Intermediate everything in Product Management, page 12
HEART Framework: Five Metrics for Product Health
HEART is a vital-signs panel for product health, not a single score. Use it to pick metrics for feature launches so you track user value, not vanity numbers. Measuring all five dimensions when only one matters creates dashboard bloat and analysis paralysis.
PPC: Buying Intent, Not Attention
PPC buys intent, not attention: you bid to appear when someone searches for what you sell, paying only if they click. Use it for high-intent offers like B2B software where organic reach is slow.
Apply AARRR to B2B SaaS vs B2C mobile game analytics
This tests mapping AARRR to instrumentation across business models. A strong answer contrasts B2B account activation and expansion against B2C session-zero funnels and whale monetization. Red flag: same metrics ignoring account hierarchies and ad attribution.
What is the difference between a metric and a KPI?
Tests strategic vs operational measurement discernment. Answer: KPIs track critical goals; metrics track processes. Page views are a metric; conversion rate is the KPI. Red flag: calling all data KPIs or using page views as success proof.
Design a self-service analytics platform for non-technical users
Tests separation of semantic modeling, UI, and query generation for safe self-service analytics. Strong answers cover a semantic layer with unified metrics, drag-and-drop UI with AST-based SQL generation, and caching.
How would you design an automated data quality monitoring system?
Tests turning data quality into tiered checks for exec dashboards. Strong answers combine freshness, volume, schema, and distribution validation with severity-based paging. Red flag: static thresholds without noise reduction or business-impact triage.
Propose a technical architecture for a centralized Metrics Layer or Metrics Store
This tests your ability to decouple metric semantics from storage and query tools. A strong answer outlines a semantic layer with versioned definitions, a query API, and enforced downstream consumption.

Design a data model for feature adoption tracking
Tests dimensional modeling for high-volume events so PMs can query Feature A not B without complex SQL. A strong answer uses an event fact table plus a materialized user-feature summary. Red flag: a wide user table with boolean columns per feature.
Explain cohort retention and write a pseudo-query for May signups
Tests cohort retention vs aggregate DAU and SQL self-joins for Week 1, 2, and 4 retention from May signups. Strong answers define cohorts by signup date, use datediff, and left-join activity. Red flag: using calendar week instead of relative signup date.

Describe dbt's role and how it differs from traditional ETL
Position dbt as ELT's T with lineage, tests, docs; contrast with Python ETL using external compute and Airflow only scheduling tasks.
Random split vs walk-forward validation in forecasting
Random splits leak future data into training; walk-forward validation rolls the origin ahead, testing only on later observations.
What is the difference between a primary metric and a guardrail metric?
Tests whether you distinguish success criteria from safety checks in experiments. A strong answer defines primary metrics as the target outcome, guardrails as protective thresholds, and gives a concrete scenario where a primary lift does not justify shipping…
What is the 'novelty effect' in experimentation?
Tests whether you separate temporary curiosity from durable value. A strong answer defines novelty effect as short-term behavior change triggered by new elements, notes it inflates early experiment lift, and proposes longer runtimes or lagged cohort analysis.
Why is stopping an A/B test at first significance problematic?
Tests peeking and Type I error inflation. Name peeking; explain daily looks inflate false positive rates above nominal alpha; note p-values assume one look at fixed sample size; recommend pre-committed runtimes or sequential testing.
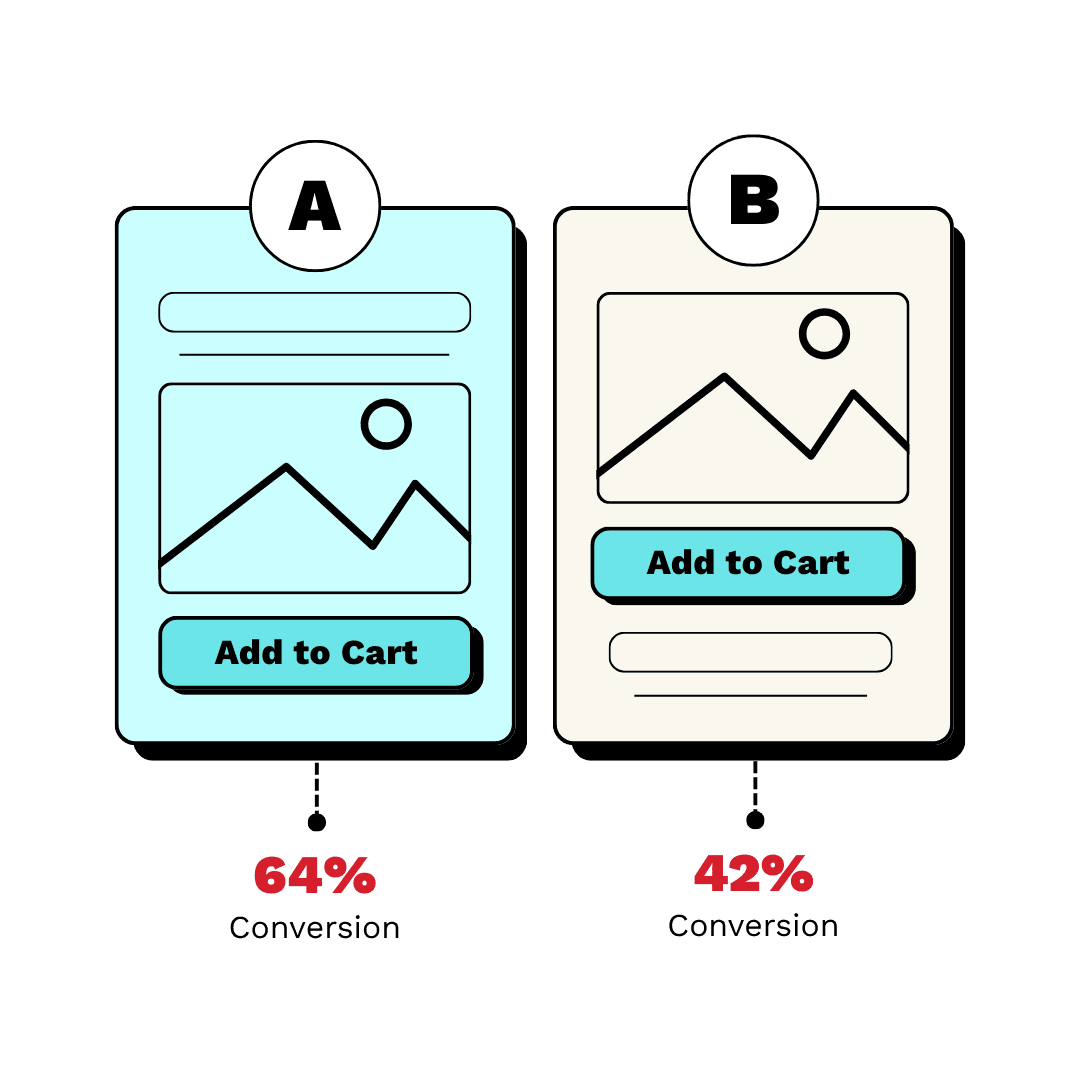
How do you determine sample size and duration for an A/B test?
This tests statistical power literacy. A strong answer names baseline rate, MDE, alpha, and beta; explains the duration versus sensitivity trade-off; and notes traffic allocation. A red flag is ignoring power or stopping early when results look significant.

Explain Simpson's Paradox and construct a user engagement scenario
Tests whether you spot trends reversing when population mixes differ. Good answers define the paradox, give a numerical example with per-segment wins but aggregate loss, and warn against segment-only decisions.
Determine if a 10% DAU drop is statistically significant
Tests signal vs noise in stable metrics. Good answers define a null hypothesis, compute a test statistic from historical variance, compare to a critical value at set alpha, and check seasonality. Red flag: calling a large drop real without baseline variance.
Explain the difference between correlation and causation with a software example.
Tests whether you distinguish association from causation to avoid blaming production issues. A strong answer defines both concepts, names a confounding variable, and gives a software example with a common cause. Red flag: claiming correlation is causation.
A/B test p-value 0.08, PM wants to ship. How do you advise?
Tests statistical rigor versus business pragmatism. A strong answer covers pre-registered thresholds, false positive risk, statistical power, confidence intervals, and the business cost of being wrong. Red flag: shipping without quantifying downside risk.
A/B test shows 5% lift with imbalanced mobile traffic. What next?
This tests sample ratio mismatch and Simpson's paradox. A strong answer says the lift is confounded by platform, demands stratified analysis to isolate the true effect, and checks randomization. A red flag is accepting the 5% lift without questioning skew.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles