Intermediate everything in Product Strategy, page 3
How would you technically evaluate a major product pivot?
Structured feasibility under uncertainty. Strong answers: define requirements and SLOs, timebox spikes to de-risk unknowns, audit architecture, data, infra, security, and team skills against thresholds.
How does product strategy influence architectural decisions? Provide a specific example.
This tests if you tie architecture to product outcomes like iteration speed. A strong answer picks patterns by company stage, cites a concrete tradeoff, and treats reliability as a product feature.
How would you evaluate investing in a complex, high-engagement feature?
This tests prioritization over gut feel. A strong answer maps the feature on a Value versus Complexity matrix, weighing business and user value against effort and risk versus alternatives. A red flag is deciding purely on feasibility or user excitement.
How do you re-evaluate roadmap and communicate an enterprise-to-SMB pivot?
Tests strategic alignment during a business model shift. A strong answer contrasts enterprise versus SMB needs, triages in-flight work by impact, and explains trade-offs with data. Red flag: cutting everything without weighing sunk cost against pivot value.
Describe artifacts and forums to align teams on API contracts and timelines
Tests API governance across teams. Propose: versioned OpenAPI specs in a shared catalog, weekly syncs, contract tests and mocks in CI, plus a joint staging environment. Red flag: Slack and meetings alone without versioned artifacts or automated validation.
Compare webhooks to sandboxed plugins for monolith extensibility
Tests distributed vs in-process extensibility. Webhooks are async, loosely coupled, and isolated but add network latency. Sandboxed plugins run in-process for low-latency UI depth yet need strict host API permissions and lifecycle gating.
Roll out a breaking change to a core public API
This tests risk management while evolving a public API contract. A strong answer covers versioning, phased deprecation with SLAs, migration tooling, and proactive communication. Red flag: proposing a hard cutover without sunset or migration support.
Design a cross-product feature flag strategy for coordinated release
This tests distributed coordination across service boundaries. A strong answer proposes a unified namespace, central config with local caches, and one user-scoped gate evaluated consistently in both products.

What pre-launch tools prevent support ticket escalations to engineering?
Tests proactive operational design versus reactive firefighting. Great answers include real-time health dashboards, automated ticket triage with user context, self-service runbooks, and escalation guardrails with pre-populated logs.

How do you technically implement an A/B test for onboarding flows?
Tests experiment pipeline design: deterministic user bucketing, an exposure event before rendering, and an event schema linking actions to variant_id. Red flag: re-randomizing per session or skipping exposure logs.
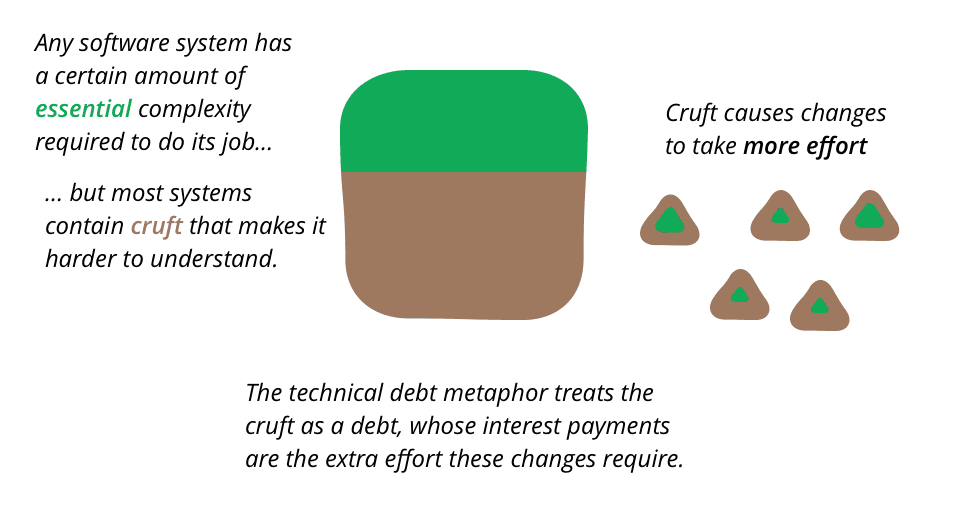
How do you justify API refactoring over new features to stakeholders?
Tests turning technical drag into business cost. Frame cruft as interest on velocity; quantify incident cost, MTTR, and lead time; advocate incremental cleanup with product work. Avoid demanding a six-month rewrite without product tie-in.
Use Cost of Delay to decide which project to start first
Tests if you quantify economic burn rate of sequencing, not raw ROI. Calculate CoD by dividing monthly value by duration: Project B is $5k/mo, Project A is $2.5k/mo, so start B first. Red flag: static NPV or "quick win" logic without computing delay cost.
Decide between cutting a feature versus taking technical debt for a deadline
Quantify business risk of both paths, secure buy-in, and lock a time-boxed post-launch remediation plan.
How would you apply RICE scoring to prioritize these three initiatives?
This tests translating technical tradeoffs into quantified RICE scores. A strong answer maps Reach to users, Impact to latency or revenue, Confidence to data quality, and Effort to person-weeks. Red flag: uniform confidence or vague t-shirt sizing.
Your feature launches but engagement doesn't move. What's engineering's role in diagnosis?
Validate data, segment users, test tech and behavioral hypotheses, propose experiments.
What artifacts and processes mitigate cross-team API dependency risks?
This tests de-risking external API dependencies via contracts. A strong answer proposes an OpenAPI spec as the source of truth, mock servers for parallel work, and automated CI validation.

Monitor p99 improvement from 500ms to 200ms and side effects
Tests systems-thinking on tail-latency instrumentation and metric tradeoffs. Strong answers cover histogram metrics, distributed tracing for fan-out bottlenecks, and guarding error rates, cost.
User session length dropped 15%: what technical issues and data to check?
Tests structured incident response. Outline: check exposure traffic, deployments, platform splits, and instrumentation bugs like dupes or bots. Red flag: blaming users before ruling out data quality or deployment changes.

Describe leading vs lagging indicators with technical performance examples.
Tests your ability to distinguish predictors from outcomes. A strong answer defines causality, offers a leading metric like cache hit rate, and a lagging metric like P99 latency. Red flag: offering only business metrics or confusing activity with outcomes.

Propose a scalable entitlement architecture for complex rules
Tests separation of hot-path reads from async policy work. Great answers: edge-cache plan tokens; stream quota usage async; isolate rules in a microservice. Red flag: doing a DB lookup or sync quota check per request.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles