Everything in AI & ML, page 33
Serverless Inference: Run ML Models Without Managing Servers
Serverless inference treats ML prediction like a function call, abstracting away servers. You pay for compute time per prediction, not for idle infrastructure.
Batch Inference: High Throughput, Not High Speed
Think of batch inference as processing a day's mail at once, not as each letter arrives. It trades immediate answers for cost-effective, high-volume predictions, like generating daily product recommendations. The footgun is using it for real-time needs.

Online Inference: Predictions on Demand
Online inference is a vending machine for predictions: you make one request and get one result back immediately. It powers real-time features like fraud detection or content moderation.
GitOps for MLOps: Your ML System as Code
GitOps for MLOps treats your entire machine learning pipeline—data, code, and models—as declarative configuration in Git. It automates ML workflows, ensuring reproducibility by making every change a reviewable commit.
Automating MLOps with GitHub Actions
Treat your ML workflow like any other CI/CD pipeline. GitHub Actions automates MLOps tasks—like training, testing, and deployment—triggered by events in your repo. Use it to run validation on PRs or deploy models on merge.
Unit Testing ML: Beyond Standard Code Checks
Unit testing for ML isn't just about code logic; it's about checking data, models, and infrastructure in isolation. Use it to validate data transformers, check model prediction shapes, or confirm a function handles nulls.
Git-Based CI Triggers: Automating on Events
Think of Git events like push or pull_request as the "play" button for your automation. This is how CI systems automatically run tests on new code. The footgun is using broad triggers, like push on all branches, which causes costly and redundant runs.
Microsoft DeepSpeed: Training Massive Models Across GPUs
DeepSpeed trains models too big for one GPU by partitioning model states across many devices. It's essential for training foundation models like BLOOM, but its complexity is overkill for smaller models and misconfiguration can harm performance.
All-Reduce: Synchronizing Parallel Workers
All-Reduce lets parallel workers agree on a global result. Each worker contributes data, an operation (like sum) runs on all data, and every worker gets the final answer. It's the core of distributed ML training, used to average gradients across GPUs.
Elastic Training: Training Models on Unreliable Hardware
Elastic Training lets ML training jobs survive worker nodes being added or removed mid-run. It's like a construction crew that adapts to a changing number of workers, making it ideal for training large models on cheap but unreliable cloud spot instances.
Slurm: The Job Scheduler for Supercomputers
Slurm is the reservation system for a shared supercomputer, queuing up jobs and assigning them to available nodes. It's the backbone of high-performance computing clusters in science and ML.
Kubeflow: MLOps on Kubernetes
Kubeflow brings the declarative, container-based world of Kubernetes to the entire ML lifecycle. It provides tools for building portable and scalable ML workflows, from development to production serving.
Ray AI Runtime (AIR): A Unified ML Toolkit
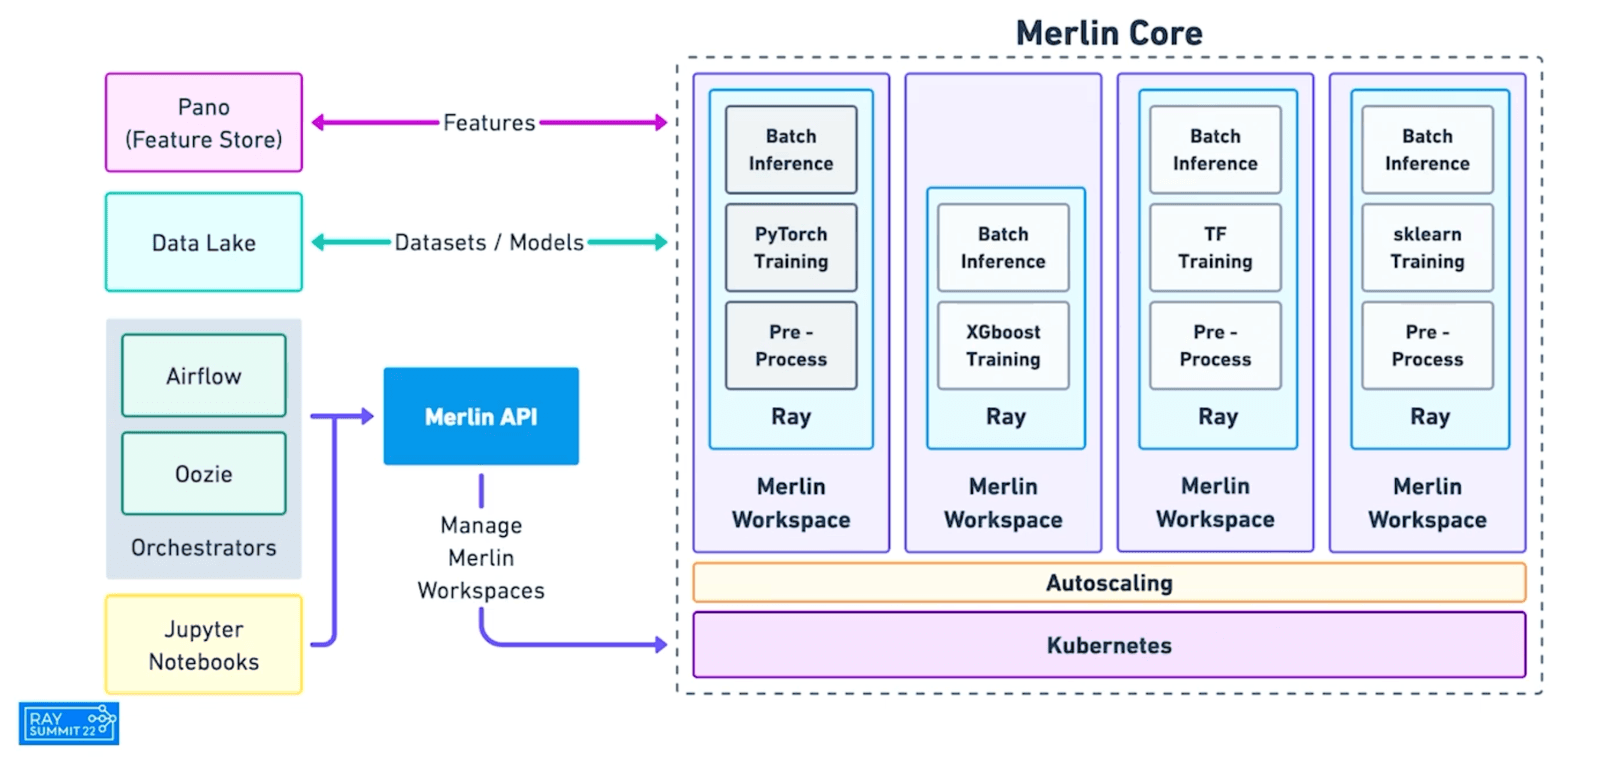
Ray AIR is a unified toolbox for the ML lifecycle, bundling libraries for data, training, tuning, and serving. It's for scaling end-to-end ML workflows on one distributed platform.
Horovod: Scale ML Training Across Many GPUs
Horovod scales a single-GPU training script to hundreds of GPUs with minimal code changes, slashing training time. It's used when models are too big for one machine.
Parameter Servers for Distributed ML Training
A parameter server splits the work in distributed training: central servers hold the model's parameters, while worker nodes pull parameters, compute gradients on data subsets, and push updates back. This enables training models too large for one machine.
Slash ML Training Costs with Spot Instances
Spot Instances are like flying standby for compute: you get a massive discount but can be 'bumped' if someone pays full price. Use them for ML training jobs that can be paused and resumed. The footgun is using them for tasks that can't tolerate interruption.
NVIDIA CUDA: General-Purpose GPU Computing
CUDA unlocks a GPU's thousands of cores for general-purpose computing, not just graphics. It's key for accelerating tasks like machine learning by running the same operation on massive datasets in parallel.
Nix: Reproducible Builds Through Functional Package Management
Nix treats system configuration like pure functional programming, ensuring reproducible builds by isolating every package into a unique, immutable path. It's used for reliable CI/CD and consistent dev environments. The footgun is its steep learning curve.
Secrets Management: Beyond Environment Variables
Treat secrets like cattle, not pets: they should be temporary and replaceable. Use a central vault to dynamically inject credentials into apps at runtime, especially in CI/CD and containerized environments.
Multi-stage Docker Builds: Lean Images, Fast Deploys
Build your app in one container stage and run it in another, separate one. This keeps your final Docker image lean by shipping only the compiled artifact, not the entire build environment, compilers, and source code.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles