Everything in AI & ML, page 41

Causal Language Modeling: The Autocomplete Engine
During each prediction, causal attention uses only the left context; a prompt can still contain a complete document, and the model can generate a continuation or answer from that prompt.
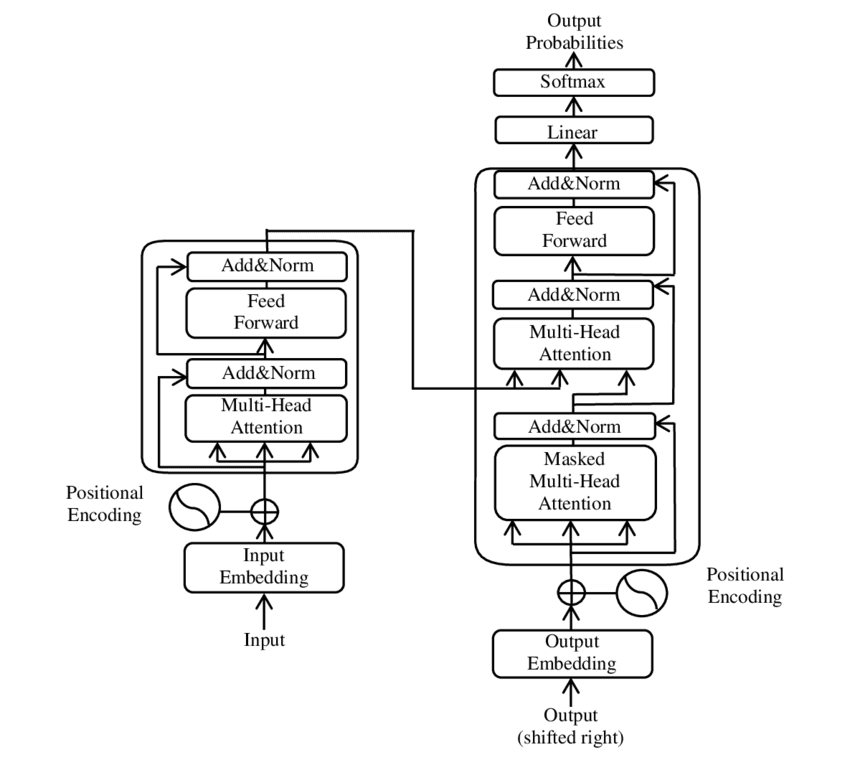
Transformer: The Final Linear and Softmax Layers
A Transformer's final linear layer acts as a classifier, converting the decoder's output vector into raw scores (logits) for every possible word. The softmax function then turns these scores into probabilities, allowing the model to pick the most likely next…
Transformer Preprocessing: From Text to Tensors
Transformers don't read text; they read numbers. A tokenizer is the translator, converting sentences into numerical tensors the model understands. This is the mandatory first step for any NLP task. The footgun is using a tokenizer that doesn't match the model.
Cross-Attention: How Models Connect Two Ideas
Cross-attention lets a model, like a translator, focus on relevant parts of an input (e.g., a sentence) to generate an output (the translation). It's used in machine translation and image captioning. The footgun is confusing it with self-attention.
Residual Connections & Layer Norm: The Transformer's Stabilizers
Residual connections are shortcuts that let information bypass layers, while Layer Normalization rescales a layer's outputs. Together, they prevent training from breaking in very deep networks like Transformers, enabling signals to flow without vanishing.
Self-Attention: The Transformer's Core Idea
Self-attention lets a model weigh the importance of different words in a sequence to understand context. This core mechanism of the transformer architecture powers LLMs for translation and generation.
Seq2Seq: Turning One Sequence Into Another
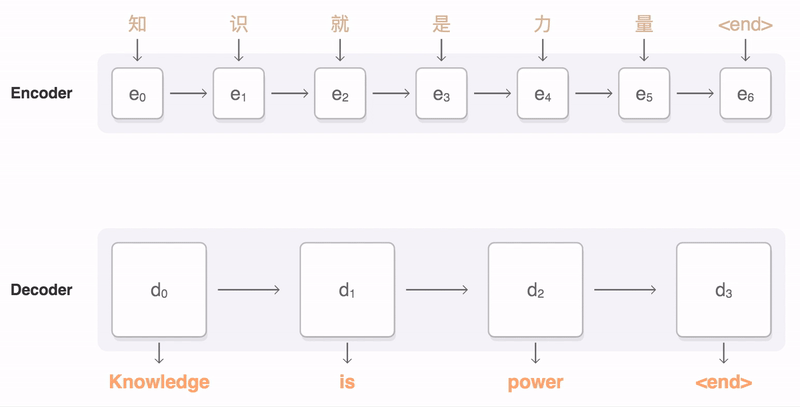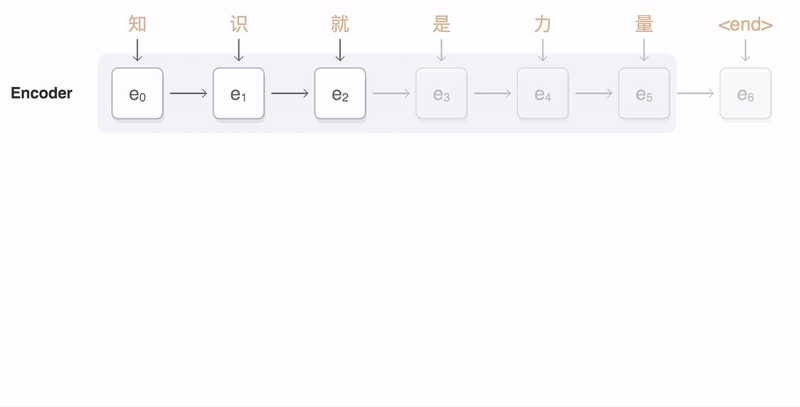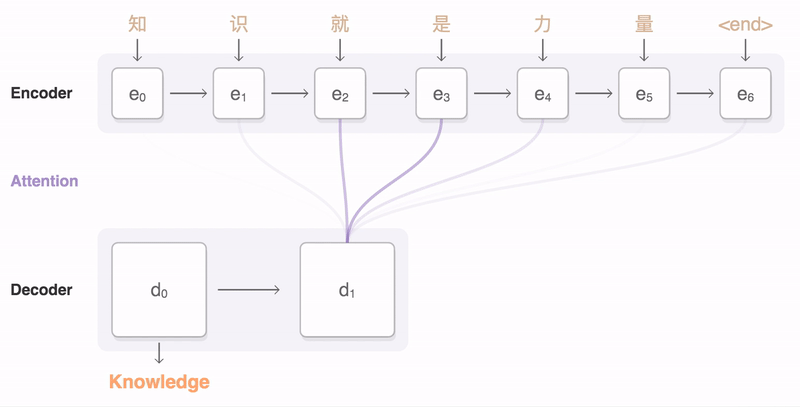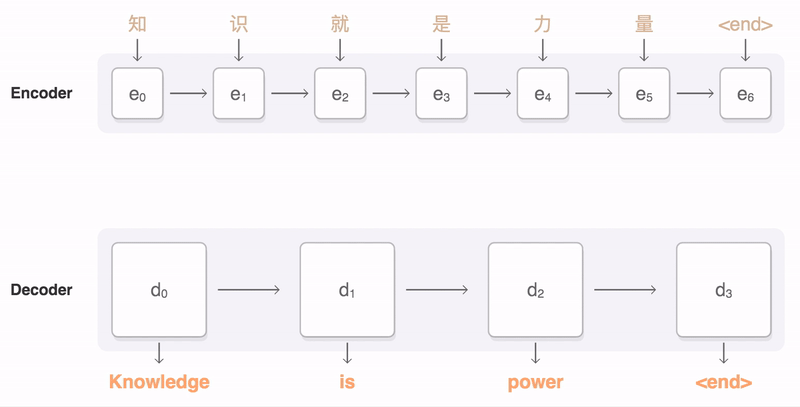
A Seq2Seq model acts like a universal translator, reading one sequence to generate another. It's foundational for machine translation and text summarization. The main footgun is its fixed-size context vector, which can forget details from long inputs.

LSTMs: Giving Neural Networks a Longer Memory
LSTMs give neural networks a longer memory, letting them connect events across long sequences. They excel at tasks like language translation or time-series analysis where distant context is key.
The Vanishing Gradient Problem
Training a deep network is like a game of telephone; the error signal (gradient) gets weaker as it's passed back through layers. This happens in deep networks using sigmoid or tanh activations.
Word2Vec: Word Meaning as a Point in Space
Word2Vec turns words into numerical vectors, where semantic similarity becomes spatial proximity. It powers synonym detection and analogy tasks by learning from a word's context in a large text corpus.

Regularization: Penalizing Complexity to Prevent Overfitting
Regularization penalizes model complexity to prevent overfitting. It's used in training to help models generalize to new data, rather than just memorizing training examples. The footgun is applying too much, causing the model to become too simple and underfit.

Activation Functions: Making Neural Networks Nonlinear
An activation function acts as a gatekeeper for a neuron, deciding what signal to pass on. It introduces non-linearity, allowing networks to learn complex patterns. A network with only linear activations collapses into a simple, less powerful model.
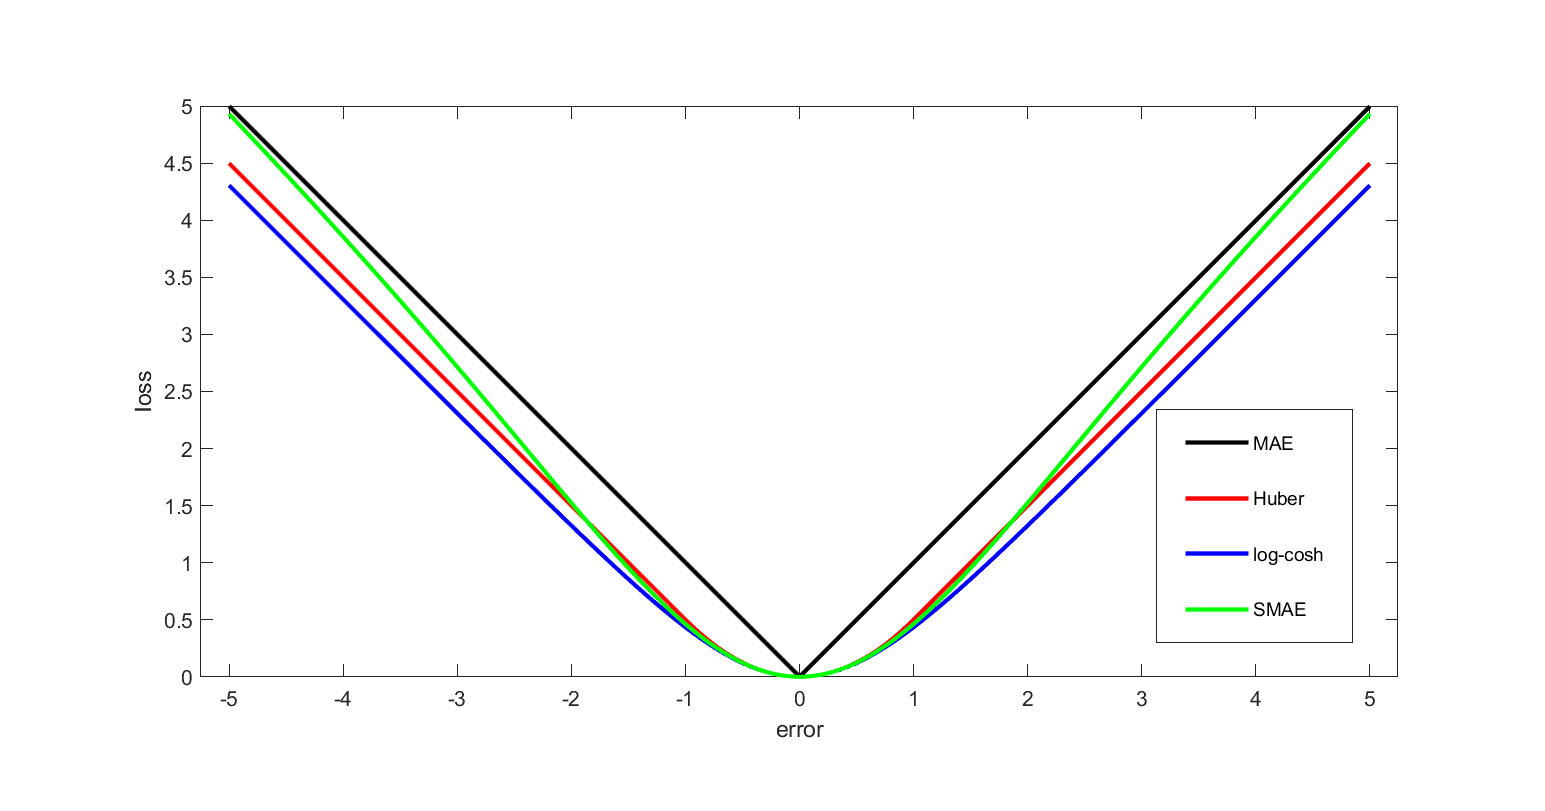
Loss Function: Quantifying 'How Wrong' a Model Is
A loss function is a score that tells a machine learning model how wrong its predictions are. The lower the score, the better. It's the engine of training, guiding the model to adjust its parameters to get closer to the correct answers.
The Big Idea: Your Presentation's Single-Sentence Core
The "Big Idea" is a single sentence distilling your presentation's core message. It must state your point of view and what's at stake, telling your audience what to know and what to do.
How a SQL SELECT Query Actually Runs
A SQL SELECT query runs in a different order than you write it. It first builds the dataset with FROM/JOINs and filters it with WHERE, only then computing the final columns in SELECT. This is crucial for debugging.
Data Sonification: Hearing Your Data's Story
Data sonification is data visualization for your ears, mapping data points to sound properties like pitch or volume. It helps find patterns in complex datasets, like network traffic, where visuals fail.
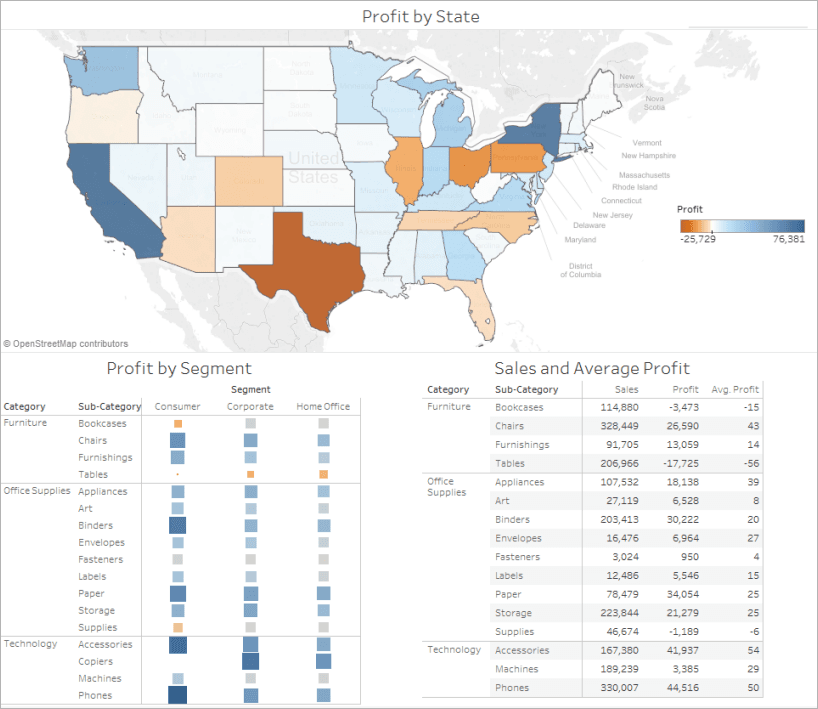
Dashboard Design: Guide, Don't Overwhelm
A good dashboard guides users to an insight, not just displays charts. Place your key takeaway in the top-left and limit views to 2-3 to maintain focus. The biggest mistake is including too many views, which clutters the message and slows down the dashboard.
Data Partitioning: Spreading Data for Scalability
Partitioning splits a huge dataset across many machines, like assigning phonebook sections to different librarians. This allows systems to scale beyond a single server.
Spark DataFrame API: SQL Smarts on Distributed Data
The DataFrame API is like giving Spark a schema for your distributed data, letting its Catalyst optimizer plan queries like a database would. Use it for structured data processing with column-based operations.
Data Pipeline Orchestration: Beyond Cron Jobs
Data pipeline orchestration is the conductor for your data workflows, ensuring tasks run in the right order with full dependency awareness. It manages complex chains, like triggering analytics only after an ETL job succeeds.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles