Advanced everything in Analytics & Metrics, page 6
Instrumental Variables: Isolating True Cause and Effect
Instrumental Variables (IV) isolate true causality when a key variable is tainted by hidden factors. An IV is a "clean" substitute that influences your cause without directly touching your effect, letting you measure the true relationship, free from…
Regression Discontinuity Design (RDD)
RDD finds a natural experiment at a cutoff point, like a test score threshold for a scholarship. By comparing people just above and below the score, you can estimate the program's effect. The footgun is assuming this local effect applies to everyone.
Isolating Impact with Difference-in-Differences (DiD)
Difference-in-Differences (DiD) isolates an intervention's true effect by comparing a treatment group's change over time to a control group's. This reveals if a new feature truly boosted engagement, not just rode a general upward trend.
Multi-Armed Bandit: The Explore vs. Exploit Trade-off
A multi-armed bandit algorithm balances exploring new options with exploiting the current winner, like a gambler trying slot machines to find the best payout.

The Multiple Comparisons Problem
Running many statistical tests on one dataset is like buying many lottery tickets; your chance of a "winning" false positive increases with each test. This happens in A/B tests with many metrics.
Bootstrapping: Quantifying Uncertainty with Resampling
Bootstrapping estimates uncertainty by resampling your own data. It's used to find confidence intervals for complex stats like medians where no simple formula exists. The footgun: it can't fix a biased sample, only reveal the uncertainty within it.
Statistical Power: Detecting Real Effects in Your Tests
Think of statistical power as your experiment's sensitivity. It's the probability of detecting a real effect, like a true lift in an A/B test. The main footgun is running a low-power test, which will likely miss a real improvement and lead you to discard good.
ANOVA: Comparing Group Averages by Analyzing Spread
ANOVA checks if group averages are different by comparing the spread *between* groups to the spread *within* them. It's used to see if three ad campaigns yield different click-through rates.
Bayesian Inference: Updating Beliefs with Data
Bayesian inference formalizes learning from experience, updating your belief in a hypothesis as you gather evidence. It's used in A/B testing and medical diagnostics. The footgun is that a poor initial belief (the prior) can skew your conclusions.
Time Series Decomposition: Separating Signal from Noise
Time series decomposition breaks a metric into its core parts: long-term trend, repeating seasonal patterns, and random noise. This helps you understand *why* a metric changed—was it a real shift or just the usual holiday rush?

Principal Component Analysis (PCA)
PCA finds the most informative axes in your data, letting you compress many features into a few "principal components." Use it to visualize high-dimensional datasets or preprocess features for machine learning, but beware: the components are hard to interpret.

Simpson's Paradox: When Averages Mislead
Simpson's Paradox is when a trend seen in separate groups reverses when you combine them. This happens when a hidden variable, like user experience level, skews the results, making a bad feature look good overall. Always segment your data to avoid this trap.
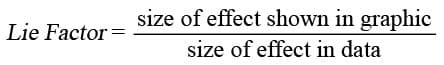
Lie Factor: Quantifying Visual Distortion in Graphs
The Lie Factor measures how much a graph's visuals distort the data's story. It's used to critique charts that exaggerate changes, like with a truncated y-axis.

Choropleth Maps: Coloring Data by Region
A choropleth map colors geographic areas to represent a metric, like shading states red or blue on an election map. It's used to show regional data like population density or sales per territory.
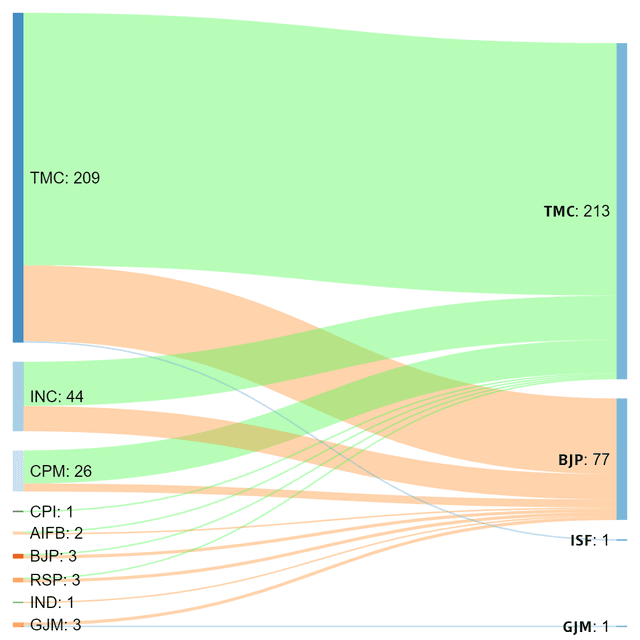
Sankey Diagram: Visualizing Proportional Flow
A Sankey diagram visualizes flow, where the width of each path is proportional to the quantity moving through it. Use it to trace user journeys or track budget allocation.

The Narrative Arc for Data Storytelling
A narrative arc gives data a story by building tension toward a key insight. It guides stakeholders from a problem (plot) to a turning point (climax) and a resolution. The footgun is oversimplifying; compelling stories have multiple smaller tension peaks.
The Semantic Layer: A Business Map for Company Data
A semantic layer is a translation dictionary for data, mapping cryptic database columns to plain business terms like "Revenue." It lets non-technical teams build reports without writing SQL.
Exception Reporting: Focus on Signals, Not Noise
Exception reporting filters out the noise, showing only data that breaks predefined rules. It's used in financial reconciliation to flag mismatched transactions or to alert on system performance dips.
Benchmarking: Know Where You Stand in Your Industry
Benchmarking answers "Are we good?" by comparing your performance metrics against industry bests. It's used to set realistic goals for cost, quality, or time. The main footgun is comparing apples to oranges—using benchmarks from dissimilar companies.
Data Masking: Protect Data, Preserve Utility
Data masking creates a realistic but fake version of your data by scrambling sensitive fields. It's used to give developers and analysts safe datasets for testing or analytics without exposing real PII.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles