Intermediate everything in Analytics & Metrics, page 4
Design a CDC pipeline that handles schema evolution gracefully
Tests designing resilient CDC pipelines against schema drift. A strong answer covers schema registries with versioning, backward-compatible serialization, and automated compatibility checks.
How would you implement data lineage for microservices analytics?
Tests end-to-end provenance tracking, not just docs. Strong answers cover automated metadata capture at service boundaries, a central catalog such as DataHub or OpenLineage, and column-level tracing.
What is data partitioning in a cloud data warehouse?
Tests physical data layout and cost/performance tradeoffs. Strong answers define time-based or integer-range partitioning, explain partition pruning avoids full scans, and warn against high-cardinality keys.
How would you handle late-arriving data in a streaming analytics pipeline?
Tests understanding of event-time processing, watermarks, and windowing for correctness. A strong answer covers watermarks with allowed lateness, event-time triggers, and idempotent updates to sinks.
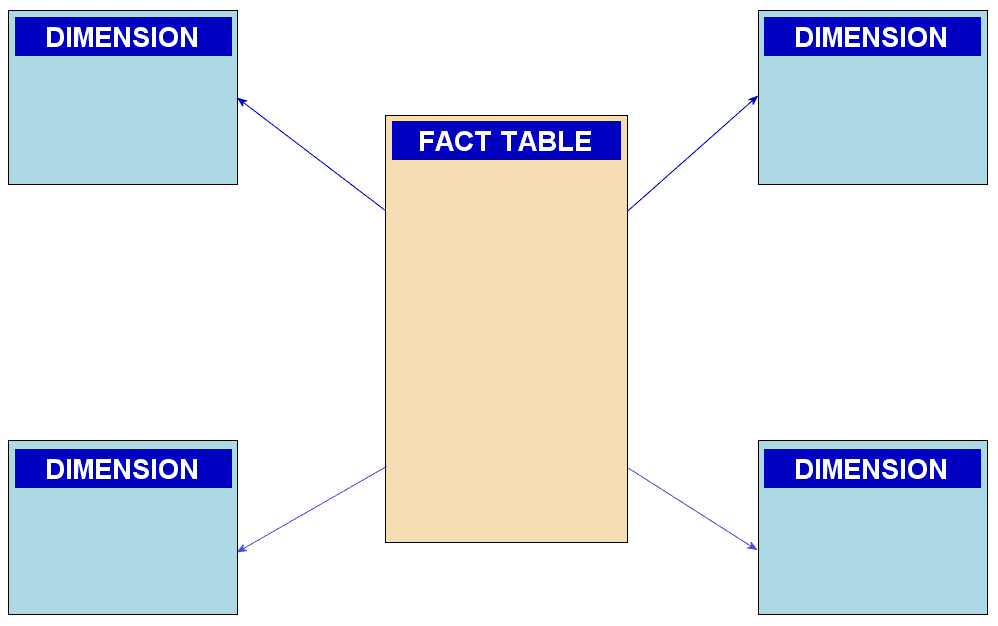
Describe star and snowflake schemas and their trade-offs
Star schemas flatten dimensions for fast joins; snowflake schemas normalize hierarchies to reduce redundancy but add joins.
How do you approach user identity stitching across devices?
Tests cross-channel identity resolution design. Strong answers capture a persistent anonymous ID per device, rekey to a person ID at login via field-based or graph-based stitching, and respect consent.
Trade-offs: third-party analytics SDK versus in-house pipeline
This tests strategic build-versus-buy judgment for data infrastructure. Strong answers weigh time-to-market, maintenance burden, data sovereignty, and compliance against core product focus.
Conversion metric dropped suddenly with no recent deployments; debug instrumentation causes
Distinguishing real regressions from telemetry pipeline failures. Segment by device, channel, and geography to spot uniform loss signaling a tagging break; verify vendor delays and sampling; check for consent or ad-blocker shifts.

How do you track page views in a Single Page Application?
This tests SPA analytics beyond classic page loads. A strong answer covers History API pushState and popstate events, framework router hooks like useEffect or afterEach, and beaconing views. A red flag is relying only on window.load or polling URL changes.
How do you diagnose why a new feature's adoption is flat?
Tests structured analytics thinking across the adoption funnel. A strong answer maps discovery to habituation, segments cohorts, pairs behavior with feedback, and validates via experiments. Red flag: blaming UI without proving users know the feature exists.
Pitfalls of using conversion rate as a checkout North Star?
Tests if you know over-optimizing conversion can degrade revenue quality or trust. Strong answers cite lower AOV or fraud risks, then list guardrails like refund rate, lifetime value, and checkout errors. Red flag: insisting conversion is the sole metric.
Define and calculate Weekly Active Users (WAU) for Slack
Tests translating a business metric to a technical spec. Define 'active' by key actions (sending messages, not just opening), then COUNT(DISTINCT user_id) on an events table, filtering out bots and background syncs. A red flag is a generic definition.

When is an A/B test not feasible, and what is DiD?
This tests your grasp of causal inference when randomization isn't possible. Explain a scenario like a state-level launch, introduce Difference-in-Differences (DiD), and state its core parallel trends assumption.
Determine Sample Size for a 2% Lift A/B Test
This tests your grasp of statistical power and the business trade-offs in experimentation. A great answer defines baseline conversion rate, minimum detectable effect (MDE), and statistical power. A red flag is ignoring the business context of MDE.
Design a Schema Validation System for Analytics Events
Tests your grasp of data quality engineering, client/server trade-offs, and failure design. A good answer defines a Tracking Plan, enforces it on both client and server, and handles failures by blocking or forwarding with violation flags.

Calculate Monthly Recurring Revenue (MRR) with SQL
This tests your ability to translate a business metric into a robust SQL query, handling time-series logic. A good answer filters for active subscriptions, sums the price, and correctly amortizes annual plans. A red flag is using incorrect date filtering.
What is a p-value, and what does 0.03 practically mean?
This tests your ability to translate stats into business decisions. A great answer defines p-value, compares 0.03 to the standard 0.05 threshold to reject the null hypothesis, and recommends shipping.
How do you handle timezones for a global daily sales report?
This tests your ability to translate ambiguous business needs (a "day") into a robust data model. First, clarify the business definition of a day. Then, store all event times in UTC and convert to the target timezone at query time for reporting.
Implement CDC from an OLTP database to a data warehouse
This tests your grasp of production system trade-offs. A good answer compares log-based and trigger-based CDC, focusing on source impact and data fidelity, then recommends log-based for its low overhead.
Propose a multi-touch attribution model and its data pipeline
This tests your ability to choose a practical data model under real-world constraints. Propose a time-decay or position-based model, then describe the data pipeline: event collection, identity resolution, and aggregation. A red flag is ignoring signal loss.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles