Easy concepts in Computer Vision

Digital Images as Grids of Pixels
Think of a digital image as a mosaic of tiny colored tiles called pixels. This 'raster' method stores the exact color of each point, making it perfect for photos. The footgun: scaling up reveals the grid, causing blurriness or pixelation.

Pinhole Camera Model: Projecting 3D to 2D
The pinhole camera model is a simple formula for how a 3D world flattens into a 2D image. It's the basis for 3D reconstruction and augmented reality, relating an object's real-world position to its pixels.
RGB Color Model: Mixing Light, Not Paint
Think of RGB as mixing colored spotlights. Red, green, and blue light are added together to create the colors on your screen. The main footgun is confusing this with print's subtractive model, where mixing colors makes black, not white.
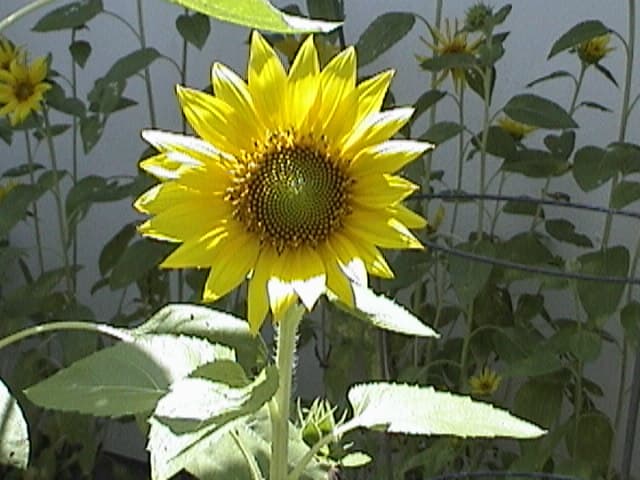
Image Histograms: Visualizing an Image's Tonal DNA
An image histogram is a bar chart of an image's brightness, showing pixel counts from pure black to pure white. It's used in photo editing to instantly judge exposure, revealing clipped shadows or blown highlights.
Grayscale Conversion: Seeing in Shades of Gray
Grayscale conversion simplifies an image by removing color, representing each pixel's brightness as a single value. It's a key preprocessing step in computer vision for tasks like OCR, where shape matters more than color.

Image Scaling: Resizing Pixels Without Ruining Them
Image scaling isn't just stretching a picture; it's inventing or discarding pixel data. It's used everywhere from displaying thumbnails to making 1080p video fit a 4K screen.
Histogram Equalization: Spreading Out Pixel Brightness
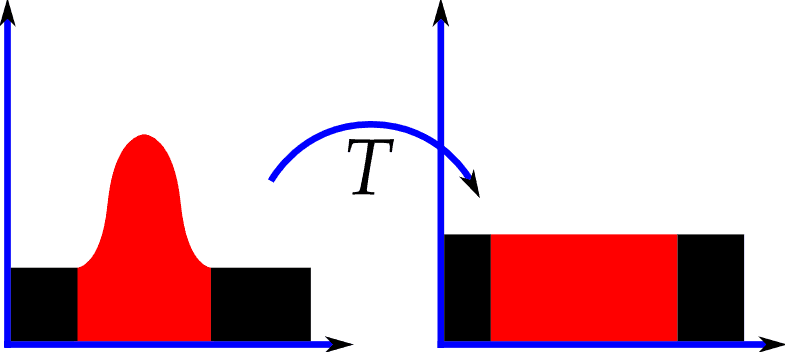
Think of histogram equalization as automatically stretching an image's contrast. It takes dark or washed-out images and spreads their pixel brightness values across the full available range, revealing hidden details. The footgun: it can amplify noise.
Harris Corner Detector: Finding Sharp Changes in Images
The Harris detector finds corners by looking for points where image intensity changes sharply in all directions. It's used in image stitching and object tracking to find stable feature points. A key weakness is its sensitivity to image scale.
Corner Detection: Finding Stable Points in Images
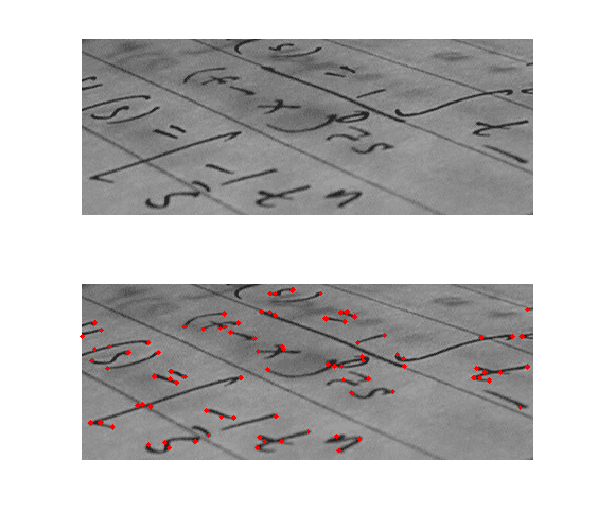
Corner detection finds stable reference points in an image by looking for areas where pixel intensity changes sharply in multiple directions. It's used to track objects in video, stitch panoramas, and recognize objects by their features.
Hough Transform: Finding Shapes by Voting
The Hough Transform finds shapes by letting pixels "vote" for all lines or circles they could belong to. It's used to detect features like road lanes in noisy images.

Epipolar Geometry: Finding 3D Points from 2D Images
Epipolar geometry finds a 3D point from two 2D views by constraining the search. Instead of scanning the whole second image for a match, you only look along a single line. It's key for 3D reconstruction. The footgun is assuming perfect pinhole cameras.
The Stereo Correspondence Problem: How Cameras See in 3D
The stereo correspondence problem is how computers see in 3D, like your two eyes. It involves matching the same point in a left and right image to calculate depth. This is key for self-driving cars and robotics. The footgun: textureless walls create ambiguity.
Disparity Map: Seeing Depth from Two 2D Images
A disparity map is a grayscale image encoding 3D depth from two 2D images. Brighter pixels mean objects are closer, because they appear to shift more between the left and right camera views. This is key for robotics and autonomous navigation.
Point Cloud: A 3D Shape as a Dust Cloud of Data
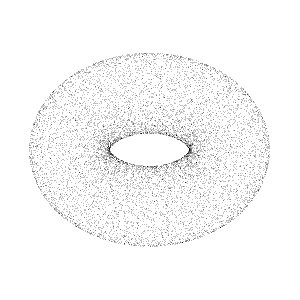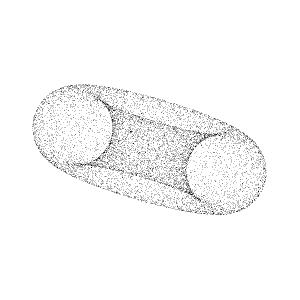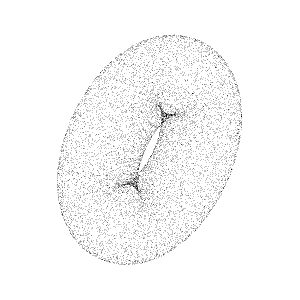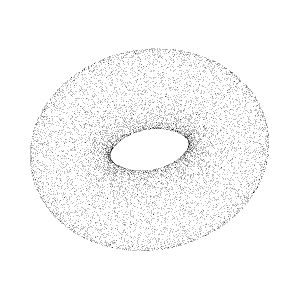
A point cloud represents a 3D object as a cloud of individual data points in space. It's the raw output from 3D scanners, used to create CAD models or GIS maps. The footgun is assuming it's a solid model; it has no surfaces, only disconnected.
Convolutional Layers: Finding Features Anywhere
A convolutional layer is like a flashlight sliding over an image, looking for a specific pattern like an edge or corner. It's the core of computer vision, letting networks find features anywhere.
Feature Maps: What a Neural Network 'Sees'
A feature map is the output of a filter in a neural network, highlighting where a specific pattern (like an edge or curve) appears. In CNNs, each layer generates dozens of these maps. The footgun is thinking one map sees an object, not just a.
Pooling Layers: Summarizing What Matters in an Image
A pooling layer is like squinting at an image; you lose fine detail but see the main shapes. It summarizes features in a region, reducing computation and making the model robust to small shifts.
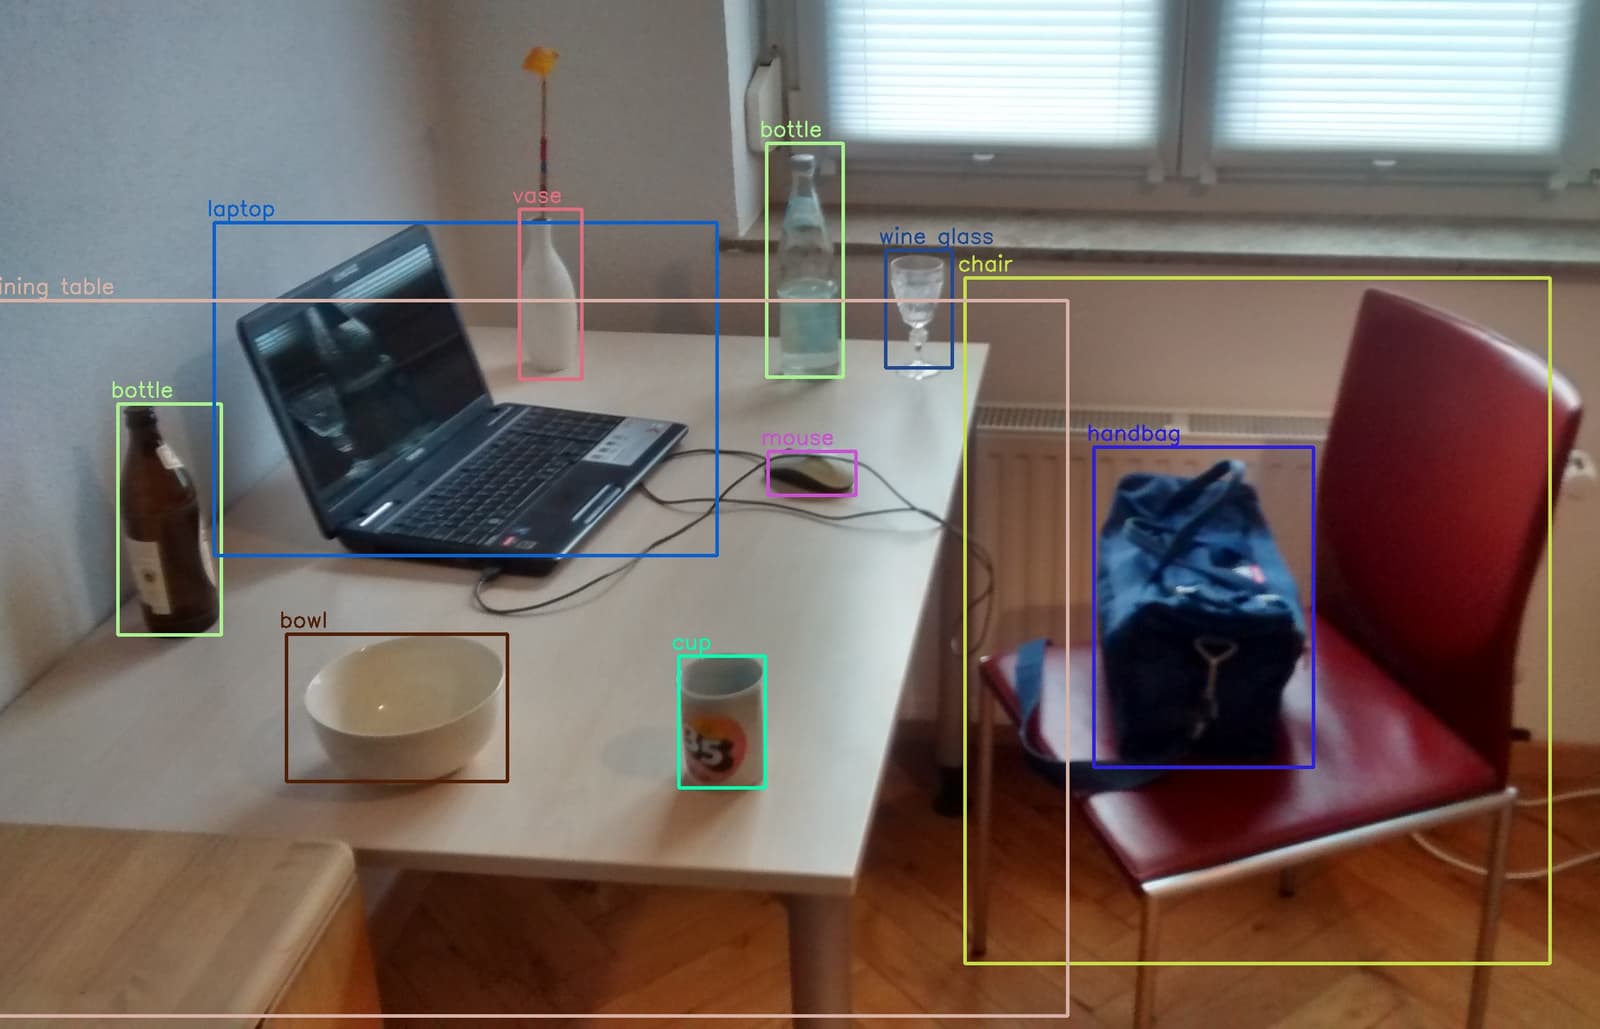
Localization vs. Detection: One Box or Many?
Object localization draws one box around an image's main object. Object detection finds and boxes *every* instance of a class, like all pedestrians. Use localization for single-subject tasks, detection for finding everything.
Intersection over Union (IoU): How Good is Your Bounding Box?
Intersection over Union (IoU) scores how well a predicted box matches the real one by dividing their overlap area by their total area. It's vital for object detection in self-driving cars and medical imaging.
Frame Differencing: The Simplest Way to See Motion
See motion by subtracting one video frame from the next; what's left over is what moved. This is used for simple motion detection but is easily fooled by lighting changes or camera shake, which it misinterprets as movement.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles