Concepts in Computer Vision, page 3
The Essential Matrix: Geometry for Stereo Vision
The Essential Matrix is a geometric bridge between two photos of the same scene, encoding the camera's relative motion. It's used in 3D reconstruction to find corresponding points; it tells you where a point from one image must lie in the other.
Triangulation: Finding 3D Points from 2D Images
Like your two eyes judging distance, triangulation finds a point's 3D location by seeing it from two different 2D camera views. It's key for 3D reconstruction and robotics.
Structure from Motion (SfM): Rebuilding 3D from 2D Photos
Structure from Motion (SfM) reconstructs a 3D scene from 2D images taken from different viewpoints, much like your brain perceives depth. It's used for creating 3D maps from drone footage. The main footgun is its failure on textureless or reflective surfaces.
Eight-Point Algorithm: Finding Geometry from Image Pairs
The Eight-Point Algorithm finds the geometric relationship between two camera views of the same scene. Given at least eight matching points, it estimates the essential or fundamental matrix.
Bundle Adjustment: Jointly Refining 3D Scenes and Cameras
Bundle adjustment is a grand negotiation, simultaneously refining a 3D scene, camera poses, and lens properties to best explain the 2D images. It's the final polish in Structure from Motion (SfM) or SLAM.
SLAM: Mapping a Room While You're Still In It
SLAM solves a chicken-and-egg problem: you can't map a space without knowing your location, and you can't know your location without a map. It does both at once. It's used by robots and AR headsets to navigate.
Convolutional Layers: Finding Features Anywhere
A convolutional layer is like a flashlight sliding over an image, looking for a specific pattern like an edge or corner. It's the core of computer vision, letting networks find features anywhere.
Feature Maps: What a Neural Network 'Sees'
A feature map is the output of a filter in a neural network, highlighting where a specific pattern (like an edge or curve) appears. In CNNs, each layer generates dozens of these maps. The footgun is thinking one map sees an object, not just a.
Pooling Layers: Summarizing What Matters in an Image
A pooling layer is like squinting at an image; you lose fine detail but see the main shapes. It summarizes features in a region, reducing computation and making the model robust to small shifts.

ReLU: The 'On/Off' Switch for Neural Networks
ReLU acts as a simple on/off switch for neurons: positive inputs pass through, negative ones become zero. It's the default activation in deep learning, especially for vision tasks, as it's fast and helps gradients flow. The footgun: neurons can "die".
Cross-Entropy Loss: How Wrong Is Your Model's Guess?
Cross-entropy loss measures the penalty when a model's predicted probabilities diverge from the true labels. It's the standard loss for classification tasks, like telling a cat from a dog.
Backpropagation: How Neural Networks Learn from Mistakes
Backpropagation is how a network learns from its mistakes. It works backward from the output error, calculating how much each weight contributed and adjusting it. This is the core training loop for most deep learning models.
Data Augmentation: Getting More Images for Free
Data augmentation creates "fake" training data by modifying existing images—flipping, rotating, or color-shifting them. This fights overfitting when your dataset is small, forcing the model to generalize.
Dropout: Forcing a Network to Generalize
Dropout prevents overfitting by randomly zeroing out a fraction of neurons during training. This forces the network to learn more robust features instead of relying on specific neurons. It's a standard regularizer for large, dense layers.

AlexNet: The CNN That Sparked the Deep Learning Boom
AlexNet is the blueprint that proved deep CNNs could master image recognition, kicking off the modern AI boom. Its architecture is foundational for modern computer vision. The footgun is thinking it was just bigger; its novelty was combining new techniques.
Batch Normalization: Stabilizing Neural Network Training
Batch Normalization regulates data flow in a neural network by re-centering and re-scaling inputs to each layer. This stabilizes deep network training, allowing higher learning rates.
Residual Networks (ResNets): Go Deeper, Not Worse
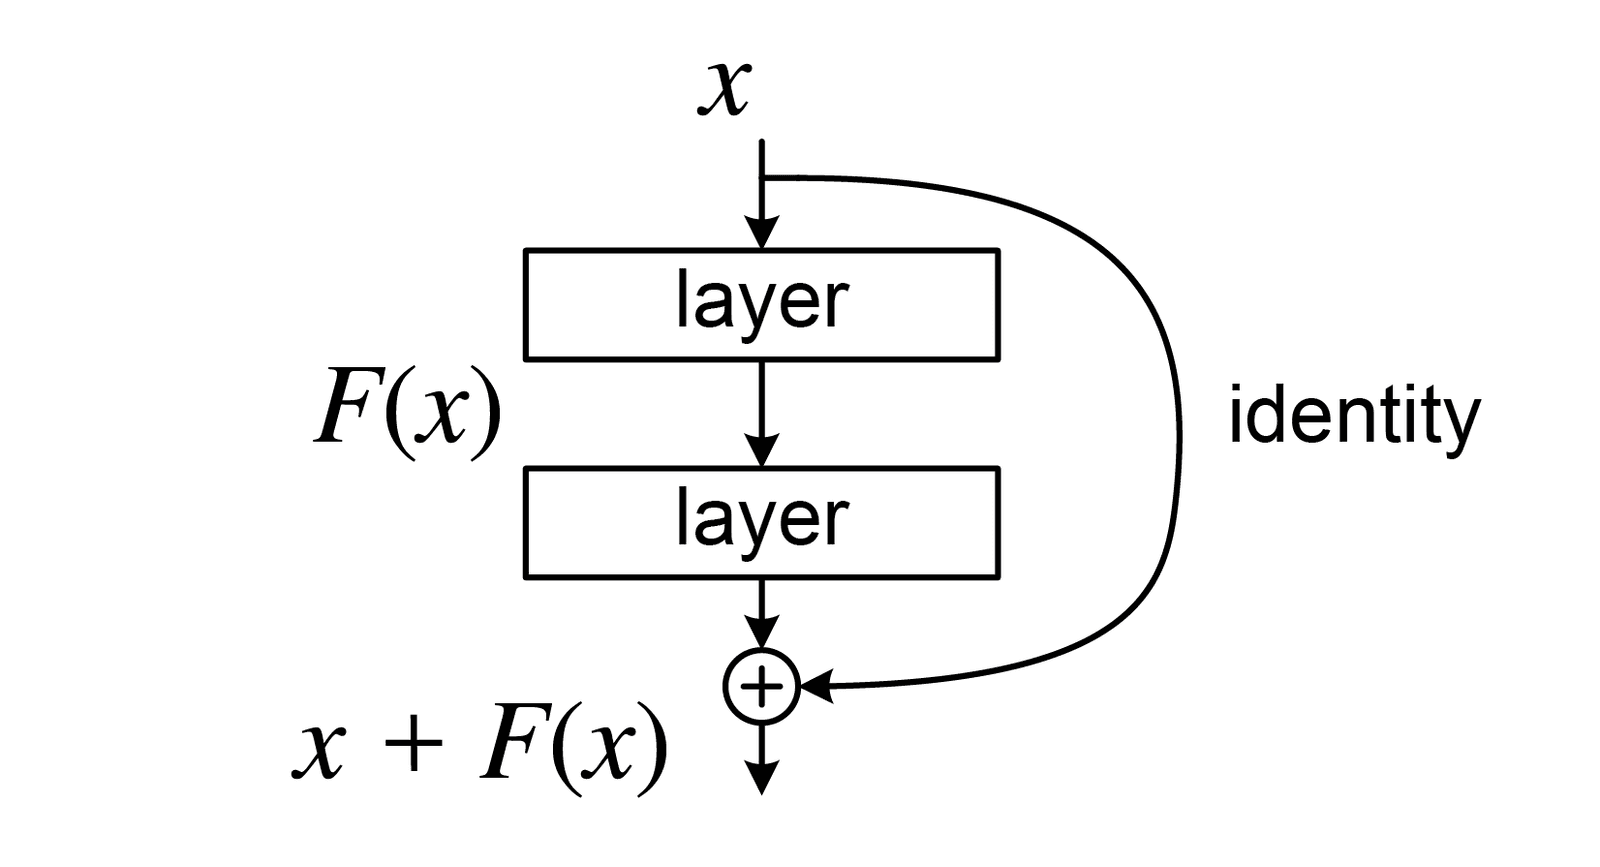
ResNets let you train extremely deep networks by learning what to *change*, not the entire output. They use 'skip connections' to bypass layers, which helps solve accuracy degradation in deep vision models. The footgun is thinking deeper is always better.
GoogLeNet's Inception Module: Wider, Not Just Deeper
Instead of choosing one filter size, GoogLeNet's Inception module runs 1x1, 3x3, and 5x5 convolutions in parallel. This lets the network capture features at multiple scales at once. The footgun is forgetting the crucial 1x1 'bottleneck' convolutions.

Transfer Learning: Don't Train Vision Models from Scratch
Don't train a vision model from scratch. Transfer learning reuses a model trained on a huge dataset (like ImageNet) as a starting point for your specific task. This lets you achieve high accuracy on new image types with much less data and compute.
Localization vs. Detection: One Box or Many?
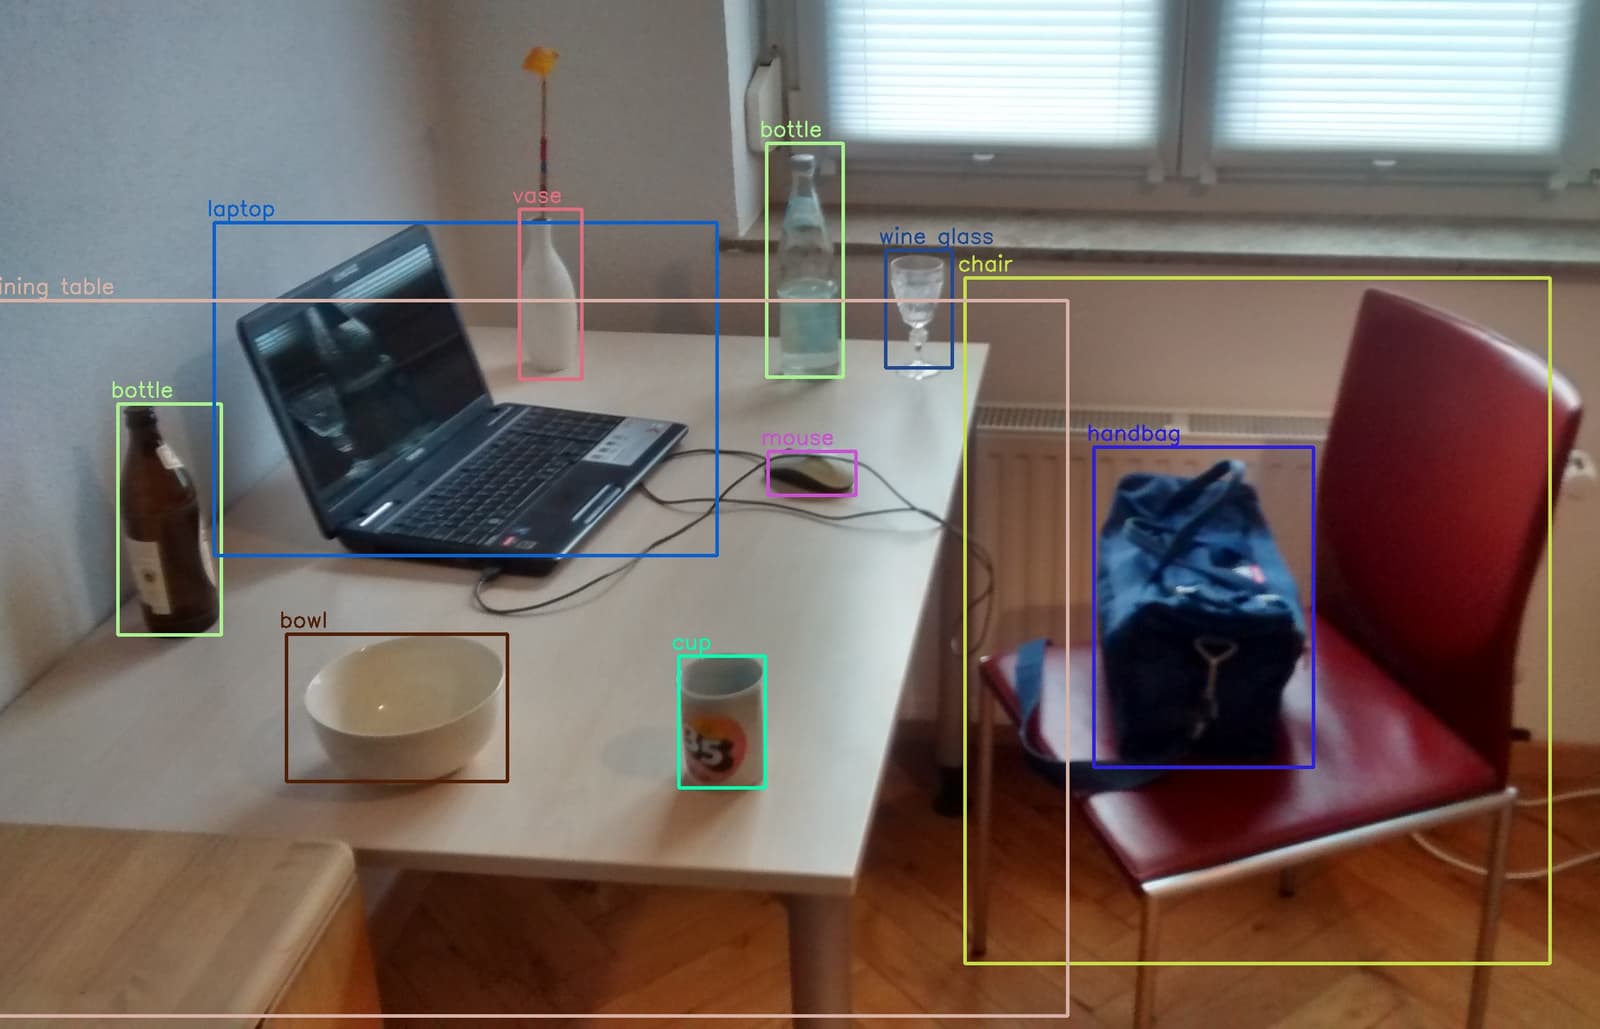
Object localization draws one box around an image's main object. Object detection finds and boxes *every* instance of a class, like all pedestrians. Use localization for single-subject tasks, detection for finding everything.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles