Concepts in LLMs & Generative AI, page 2
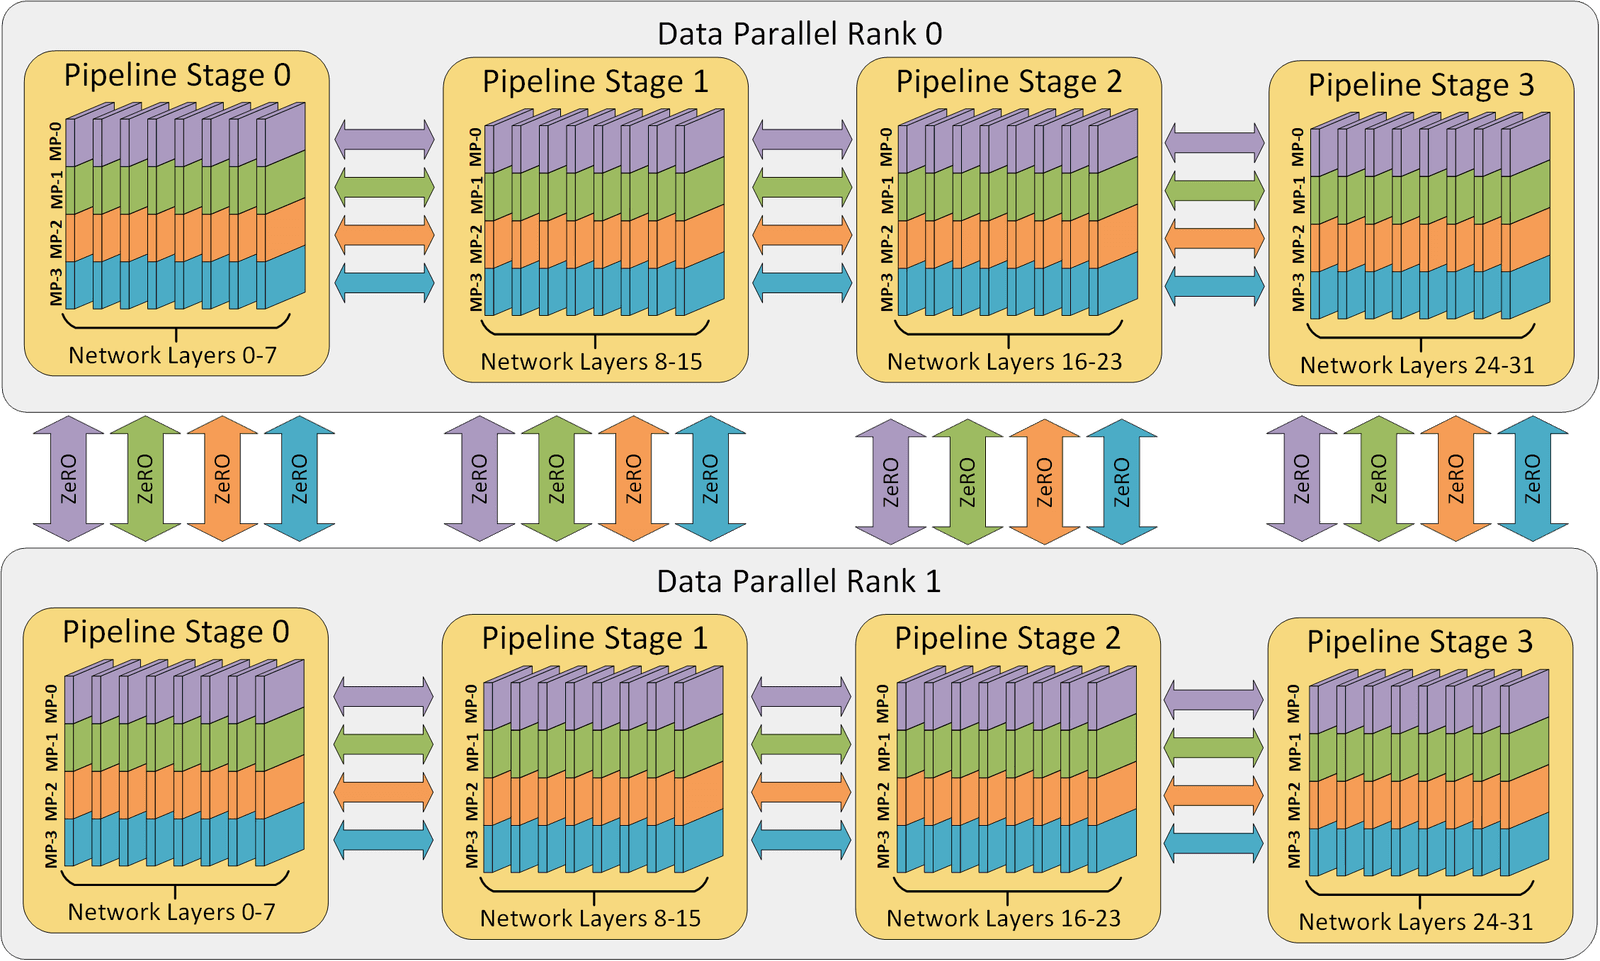
Pipeline Parallelism: An Assembly Line for Your Model
Think of training a huge model like an assembly line. Pipeline parallelism splits a model's layers into stages across multiple GPUs, allowing you to train models too large for one device.

Tensor Parallelism: Split Layers, Not Just Models
Tensor Parallelism splits a single large model layer, like a weight matrix, across multiple GPUs to run in parallel. This is crucial for inference with models whose layers exceed a single GPU's VRAM.
Prompt Engineering: Guiding LLMs to Better Answers
Prompt engineering means structuring instructions, context, constraints, and examples to make a model's output more useful for a task. For example, asking for JSON with a schema and one valid example can improve format consistency, but prompting alone cannot guarantee accuracy.
Zero-Shot Prompting: Ask, Don't Show
Zero-shot prompting is asking an LLM to do a task without examples, relying on its pre-existing knowledge. Use it for simple tasks like basic translation or sentiment analysis where instructions are self-explanatory, but expect it to fail on complex tasks.

In-Context Learning: Teaching a GPT Without Retraining
In-context learning is like giving an LLM a cheat sheet in the prompt. You provide examples of a task, and the model follows the pattern for your new query without any permanent changes. Use it for one-off tasks like reformatting text or classifying sentiment.
Few-Shot Prompting
Few-shot prompting embeds task examples directly in the prompt to guide output format without retraining. It excels at niche tasks and consistent formatting, but mismatched examples degrade performance more than no examples at all.
Chain-of-Thought Prompting: Making LLMs 'Show Their Work'
Chain-of-Thought (CoT) prompting gets better answers from LLMs by asking them to 'show their work.' It's best for complex reasoning like math problems or logic puzzles where breaking the problem down helps.
Least-to-Most Prompting: Solving Hard Problems Incrementally
Least-to-most prompting guides an LLM by breaking a hard problem into a sequence of simpler steps. It excels at complex math or logic where chain-of-thought fails, solving each subproblem using the answer to the previous one.
Self-Consistency: Majority Rules for LLM Reasoning
Self-consistency makes an LLM solve a problem multiple ways, then picks the most common answer. It's like asking a committee of experts for their reasoning and taking a vote. This boosts accuracy on complex math and logic puzzles.
Tree of Thoughts: LLM Reasoning Beyond a Single Path
Tree of Thoughts (ToT) lets an LLM explore multiple reasoning paths at once, like a human brainstorming. It generates several 'thoughts' and pursues the most promising ones. This is crucial for planning tasks where one wrong turn fails.

ReAct: Teaching LLMs to Think, Act, and Observe
ReAct teaches an LLM to solve problems by interleaving thought, action, and observation. This is key for agents that search the web or query APIs to answer questions with external data.
Supervised Fine-Tuning (SFT): Teaching a Model to Chat
Supervised Fine-Tuning (SFT) teaches a general LLM to be a helpful assistant by training it on high-quality conversations. This turns a base model into an instruction-following chatbot.
Catastrophic Forgetting: The AI's Amnesia Problem
Catastrophic forgetting is when an AI, trained on new information, abruptly forgets what it previously knew. It's like overwriting a file instead of appending to it. This happens when fine-tuning a model on a narrow dataset, erasing its general knowledge.
PEFT: Fine-Tune Large Models on a Budget
Parameter-Efficient Fine-Tuning (PEFT) adapts huge models without retraining everything. It's like adding a task-specific cheat sheet to a genius brain. Use it to specialize LLMs on consumer GPUs.
Instruction Fine-Tuning: Teaching LLMs to Follow Orders
Instruction fine-tuning teaches a base LLM to follow commands, not just predict the next word. It turns a raw text-completion engine into a helpful assistant, enabling it to answer questions or summarize text. The footgun: it learns style, not facts.
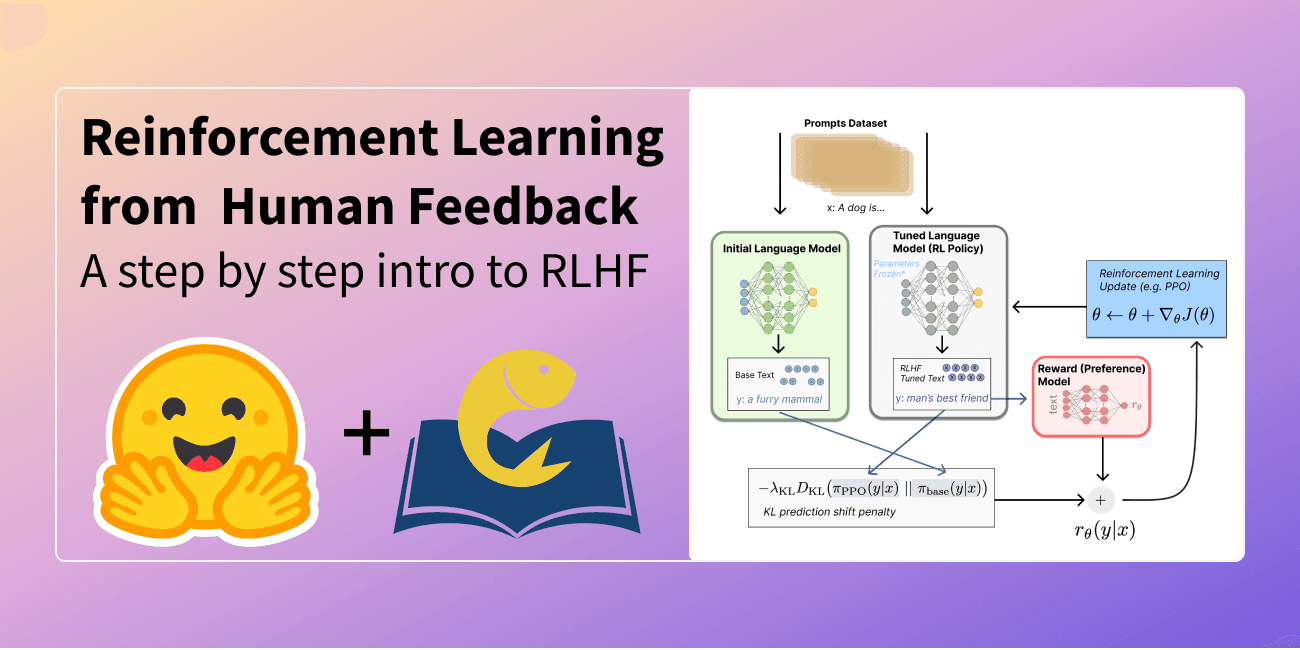
Reward Modeling: Teaching an LLM What 'Good' Means
A reward model is a judge that scores an LLM's outputs based on human preferences. It learns to assign a numerical 'goodness' score to text, turning subjective quality into an optimizable signal for training models like ChatGPT.
Adapter Modules: Efficient LLM Fine-Tuning
Adapters are small modules plugged into a frozen LLM to avoid costly full fine-tuning. This lets you specialize a base model for many tasks by training tiny, swappable plugins instead of duplicating the entire model for each task.
Proximal Policy Optimization (PPO): Stable RL Updates
PPO prevents destructive updates in reinforcement learning by "clipping" how much a policy can change at once, like a governor on an engine. It's a default for training LLMs with RLHF or robotics agents where stability is key.
QLoRA: Finetune Huge LLMs on a Single GPU
QLoRA lets you finetune massive LLMs on one GPU by freezing the model in a 4-bit state and only training tiny adapter layers. Use it to adapt a 65B model with limited hardware. The footgun: performance hinges on high-quality data, not just the technique.
Embedding Models: The 'Retrieval' in RAG
An embedding model acts like a librarian for your data, converting text into numerical vectors so similar concepts are grouped together. In RAG, it finds relevant documents to feed an LLM, but using the wrong model type will yield poor retrieval results.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles