Intermediate concepts in MLOps & Infrastructure
ML Experiment Tracking: Your Model's Lab Notebook
Think of it as a lab notebook for your models, logging every parameter and result. It's essential when tuning hyperparameters or comparing architectures, preventing you from losing track of what worked.
Data Versioning: Git for Your Datasets
Think of data versioning as Git for datasets. It tracks changes to your data, allowing you to reproduce ML experiments or roll back to a previous state. The footgun is using regular Git, which chokes on the large binary files common in ML.
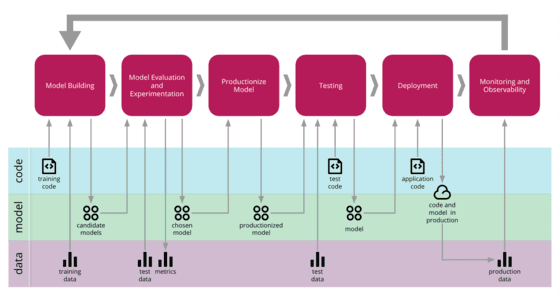
CD4ML: Automating ML from Data to Deployment
CD4ML extends CI/CD to manage ML's three axes of change: code, data, and models. It automates the entire lifecycle, enabling reliable updates for systems like sales forecasting.
ELT: Load Raw Data, Transform in Place
ELT flips the data pipeline: load raw data first, then use the data warehouse's own power to transform it. It's used in ML feature pipelines. The footgun is assuming it's ETL; with ELT, the transformation logic is coupled to the warehouse's SQL engine.
Data Schema Evolution: Changing Your Data's Blueprint
Schema evolution is like updating a building's blueprint while it's occupied. You must change your data's structure without breaking apps or losing data. It's key for adding features that need new DB columns.
Great Expectations: Unit Tests for Your Data
Great Expectations brings unit testing to your data, letting you assert what a dataset should look like. It validates data within a pipeline, preventing bad data from corrupting models or reports.
DVC: Git for Data and ML Models
DVC extends Git to version large data files and models without bloating your repo. It stores small pointer files in Git that reference large files in cloud storage.
Data Augmentation: Getting More from Your Data
Data augmentation creates 'new' training data by making small, realistic changes to your existing data. It's used to fight overfitting in ML models when a dataset is small, teaching the model to generalize rather than memorize.
Feature Hashing: The Hashing Trick for ML
Feature hashing turns features into vector indices without a lookup table, trading perfect accuracy for speed and memory. It's used for high-cardinality data like user IDs or in online systems.

Online vs. Offline Feature Serving: Two Speeds for ML Data
Offline serving provides large batches of historical data for model training; online serving provides low-latency features for live predictions. This dual system in a feature store prevents training-serving skew, ensuring model consistency from lab to…

Feature Backfilling: Populating Historical Data for ML
Feature backfilling computes a new feature's values for historical data. It's how you generate a complete training dataset after defining a new signal, like a user's 7-day purchase history. The footgun is using future data, causing data leakage.

Recursive Feature Elimination: Survival of the Fittest Features
RFE runs a tournament for your features, repeatedly training a model and dropping the weakest ones. It's used to simplify models by selecting a core subset of impactful features. The main footgun: RFE's output is only as good as the model used for ranking.
Feature Definition Language: Define ML Features as Code
A feature definition language is like infrastructure-as-code for ML features. It lets you define a feature's source and schema once, then use it for both offline training and online serving, ensuring consistency.
MLflow Tracking: A Lab Notebook for Your ML Experiments
Think of MLflow Tracking as a lab notebook for your models. It logs parameters, metrics, and artifacts for every training run, letting you compare results and find the best model. The main footgun is forgetting to set a remote server, trapping logs locally.
Model Signature: The API Contract for Your ML Model
A model signature is an API contract for your ML model, defining the exact shape and types of its inputs, outputs, and parameters. It's used by platforms like MLflow to validate requests and enable safe deployments. Forgetting it will block model registration.
Hydra: Composable Configuration for Complex Apps
Hydra treats configuration like LEGOs. Instead of one monolithic file, you compose small, reusable config pieces for each run. It's ideal for ML experiments where you override settings from the command line.
Conda Environments: Isolate Your Project Dependencies
Think of a Conda environment as a separate workshop for each project, with its own tools (packages) and Python version. This prevents dependency conflicts when Project A needs a different library version than Project B.
Docker Bind Mounts: A Portal to Your Host Filesystem
A bind mount is a portal from your host machine's filesystem directly into a container, where changes on either side are reflected instantly. Use it for live code development, but never for production data, as it creates a major security risk.
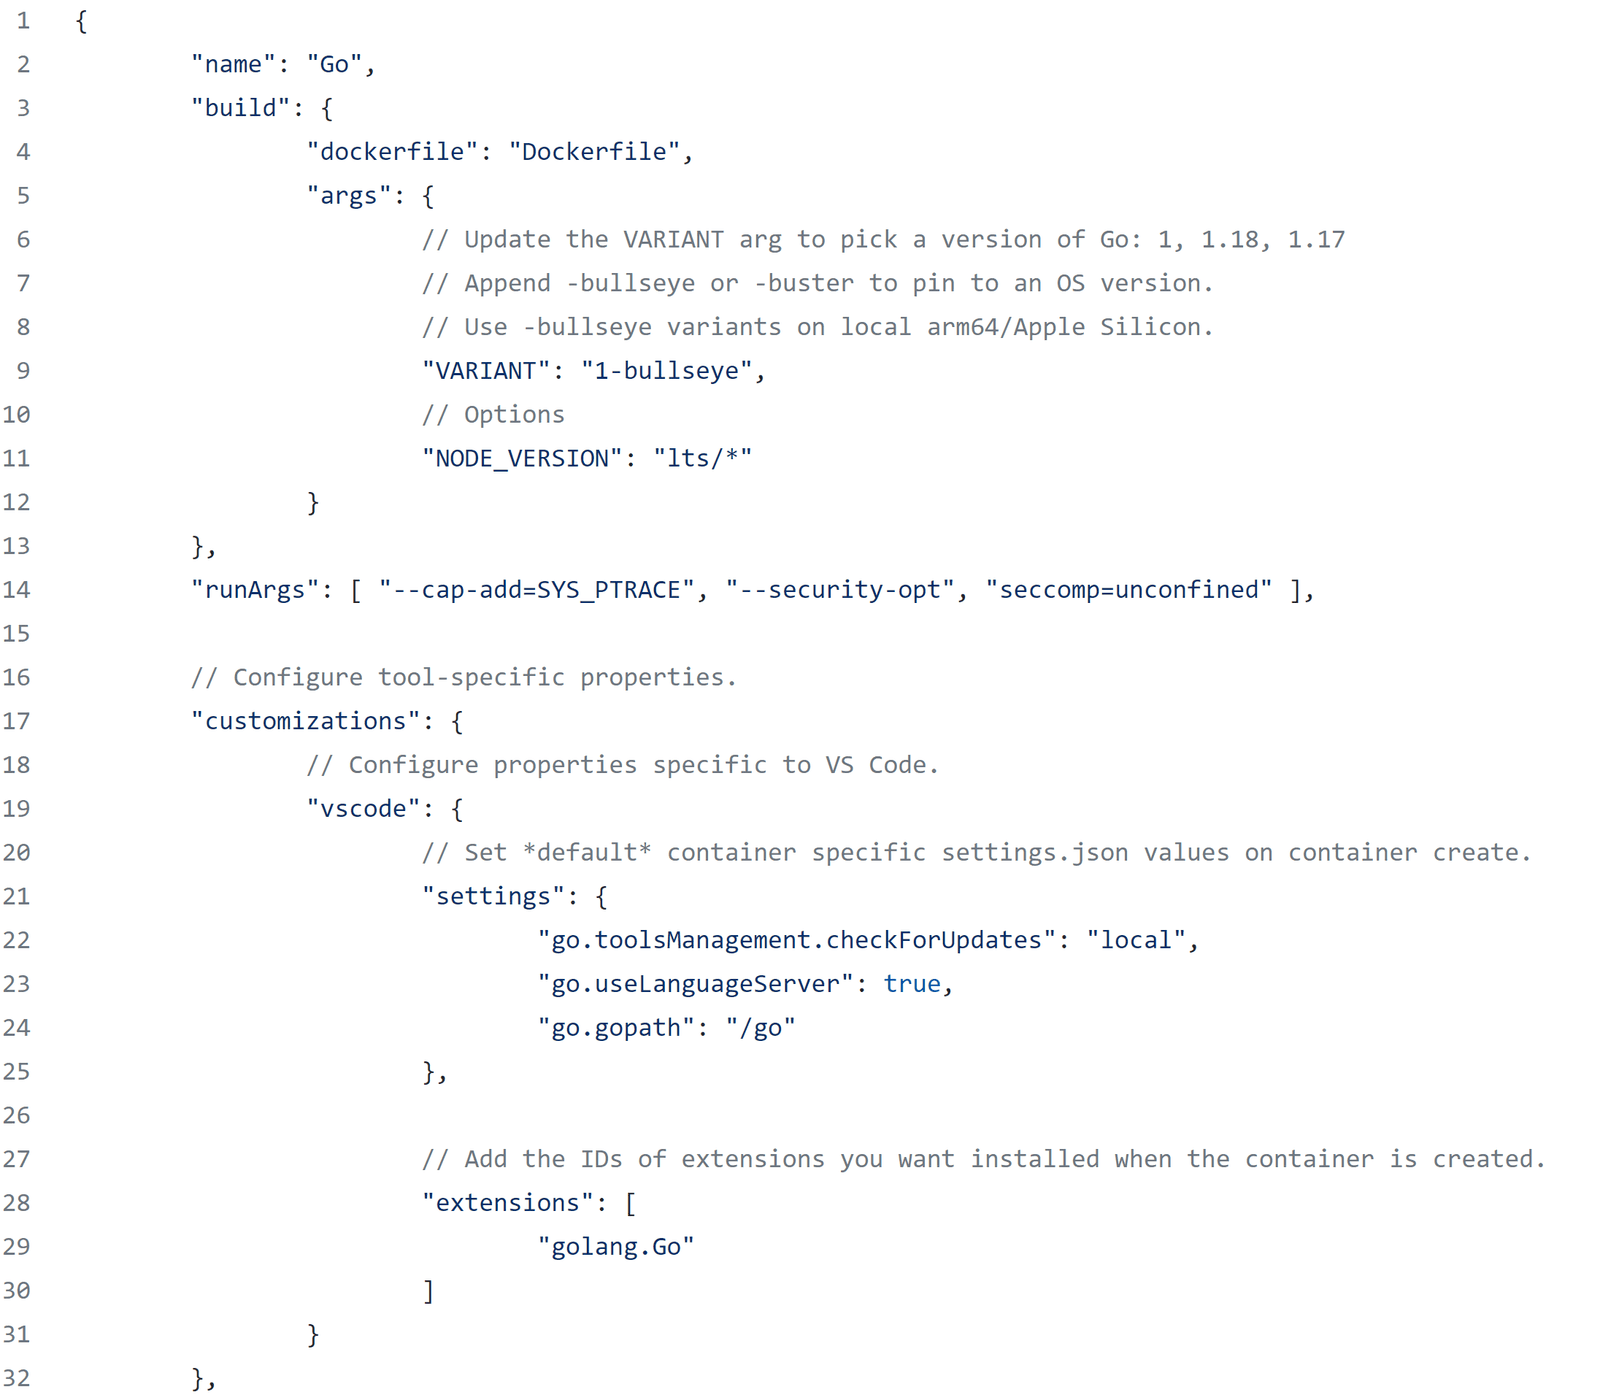
Dev Containers: Your Dev Environment as Code
A dev container packages your entire development environment—tools, libraries, and settings—into a single, portable container. Use it to standardize team environments, simplify onboarding, and ensure consistency between local dev and CI.
Configuration as Code: Version Control for Your Settings
Configuration as Code treats your system settings like source code: defined in files, versioned, and automatically applied. It's used to manage app settings or service credentials across environments, preventing manual errors.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles