Intermediate everything in MLOps & Infrastructure, page 2
Explain a model registry's purpose and what to store per version
Tests if you treat the registry as a governance bridge between training and production, not just storage. Strong answers cite versioned artifacts, lineage, metrics, dependencies, and approval gates. Red flag: calling it a file dump or experiment tracker.
How would you design drift detection for high-dimensional embeddings?
Tests distribution shift in latent spaces beyond per-feature stats. Strong answers use maximum mean discrepancy, k-NN two-sample tests, or domain-classifier AUC, plus windowing. Red flag: per-dimension KS tests or mean-difference thresholds.
How do you monitor model health with delayed ground truth labels?
Tests ML ops maturity beyond accuracy. A strong answer covers input drift via PSI or KS tests, prediction distribution shifts, proxy business metrics, and human spot-checking. A red flag is passively waiting for labels or retraining blindly without validation.
How do you configure Docker for host GPU access and CUDA libraries?
This tests GPU passthrough via the NVIDIA Container Toolkit. Strong answers use nvidia/cuda base images matching the host driver, pass GPUs with --gpus all, and avoid installing drivers inside the container.
Why avoid global Python dependencies for ML, and how do containers help?
This probes environment isolation and reproducibility in ML. A strong answer cites global dependency conflicts, system library skew, and brittle environments; then notes containers freeze the full stack for deterministic deployment.
Design a centralized model registry for a large enterprise
Tests ML artifact governance at scale. Strong answers cover immutable versioned artifacts with dependency manifests, a framework-agnostic API, and pluggable deployment targets. Red flag: treating models as opaque files without environment reproducibility.
Debug sudden model degradation using experiment tracking and model registry
Tests unified use of experiment tracking and registry lineage. Great answers verify the exact production artifact, inspect linked training data and hyperparameters, compare input distributions, and check dependency metadata.
Reproduce a six-month-old model using experiment tracking
Trace code commit, dataset version, feature pipeline, hyperparameters, dependency manifest, and random seeds through a model registry.
Describe a Model Registry and how it differs from versioned storage
It tests governance and lifecycle metadata beyond file storage. A strong answer covers lineage, stage transitions, approval gates, and artifact metadata, contrasting with buckets that only store file versions.
Why systematically track ML experiments and what should you log?
This tests reproducibility mindset over bookkeeping. A strong answer names three motivations—reproducibility, selection, debugging—and three logs: hyperparameters, metrics, and code versions.
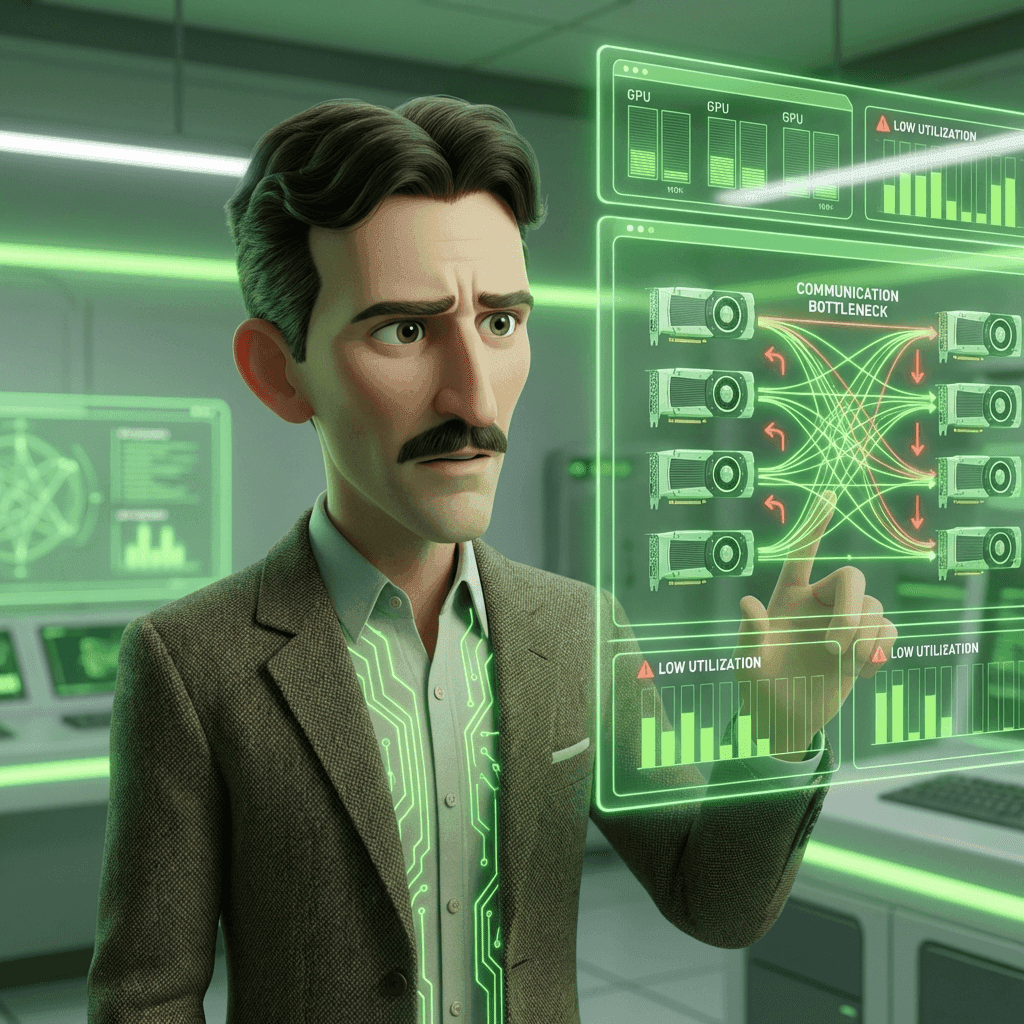
Low GPU utilization on multi-GPU instance: diagnose and right-size
Tests distributed bottleneck triage. Strong answers profile CPU/GPU/disk, compare gradient sync time to compute, validate per-GPU batch size, and check NVLink vs PCIe. Red flag: suggesting more GPUs before ruling out data starvation or all-reduce overhead.
Design an ML workflow that masks PII from scientists
This tests privacy-preserving pipeline design and least-privilege access for ML teams. Propose automated de-identification before experimentation, restrict re-identification to production jobs, and enforce role-based access with audit logs.

Compare and contrast Apache Airflow versus Kubeflow Pipelines for ML orchestration
This tests matching orchestrators to ML constraints. A strong answer contrasts Airflow's task scheduling and backfills with Kubeflow's K8s-native GPU scaling, choosing based on team skills.

Explain dynamic batching in inference servers and its trade-off
Dynamic batching launches when a time window or max size is met, improving throughput over static batching, but short ones wait for the slowest.

Design a multi-tenant GPU serving system for hundreds of fine-tuned models
Tests GPU memory tradeoffs versus cold-start latency in multi-tenant serving. Strong answers propose tiered CPU staging, predictive pre-warming, and disaggregated prefill and decode. Red flag: keeping all models GPU-resident or ignoring transfer overhead.

Compare Canary and Blue/Green ML deployments and model-specific metrics
Contrast Canary gradual shift vs Blue/Green instant swap; highlight silent failures, data drift, prediction distribution; cite accuracy and calibration.
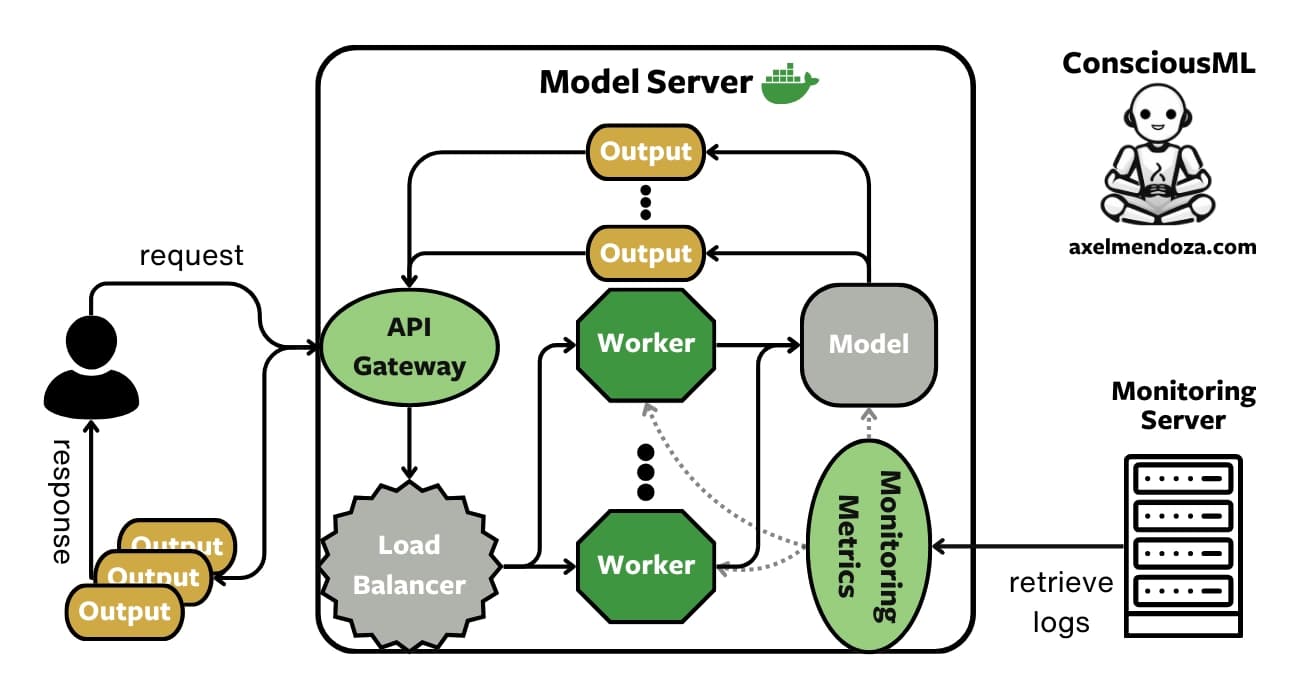
Expose a trained model as a simple web service
Practical MLOps knowledge from model serialization to serving. Package the model into a standard format, containerize it, expose a REST endpoint behind a load balancer, and add monitoring. A bare Flask server without containers or health checks is a red flag.
How would you version control a 50GB dataset in a CI/CD pipeline?
Contrast Git LFS (simple, but 50GB chokes CI clones) with DVC (git metadata plus S3; enables selective pulls and CI cache).
How would GDPR requirements influence experiment tracking and model management design?
Immutable data lineage, user exclusion lists, audit logs, versioned explainability.
How do you ensure ML experiment reproducibility beyond random seeds?
Tests system-level reproducibility through data versioning, environment capture, and pipeline automation. Strong answers cover versioned datasets, containerized dependencies, and immutable experiment logs.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles