Intermediate interview questions in Product Management, page 11

Design an A/B test for a Buy Now button
This tests experiment plumbing: deterministic bucketing, sticky storage, and logging. A strong answer covers user-ID hashing, cookie persistence, and impression-plus-conversion events.
Determine if a 10% DAU drop is statistically significant
Tests signal vs noise in stable metrics. Good answers define a null hypothesis, compute a test statistic from historical variance, compare to a critical value at set alpha, and check seasonality. Red flag: calling a large drop real without baseline variance.
DAU dropped 10% overnight. Is this a significant change?
Tests your use of statistical hypothesis testing on business metrics. Outline the process: state a null hypothesis (no change), choose a Z-test, calculate the p-value, and compare to an alpha of 0.05. A red flag is guessing causes before proving significance.
How to Statistically Test a 10% DAU Drop?
Tests your knowledge of hypothesis testing. A good answer outlines the steps: state a null hypothesis, choose a test (e.g., Z-test), calculate a p-value, and compare it to a significance level (alpha).

Outline architecture for a weekly email digest of unread notifications
This tests batch processing and scheduled delivery at scale. Pre-aggregate unread counts, shard digest jobs across a distributed scheduler, and cache unsubscribes for fast filtering. Never scan the notifications table at send time for millions of users.

Explain Simpson's Paradox and construct a user engagement scenario
Tests whether you spot trends reversing when population mixes differ. Good answers define the paradox, give a numerical example with per-segment wins but aggregate loss, and warn against segment-only decisions.
Explain Simpson's Paradox with a user engagement example
Tests if you see beyond aggregate data. Define the paradox, give a numerical example where a feature fails overall but wins in segments (e.g., new vs. returning users), and name the confounding variable. A vague definition without numbers is a red flag.
Explain Simpson's Paradox with a user engagement example
This tests your understanding of statistical pitfalls in A/B testing. A good answer defines the paradox, gives an example where a feature fails in aggregate but wins in every segment, and attributes it to a confounding variable.
Compare fan-out-on-write vs fan-out-on-read for an activity feed
Tests whether you tie feed architecture to read/write ratios and follower distribution. Strong answers contrast push O(1) reads with celebrity storms against pull O(1) writes with read amplification, then propose a hybrid threshold.
What artifacts and processes mitigate cross-team API dependency risks?
This tests de-risking external API dependencies via contracts. A strong answer proposes an OpenAPI spec as the source of truth, mock servers for parallel work, and automated CI validation.
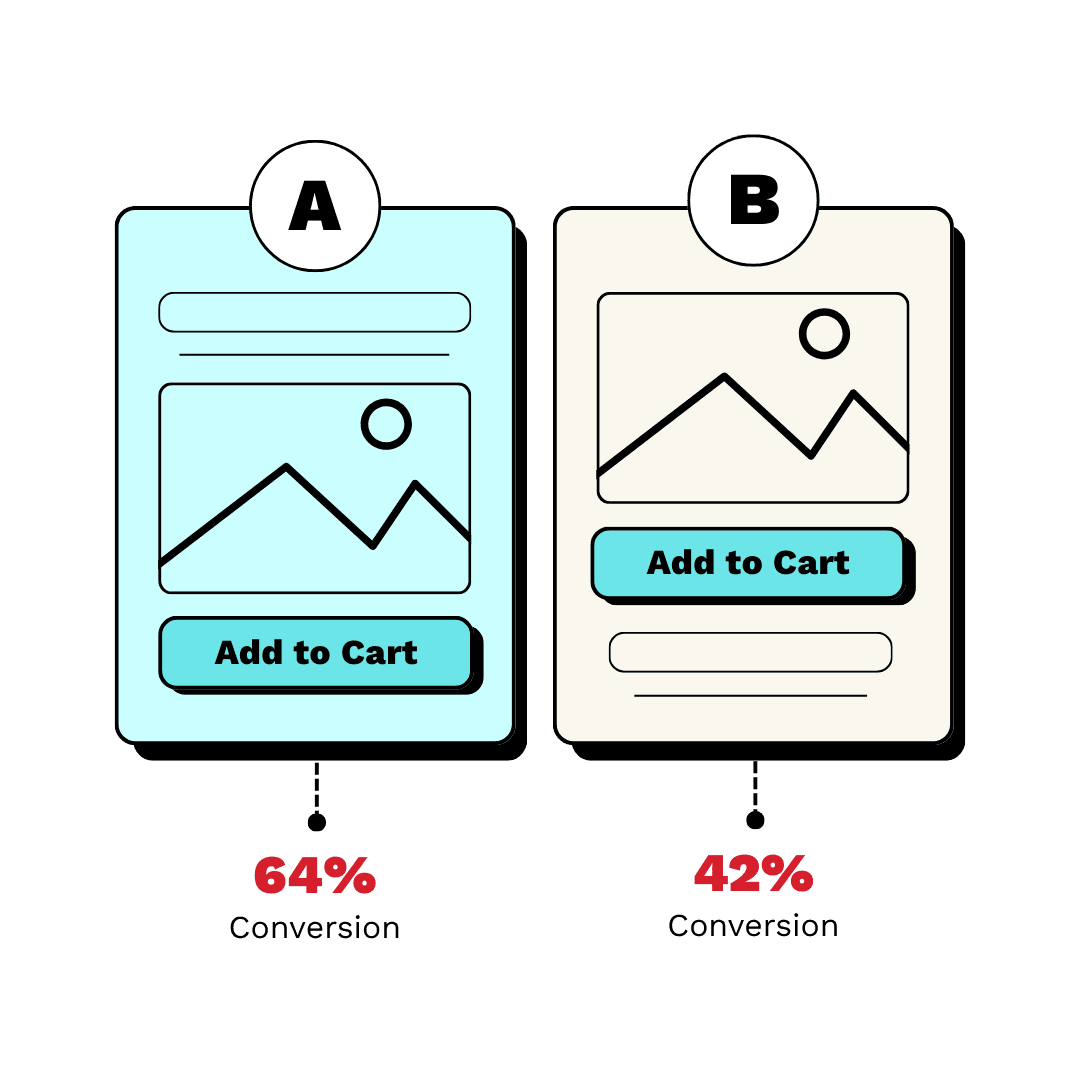
How do you determine sample size and duration for an A/B test?
This tests statistical power literacy. A strong answer names baseline rate, MDE, alpha, and beta; explains the duration versus sensitivity trade-off; and notes traffic allocation. A red flag is ignoring power or stopping early when results look significant.
How do you determine sample size and duration for an A/B test?
This tests your grasp of statistical power and business trade-offs. A good answer defines the four inputs (baseline, MDE, significance, power) to calculate sample size, then uses traffic to find duration.
How do you determine A/B test sample size and duration?
This tests your ability to connect business goals to statistical parameters. A good answer defines the four power analysis inputs (baseline, MDE, alpha, power) and explains trade-offs, then converts sample size to duration using business cycles.
Your feature launches but engagement doesn't move. What's engineering's role in diagnosis?
Validate data, segment users, test tech and behavioral hypotheses, propose experiments.
Why is stopping an A/B test at first significance problematic?
Tests peeking and Type I error inflation. Name peeking; explain daily looks inflate false positive rates above nominal alpha; note p-values assume one look at fixed sample size; recommend pre-committed runtimes or sequential testing.
How would you implement an A/B test for a redesigned dashboard?
Tests experiment rigor: randomize stable user buckets, pick one primary metric and guardrails like latency, pre-calculate sample size and runtime with a minimum detectable effect, and validate via backend logging.
Why is stopping an A/B test early problematic?
Tests understanding of the 'peeking problem' in A/B testing. A good answer defines peeking, explains how it inflates false positive rates, and contrasts it with waiting for a pre-determined sample size. A red flag is not explaining the statistical mechanism.
How would you A/B test a redesigned dashboard?
Tests translating a vague goal ('more engagement') into a concrete engineering plan. A good answer defines key metrics first, then outlines user bucketing, instrumentation, and statistical analysis.
Why is stopping an A/B test when it hits significance problematic?
Tests your understanding of the 'peeking problem' in A/B testing. A great answer defines peeking, explains how it inflates the Type I error rate (false positives), and states the need for a predetermined sample size.
How would you A/B test a redesigned dashboard?
This tests your ability to translate a product goal into a technical plan. A good answer defines "engagement" with metrics, outlines the bucketing and instrumentation strategy, and discusses statistical significance.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles