Advanced interview questions in UX Research
Describe a lightweight research method to validate a feature with no researcher
What it tests: bootstrapping validation without research headcount. Answer outline: unmoderated concept tests or concierge MVPs; behavioral vs attitudinal data; lightweight recruiting. Red flag: shipping A/B tests or using only internal opinions.
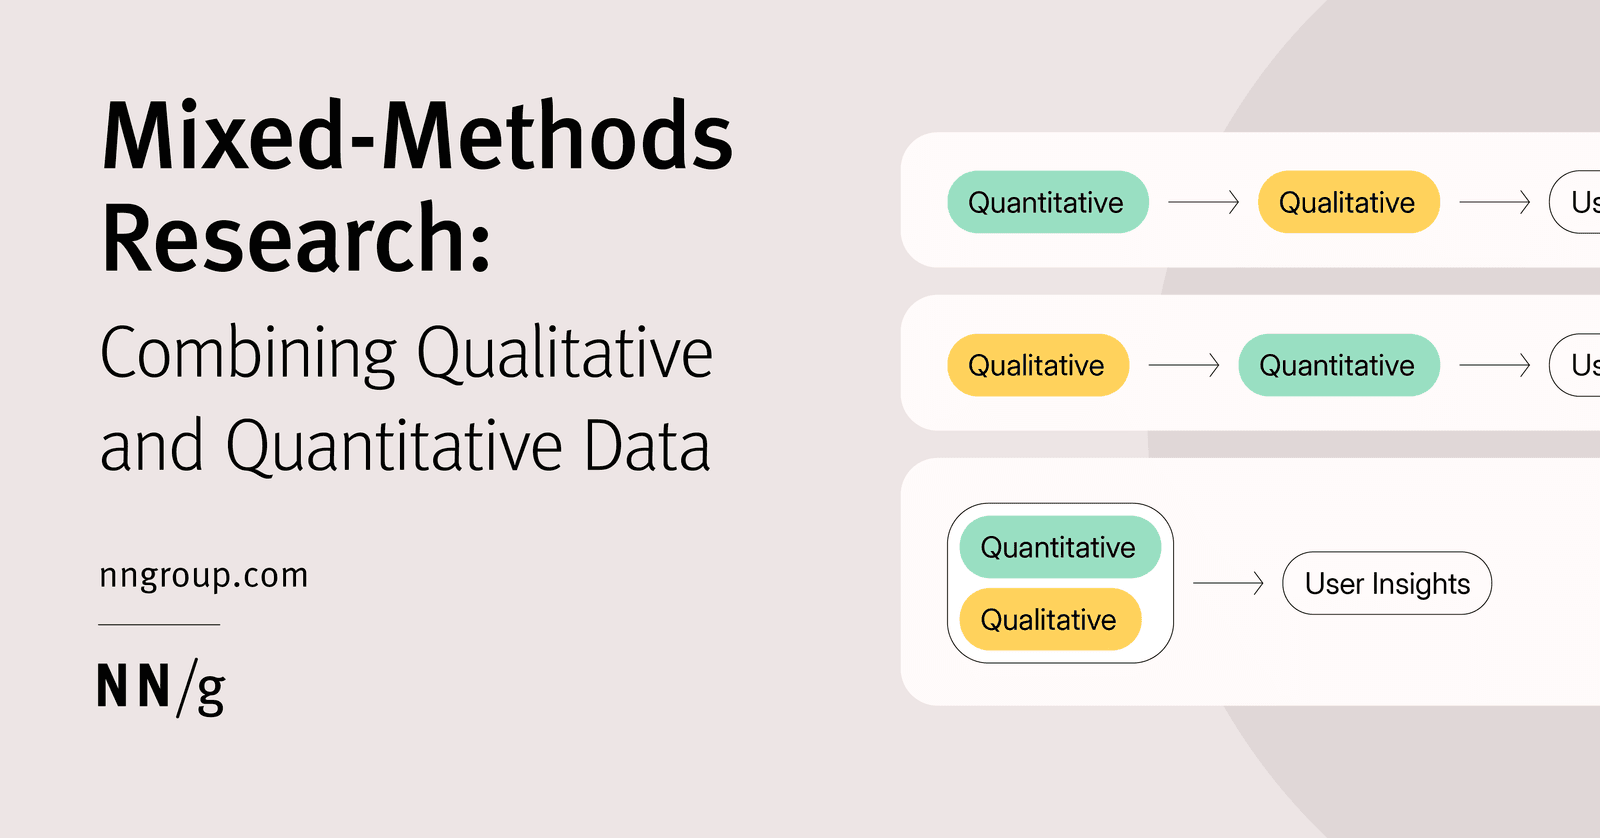
How would you instrument a feature to validate qualitative findings quantitatively?
Mapping themes to events, picking guardrail and success metrics, and sampling.
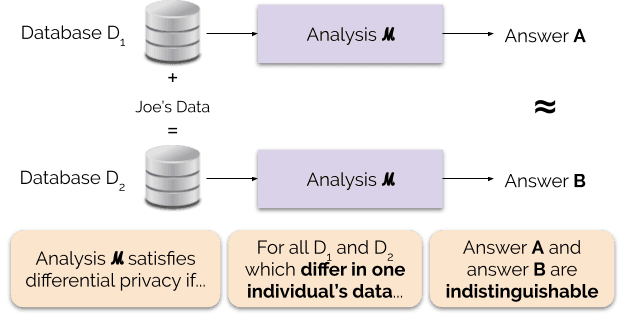
Apply differential privacy to user behavior queries and explain epsilon trade-offs
Mastery of formal privacy guarantees and noise-based query systems. Inject Laplace or Gaussian noise scaled to query sensitivity; track cumulative epsilon across queries; lower epsilon tightens privacy but increases variance and error bars.
Propose an automated de-identification pipeline for video interview recordings
Propose CV redaction, ASR/NLP for names, human QA, and consent tracking; note model bias and re-ID risk.
Design a one-week lean research plan for a high-risk decision
This tests trading rigor for speed without losing decision signal. A strong answer matches the riskiest assumption to a fast method, sequences generative and validation across five days, and defends bias.

How would you structure a backend architecture A/B test and define metrics?
This tests causal inference rigor for infrastructure changes. A strong answer covers sticky user routing, controlling for geography and time, and paired primary metrics like P99 latency and error rate.

Outline a technical roadmap for an internal research participant panel
Tests systems design for research ops. Strong answers: CRM-synced opt-in, canonical data model with eligibility rules, communication orchestration, and incentive automation.
Design a system integrating analytics data with participant recruiting
Tests system design for behavioral targeting in research ops. A strong answer covers: a warehouse-to-tool pipeline; consent and privacy gates; behavioral SQL segmentation; and frequency capping. Red flag: skipping GDPR and consent to focus only on data joins.
Design a centralized participant management system to prevent over-contacting
Tests ResearchOps governance at scale. Strong answers define unified data tracking contact history, consent, and segments; enforce hard frequency caps and cooling-off windows; and build automated guardrails. Red flag: siloed spreadsheets or soft guidelines.

Advocate for generative research over a complex feature request?
Tests mapping research methods to product risk. Strong answers reframe the feature as an unvalidated problem, cite qualitative behavioral methods like field studies, and translate unknowns into scope and opportunity cost.
What lightweight generative research reveals why users drop off a funnel?
Tests bridging analytics to qualitative insight fast. Outline: run 5-8 micro-interviews at the exact drop-off step; probe confidence and expectations; map findings to technical fixes.

How do you adapt contextual inquiry for internal API and tool design?
This tests applying ethnographic methods to API design by observing engineers at work, surfacing invisible habits, and mapping findings to endpoint granularity and docs. A red flag is treating internal users as unlike external customers or using only surveys.
How would you triage 50+ UX issues against new features in agile?
Matrix the 50 issues by severity and effort; reserve 15-20% sprint capacity for debt; socialize compound cost.
How do you architect an automated performance and accessibility testing pipeline?
This tests operationalizing quality gates via automation, not manual checks. A strong answer covers Lighthouse CI in CI/CD, fail thresholds for CWV and WCAG, and a triage workflow assigning regressions to owners.
Detect a three-action user sequence in real-time at scale
Tests stream processing and stateful pattern matching on unbounded data. A strong design uses a CEP engine with keyed event-time windows, pushes alerts via WebSocket, and trades state-memory for latency.
How do you trace data points to journey map stages?
Tests auditable evidence chains for technical buy-in. Answer covers a traceability matrix linking quotes to stages and pain points, plus validation sessions where engineers inspect source data. Red flag: presenting the map as intuition without source docs.

How do you challenge assumptions and mitigate confirmation bias during synthesis?
Tests structural defenses against confirmation bias, not vague mindfulness. Strong answers name concrete protocols like hypothesis reversal, separate raw evidence from interpretation, and triangulate with logs.
What analytical frameworks structure synthesis beyond thematic analysis?
Tests if you model problems structurally, not just code themes. Strong answers pair mental models to map user goals with JTBD to prioritize unmet needs by importance and satisfaction. Red flag: naming frameworks without explaining how they reshape synthesis.
Explain statistical power and respond to extending a null A/B test
This tests statistical power and p-hacking judgment. A strong answer defines power as detecting a true effect, rejects extending the test to chase significance, and requires pre-registered sample sizes. Agreeing to run until it hits significance is a red flag.
What metrics and models link onboarding to long-term retention?
Track activation-to-D90 metrics; use Cox/AFT or diff-in-diff; control censoring.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles