All bites
The whole library, newest first. Filter by what you are here for, or pick a topic if you already know.
8667 bites
Page 386
High Dynamic Range (HDR): Seeing More Light
HDR captures a wider range of light and dark than standard images, preventing blown-out highlights and crushed shadows. It's used to show scenes as the human eye sees them. The footgun is thinking HDR is just 'brighter'—it's about more detail in the extremes.
MAML: Learning to Learn Quickly
MAML trains a model to be easy to fine-tune, finding an initial set of parameters that serve as a great starting point for many new tasks. It's used in few-shot learning where models must adapt with minimal data.
Masked Autoencoders: Learning Vision by Filling in the Blanks
Masked Autoencoders (MAEs) teach models vision by playing "fill-in-the-blanks" with images, masking most of an image (e.g., 75%) and learning to reconstruct it. This is used for self-supervised pre-training of large Vision Transformers on unlabeled data.
Momentum Contrast (MoCo): A Dynamic Dictionary for Unsupervised Learning
MoCo learns visual features without labels by treating contrastive learning as a dynamic dictionary lookup. A momentum-updated encoder creates a large, consistent set of keys on-the-fly, enabling powerful pre-training on unlabeled data for downstream vision…
SimCLR: Learning Powerful Vision Features Without Labels
SimCLR learns image features from unlabeled data by teaching a model that two augmentations of one image are similar, and all other images are different. It's used to pre-train models on vast, unlabeled datasets.
Weakly Supervised Learning: Cheaper Labels, Smarter Models
Weakly Supervised Learning trains models on cheap, imprecise labels to perform complex tasks. It's used for object detection when you only have image-level tags, not pixel-perfect annotations.
Prototypical Networks: Learning from a Handful of Examples
Prototypical Networks classify new categories from few examples by finding the average representation, or 'prototype,' for each class. This is key for few-shot image recognition where you have only 1-5 examples.

Zero-Shot Learning: Classifying the Unseen
Zero-Shot Learning lets a model classify things it never trained on. It works by linking visual features to semantic descriptions, like identifying a 'zebra' from the description 'striped horse'. The footgun is assuming it creates knowledge from nothing.
N-way-K-shot: Classifying with Few Examples
N-way-K-shot is a framework for testing a model's ability to learn from scarce data. It asks: 'Can you classify between N categories after seeing only K examples of each?'
Semi-Supervised Learning: More From Less Data
Semi-supervised learning uses a small set of labeled data and a large set of unlabeled data to train a model. It's ideal for tasks like image classification where labeling is costly. The footgun: if your unlabeled data is noisy, it can degrade performance.
Pretext Tasks: Making Data Teach Itself
A pretext task is a fake problem you invent for a model so it learns from unlabeled data. For example, asking it to predict a missing image patch forces it to learn about objects. This is the core of self-supervised learning.
Visual Commonsense Reasoning (VCR): From Recognition to Cognition
VCR pushes AI from simple object recognition to human-like reasoning by asking not just 'what' is in an image, but 'why.' Models must select both the correct answer and the correct rationale, exposing models that guess answers based on shallow correlations.
Affordance Learning: Teaching AI What Objects Do
Instead of just naming objects, affordance learning teaches AI to see potential actions—a chair is for sitting, a knob is for turning. This is crucial for robotics, where a machine must know how to interact with novel items.
Visual Servoing: Using Eyes to Guide a Robot's Hands
Visual servoing is like how you reach for a cup: your eyes guide your hand. A robot uses a camera to continuously correct its motion toward a target, closing the loop between seeing and doing. It's key for robotic arms, drones, and surgical bots.
Scene Graph Generation: From Pixels to Relationships
Scene Graph Generation (SGG) moves beyond just finding objects in an image; it maps out the relationships between them. This enables deeper scene understanding for tasks like advanced image search.
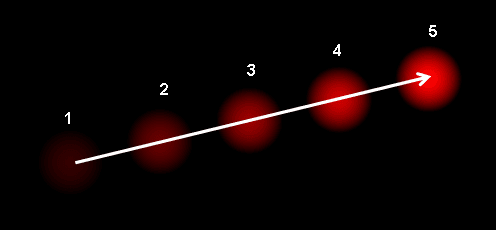
Visual Odometry: Estimating Motion from Pixels
Visual odometry is dead reckoning with a camera. It estimates movement by tracking how features shift between images, without GPS or maps. It's used in robotics and AR, but its biggest footgun is that small errors accumulate, causing it to drift over time.

Visual Question Answering (VQA): Teaching AI to See and Reason
VQA models combine vision and language to answer questions about an image, like a visual Turing test. It's used in assistive tech and advanced image search. The footgun is models learning to answer based on language patterns, not visual content.

Scene Parsing: Labeling Every Pixel in an Image
Scene parsing is like digital coloring-by-numbers, assigning a category like 'road' or 'sky' to every pixel. It's used by autonomous vehicles to understand the road and AR apps to place objects.
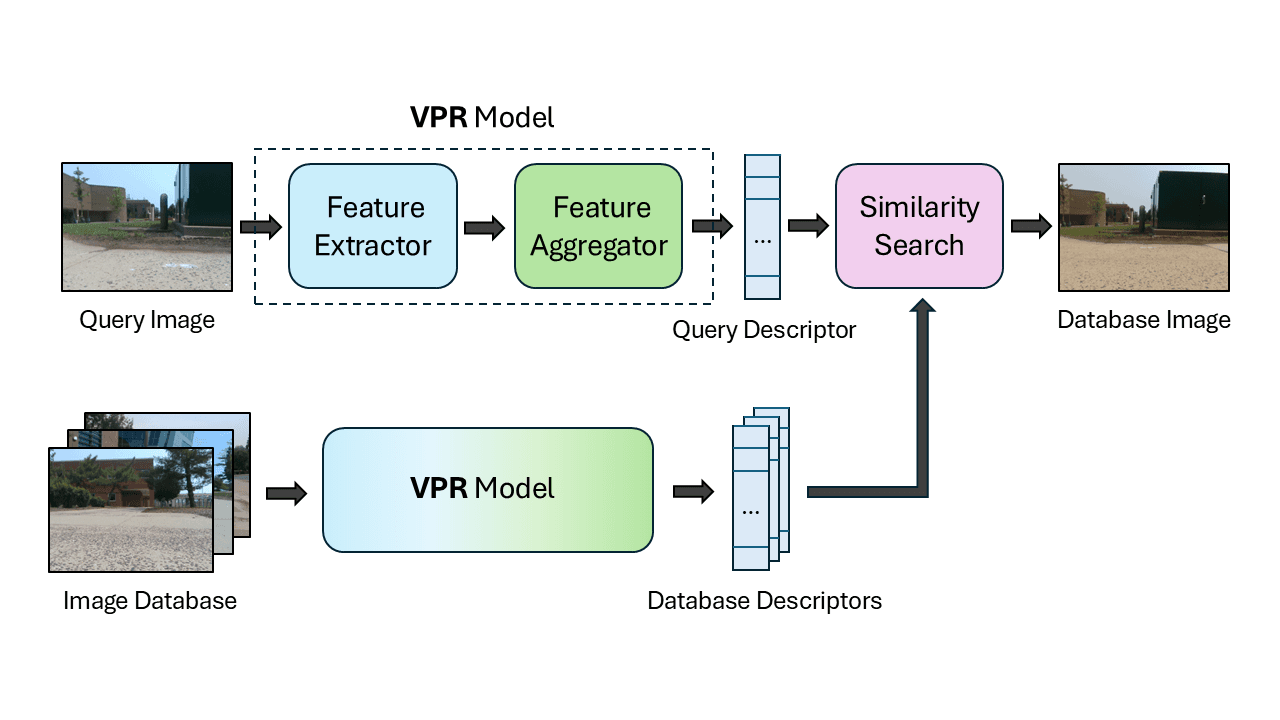
Visual Place Recognition: Finding Your Location from a Picture
Visual Place Recognition (VPR) answers "Where am I?" by matching a live camera image to a database of pre-recorded pictures. It's a visual GPS for robots and self-driving cars to find their position when GPS is unreliable, like in cities or indoors.
Image Captioning: Teaching Machines to Describe What They See
Image captioning teaches a computer to generate a human-readable sentence describing an image, translating pixels into words. This powers accessibility features and better image search.