All bites
The whole library, newest first. Filter by what you are here for, or pick a topic if you already know.
8667 bites
Page 387
GAN Inversion: Editing Real Photos with Fake Image Generators
GAN Inversion finds the latent code "recipe" inside a pre-trained GAN that best recreates a real image. This lets you use a generator's powerful editing features on real photos for tasks like manipulation or restoration.
Normalizing Flows: Shaping Simple Distributions into Complex Ones
Normalizing flows transform a simple probability distribution, like a Gaussian, into a complex one, like images. This allows generative models to explicitly calculate the probability of any data point. The footgun is that the transformation must be invertible.
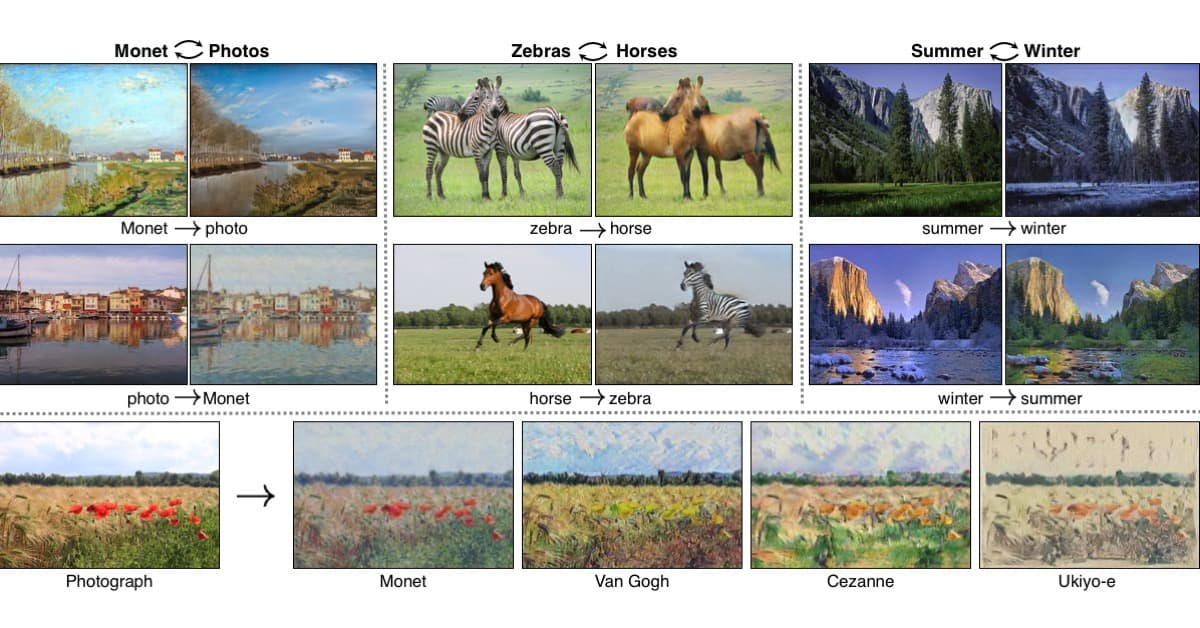
CycleGAN: Image Translation Without Paired Data
CycleGAN translates images between domains (e.g., photos to paintings) without direct 'before' and 'after' examples. It's used for style transfer or turning horses into zebras. The footgun is that it hallucinates details, making it unsafe for critical tasks.
Perceptual Loss: Judging Images by Vibe, Not Pixels
Perceptual loss judges an AI-generated image by its 'vibe,' not just pixel-for-pixel accuracy. It compares high-level features, making it key for style transfer and super-resolution.
CLIP: Teaching AI to See with Words
CLIP creates a shared map for images and text, letting you classify images with natural language prompts. It's used for zero-shot classification and semantic search, bypassing the need for task-specific labeled data.
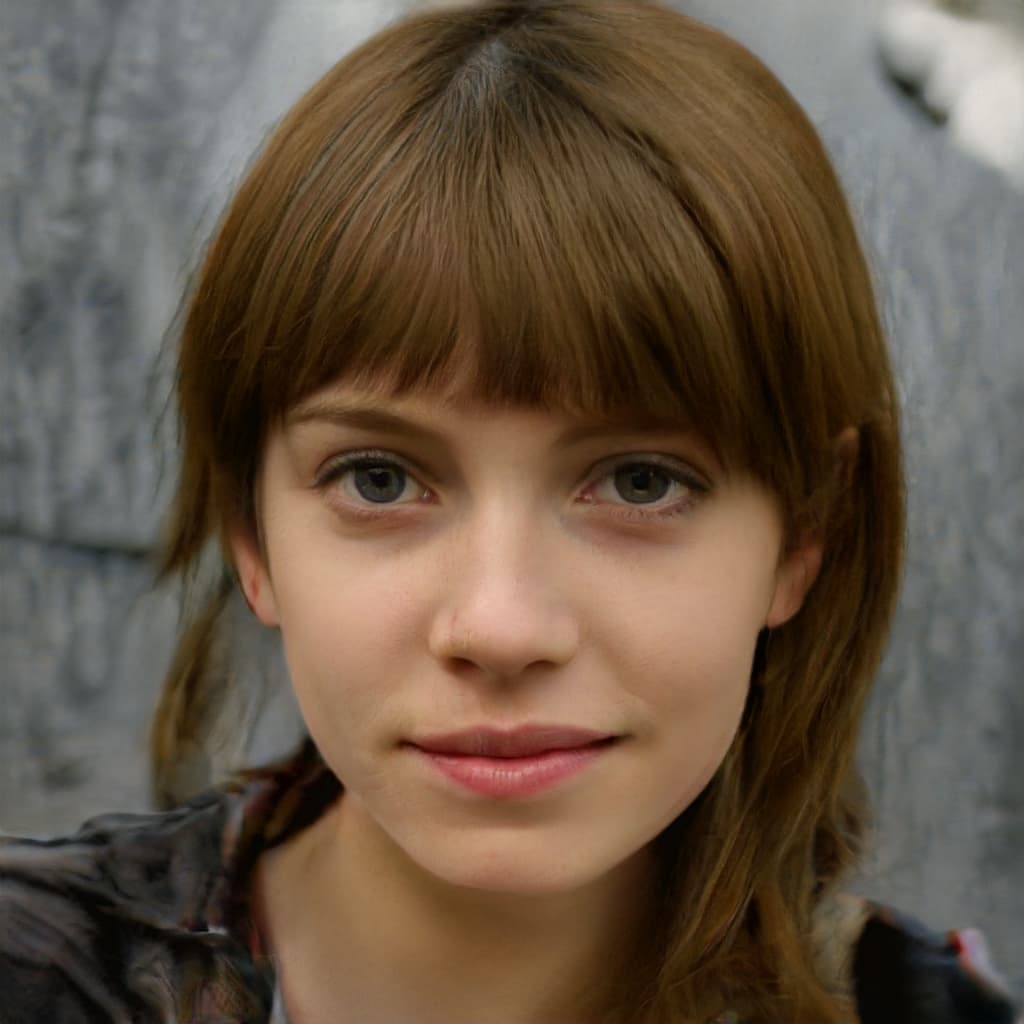
StyleGAN: Controllable, High-Fidelity Image Generation
StyleGAN generates images by controlling 'style' at different levels, like a painter layering coarse, medium, and fine details. It excels at creating hyper-realistic images with tunable features.
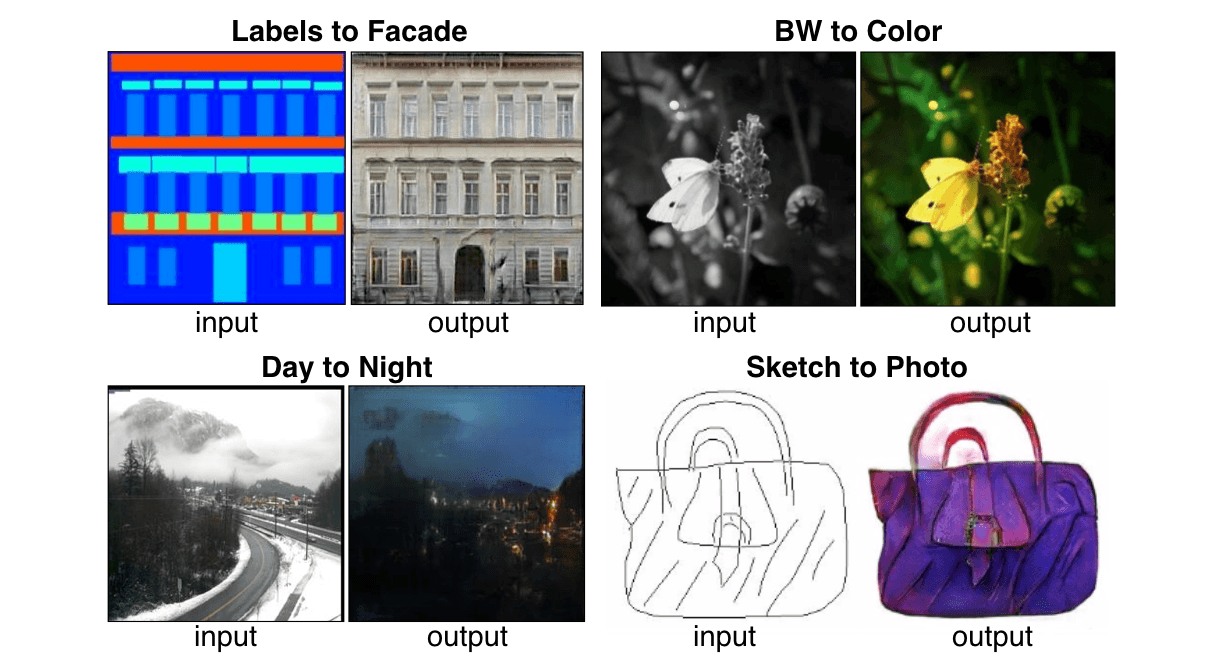
Image-to-Image Translation: One Model, Many Styles
Think of it as a universal visual translator. Given paired examples, it learns to convert one image style to another, like turning a building sketch into a photorealistic rendering. The footgun: it needs a large, aligned 'before-and-after' dataset.
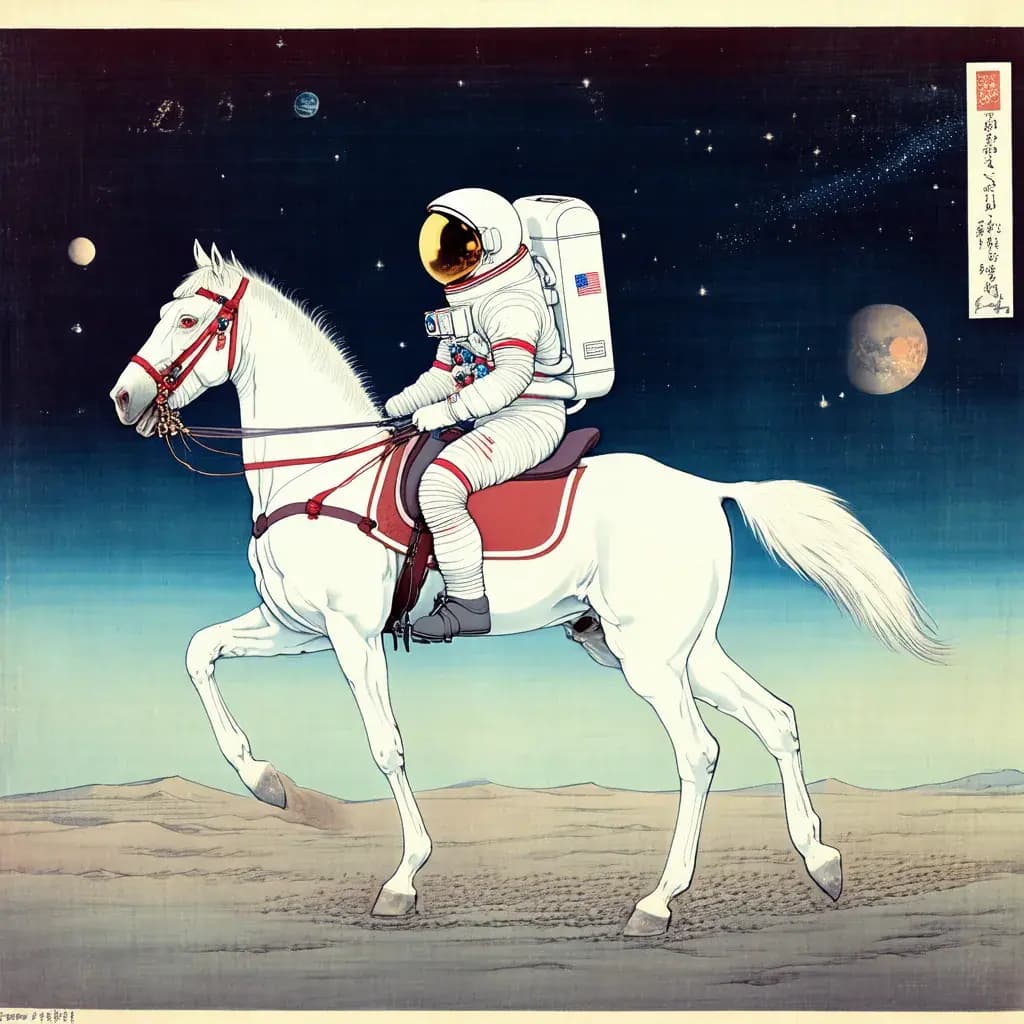
Text-to-Image Generation: From Words to Pixels
Text-to-image models act like a digital artist, translating language into visuals. They're used to create art, marketing materials, and prototype designs. The main footgun is prompt ambiguity, which can lead to bizarre or nonsensical images.
Latent Space: A Map Where Distance is Similarity
A latent space is a map of concepts where distance equals similarity. Similar items are clustered together, which powers image generation and recommendation engines. The footgun is that the map's dimensions are abstract, not human-interpretable features.
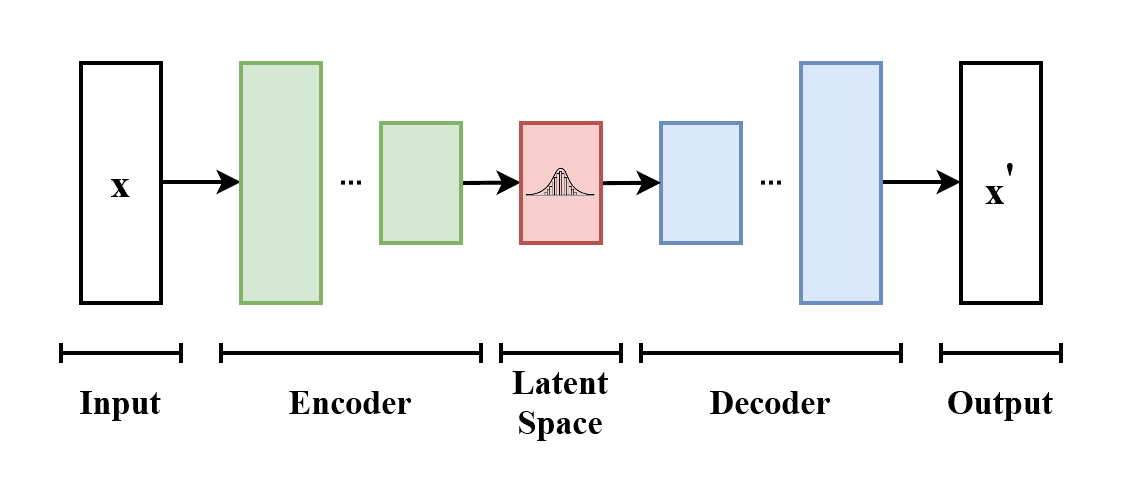
Variational Autoencoders: Learning to Generate Data
A VAE learns to create new data by compressing examples into a "latent space" of core features and then decoding from it. It's used for generative art and data augmentation, but its outputs can be blurrier than those from other models like GANs.
Diffusion Models: Generating by Reversing Noise
Diffusion models generate data by learning to reverse a process of adding noise. They power state-of-the-art image generation (DALL-E 2, Stable Diffusion). The main footgun is that their iterative sampling process is slow and computationally expensive.
NeRF: Turning 2D Photos into a Walkable 3D Scene
A Neural Radiance Field (NeRF) learns to be a 'ray-tracing oracle' for a scene, predicting color and density from any angle. It's used to create walkable 3D experiences from 2D photos. The footgun: NeRFs can't invent details not in the source images.
MLP-Mixer: Vision Without Convolutions or Attention
MLP-Mixer shows that simple MLPs can achieve strong vision results, challenging the need for convolutions or attention. It works by alternating between mixing features within image patches and mixing information across patches.
Cross-Attention: How Models Fuse Text and Images
Cross-attention lets a model fuse different data streams, like asking 'what in this image corresponds to this word?'. It's key for text-to-image generation, where text queries attend to image features. The footgun is confusing it with self-attention.
Swin Transformer: Efficient Vision with Shifted Windows
Swin Transformer makes Vision Transformers practical by processing images in local "windows" instead of all at once. It's a powerful backbone for object detection and segmentation where scale varies.
DETR: Object Detection as Direct Set Prediction
DETR reframes object detection from a filtering task to direct set prediction. It uses a Transformer to output a fixed set of object predictions in one pass, eliminating complex post-processing.

Multi-Head Attention: Seeing Data From Multiple Angles
Multi-head attention lets a model analyze a sequence from multiple perspectives at once. It runs several "attention heads" in parallel, each focusing on different relationships, like syntax vs. semantics.
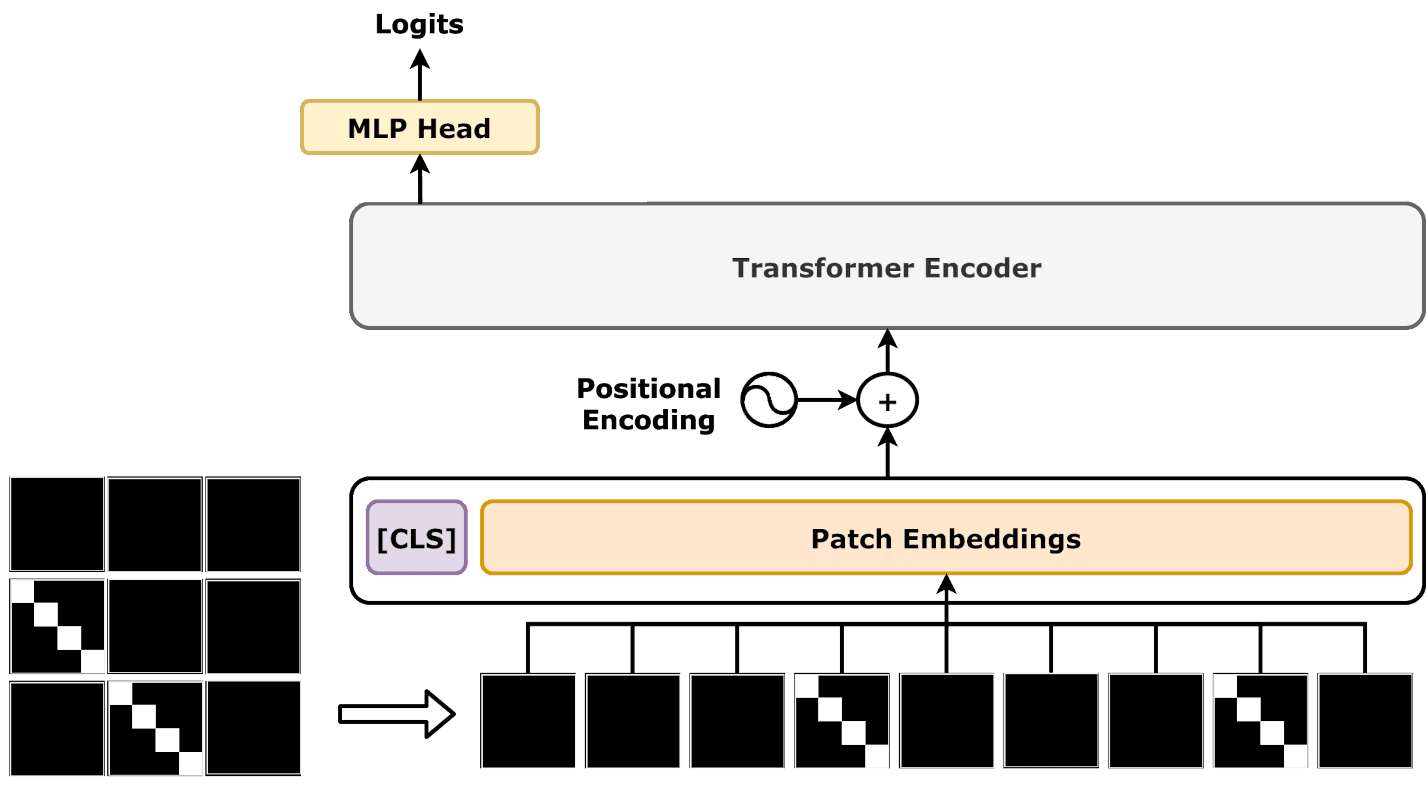
Patch Embedding: Turning Images into Words for Transformers
Patch embedding chops an image into a grid of squares, turning each into a vector. This lets sequence-based models like Transformers "read" images. It's the core of Vision Transformers (ViTs), but it discards the fine-grained detail inside each patch.

Generative Adversarial Networks (GANs): A Forger and a Detective
A GAN pits two neural networks against each other: a Generator that creates fakes and a Discriminator that spots them. This adversarial game forces the Generator to produce highly realistic outputs, like photorealistic faces. The main footgun is mode collapse.
Attention in Vision: Teaching Models Where to Look
Attention teaches a model where to look in an image by dynamically weighting important pixels or features. It's used in object detection to focus on relevant regions. The footgun is assuming it's free; attention adds computational cost and complexity.