All bites
The whole library, newest first. Filter by what you are here for, or pick a topic if you already know.
8667 bites
Page 389
Focal Loss: Forcing Models to Learn from Hard Examples
Focal Loss tells your model to ignore the easy examples during training and focus on the hard ones. This is critical for object detection, where thousands of background patches can overwhelm the few actual objects, creating a massive class imbalance.
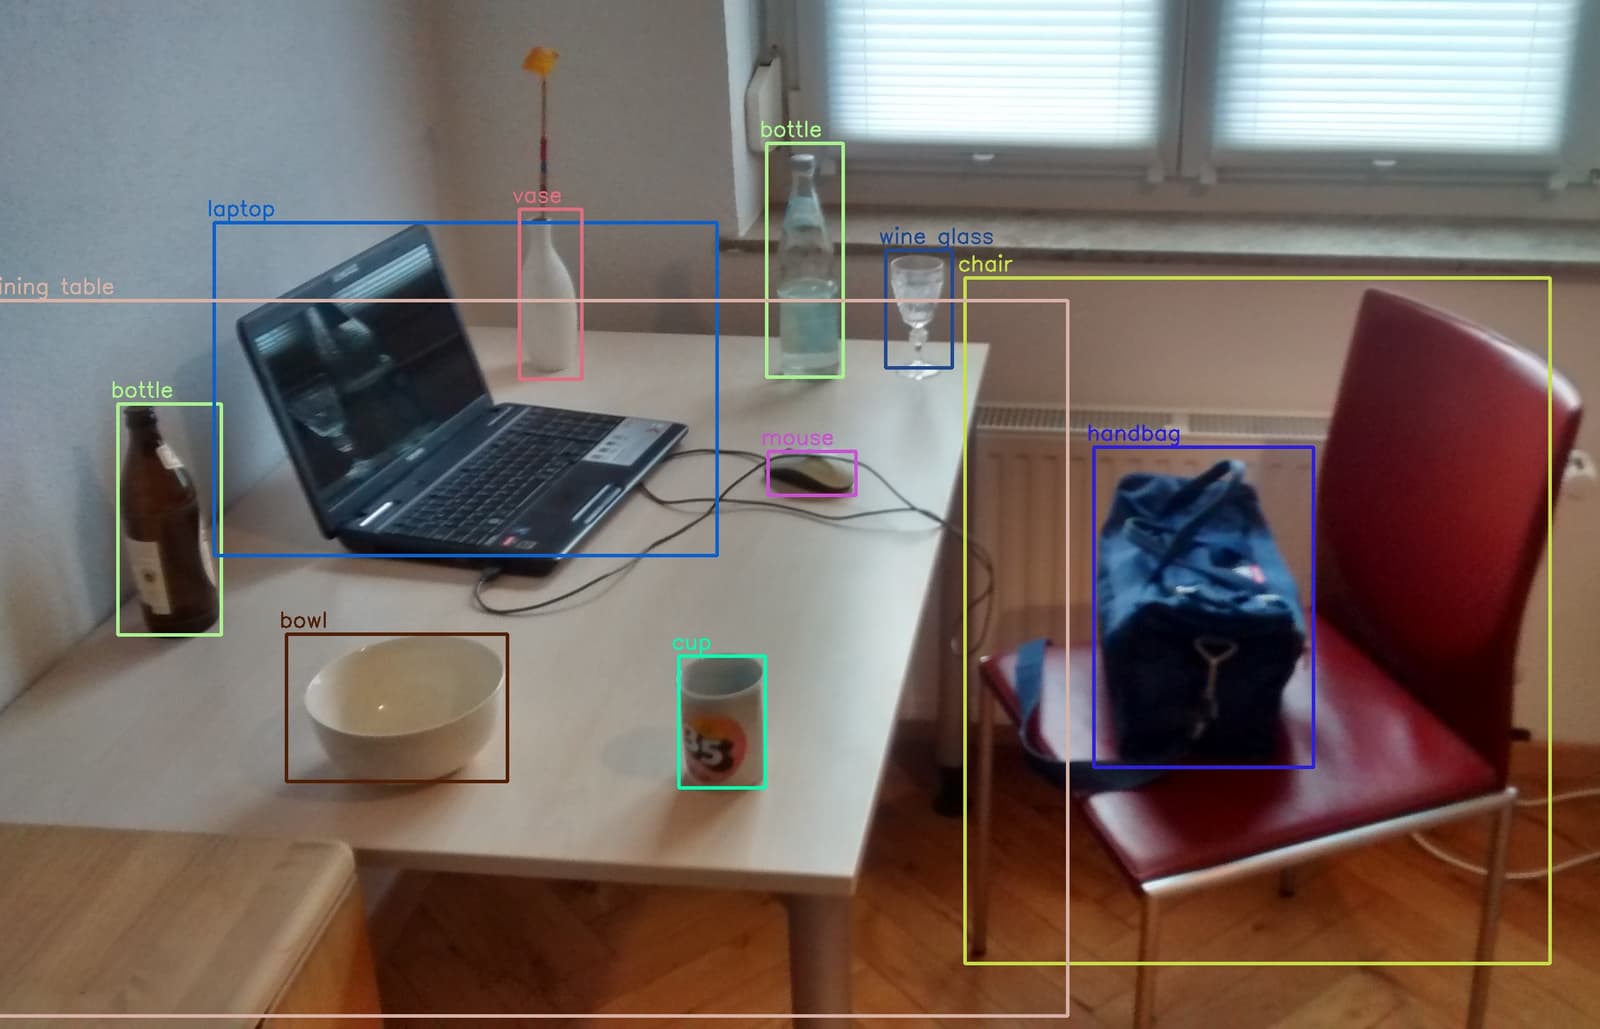
YOLO: Real-Time Object Detection in a Single Pass
YOLO treats object detection as a single regression problem, looking at an image once to predict all bounding boxes and classes. This makes it extremely fast, perfect for real-time video analysis.
Region Proposal Network (RPN): The 'Where to Look' Engine
An RPN is an 'attention' mechanism for object detection, telling the model where to look. It replaces slow, external proposal methods in systems like Faster R-CNN for autonomous driving.
Intersection over Union (IoU): How Good is Your Bounding Box?
Intersection over Union (IoU) scores how well a predicted box matches the real one by dividing their overlap area by their total area. It's vital for object detection in self-driving cars and medical imaging.
Localization vs. Detection: One Box or Many?
Object localization draws one box around an image's main object. Object detection finds and boxes *every* instance of a class, like all pedestrians. Use localization for single-subject tasks, detection for finding everything.

Transfer Learning: Don't Train Vision Models from Scratch
Don't train a vision model from scratch. Transfer learning reuses a model trained on a huge dataset (like ImageNet) as a starting point for your specific task. This lets you achieve high accuracy on new image types with much less data and compute.
GoogLeNet's Inception Module: Wider, Not Just Deeper
Instead of choosing one filter size, GoogLeNet's Inception module runs 1x1, 3x3, and 5x5 convolutions in parallel. This lets the network capture features at multiple scales at once. The footgun is forgetting the crucial 1x1 'bottleneck' convolutions.
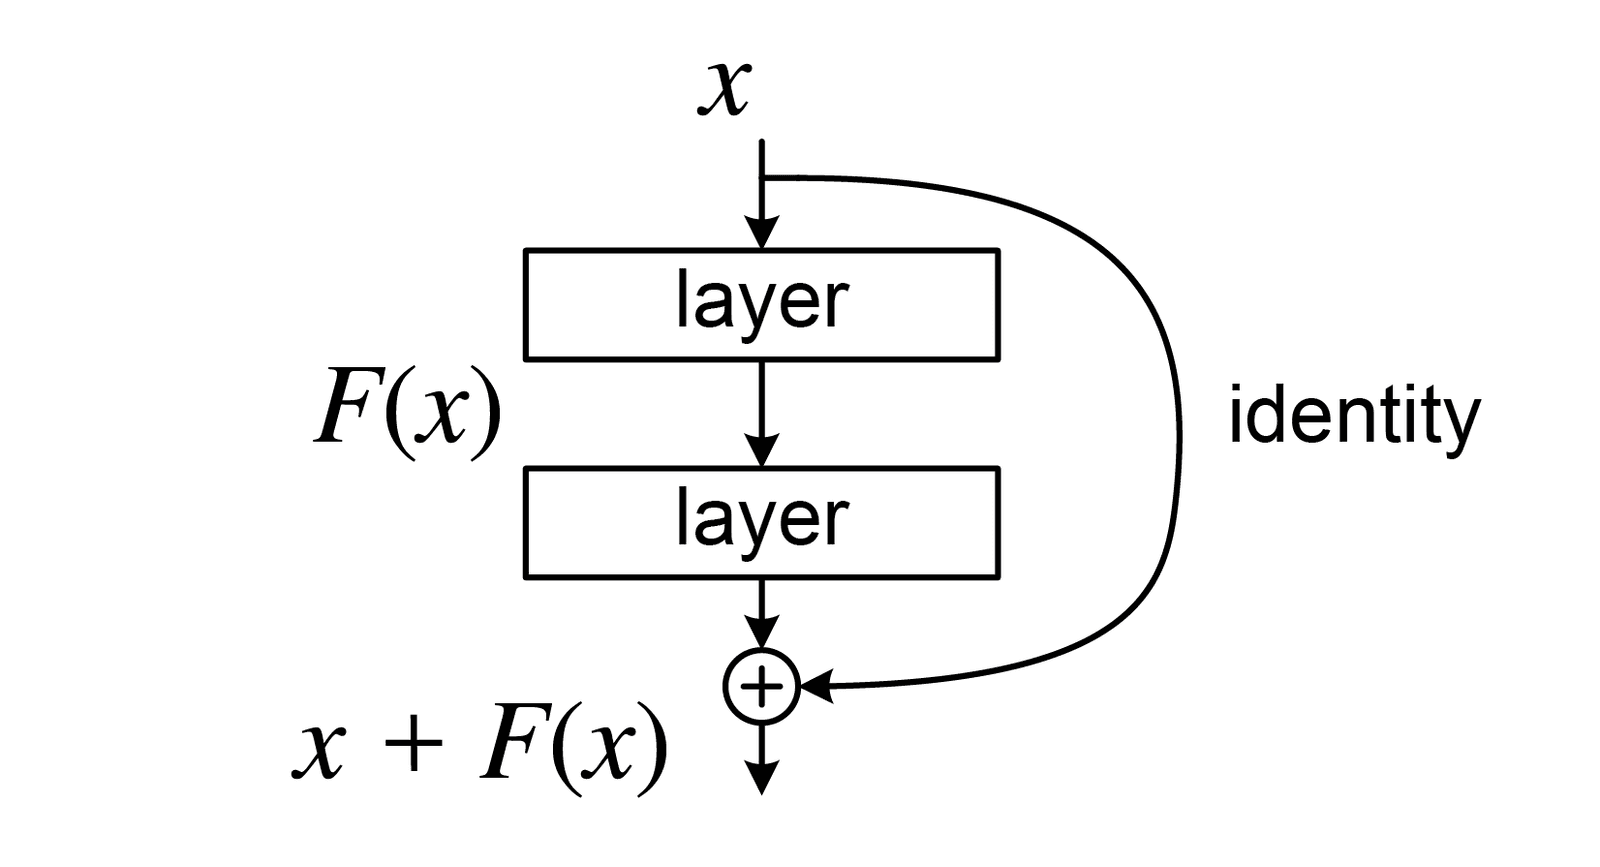
Residual Networks (ResNets): Go Deeper, Not Worse
ResNets let you train extremely deep networks by learning what to *change*, not the entire output. They use 'skip connections' to bypass layers, which helps solve accuracy degradation in deep vision models. The footgun is thinking deeper is always better.
Batch Normalization: Stabilizing Neural Network Training
Batch Normalization regulates data flow in a neural network by re-centering and re-scaling inputs to each layer. This stabilizes deep network training, allowing higher learning rates.

AlexNet: The CNN That Sparked the Deep Learning Boom
AlexNet is the blueprint that proved deep CNNs could master image recognition, kicking off the modern AI boom. Its architecture is foundational for modern computer vision. The footgun is thinking it was just bigger; its novelty was combining new techniques.
Dropout: Forcing a Network to Generalize
Dropout prevents overfitting by randomly zeroing out a fraction of neurons during training. This forces the network to learn more robust features instead of relying on specific neurons. It's a standard regularizer for large, dense layers.
Data Augmentation: Getting More Images for Free
Data augmentation creates "fake" training data by modifying existing images—flipping, rotating, or color-shifting them. This fights overfitting when your dataset is small, forcing the model to generalize.
Backpropagation: How Neural Networks Learn from Mistakes
Backpropagation is how a network learns from its mistakes. It works backward from the output error, calculating how much each weight contributed and adjusting it. This is the core training loop for most deep learning models.
Cross-Entropy Loss: How Wrong Is Your Model's Guess?
Cross-entropy loss measures the penalty when a model's predicted probabilities diverge from the true labels. It's the standard loss for classification tasks, like telling a cat from a dog.

ReLU: The 'On/Off' Switch for Neural Networks
ReLU acts as a simple on/off switch for neurons: positive inputs pass through, negative ones become zero. It's the default activation in deep learning, especially for vision tasks, as it's fast and helps gradients flow. The footgun: neurons can "die".
Pooling Layers: Summarizing What Matters in an Image
A pooling layer is like squinting at an image; you lose fine detail but see the main shapes. It summarizes features in a region, reducing computation and making the model robust to small shifts.
Feature Maps: What a Neural Network 'Sees'
A feature map is the output of a filter in a neural network, highlighting where a specific pattern (like an edge or curve) appears. In CNNs, each layer generates dozens of these maps. The footgun is thinking one map sees an object, not just a.
Convolutional Layers: Finding Features Anywhere
A convolutional layer is like a flashlight sliding over an image, looking for a specific pattern like an edge or corner. It's the core of computer vision, letting networks find features anywhere.
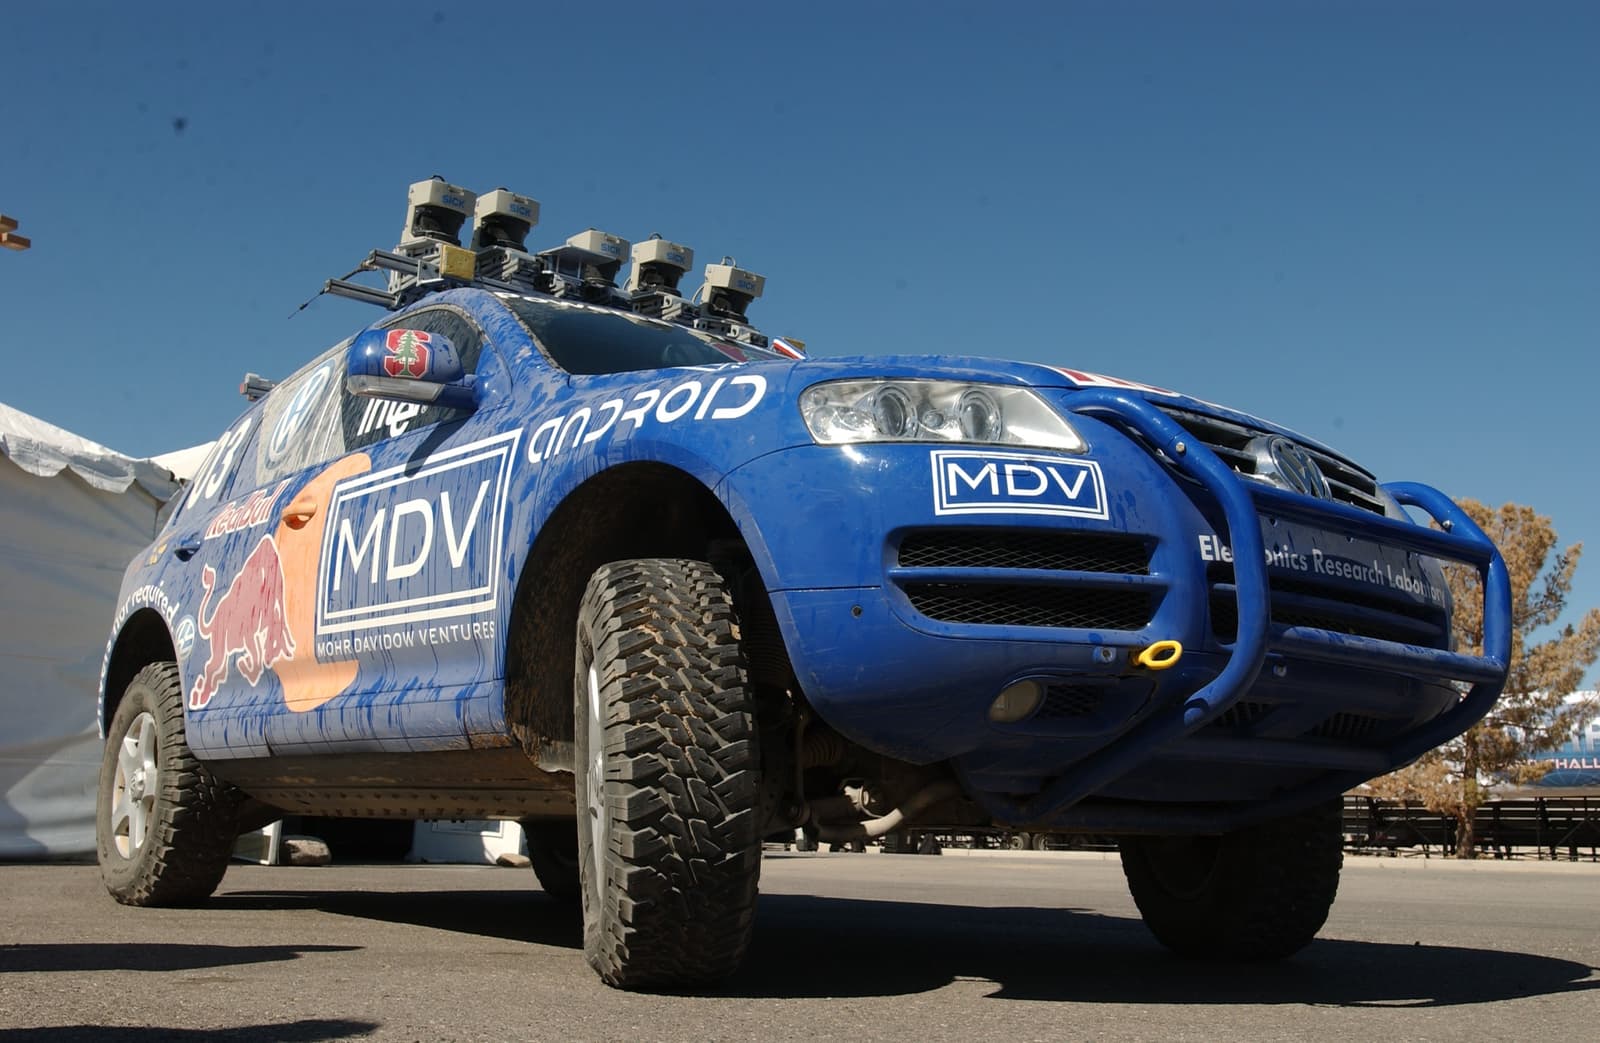
SLAM: Mapping a Room While You're Still In It
SLAM solves a chicken-and-egg problem: you can't map a space without knowing your location, and you can't know your location without a map. It does both at once. It's used by robots and AR headsets to navigate.
Bundle Adjustment: Jointly Refining 3D Scenes and Cameras
Bundle adjustment is a grand negotiation, simultaneously refining a 3D scene, camera poses, and lens properties to best explain the 2D images. It's the final polish in Structure from Motion (SfM) or SLAM.