Easy everything in AI & ML, page 12
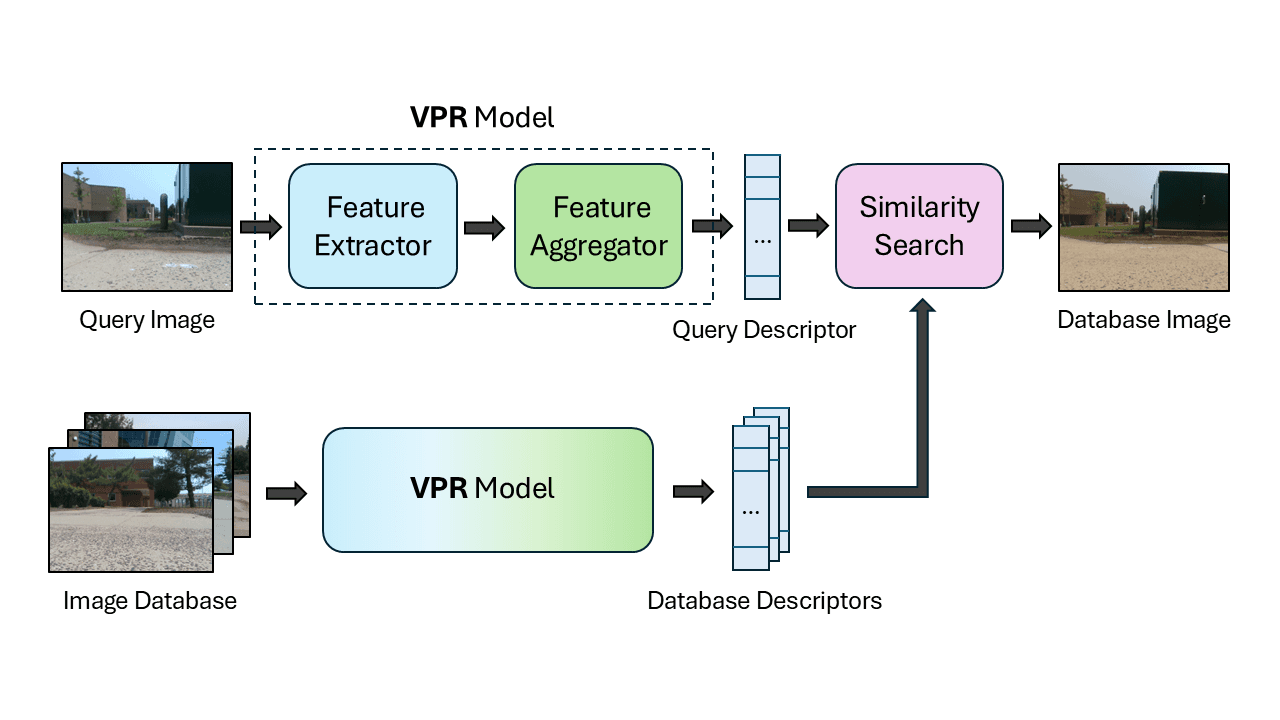
Visual Place Recognition: Finding Your Location from a Picture
Visual Place Recognition (VPR) answers "Where am I?" by matching a live camera image to a database of pre-recorded pictures. It's a visual GPS for robots and self-driving cars to find their position when GPS is unreliable, like in cities or indoors.
Image Captioning: Teaching Machines to Describe What They See
Image captioning teaches a computer to generate a human-readable sentence describing an image, translating pixels into words. This powers accessibility features and better image search.
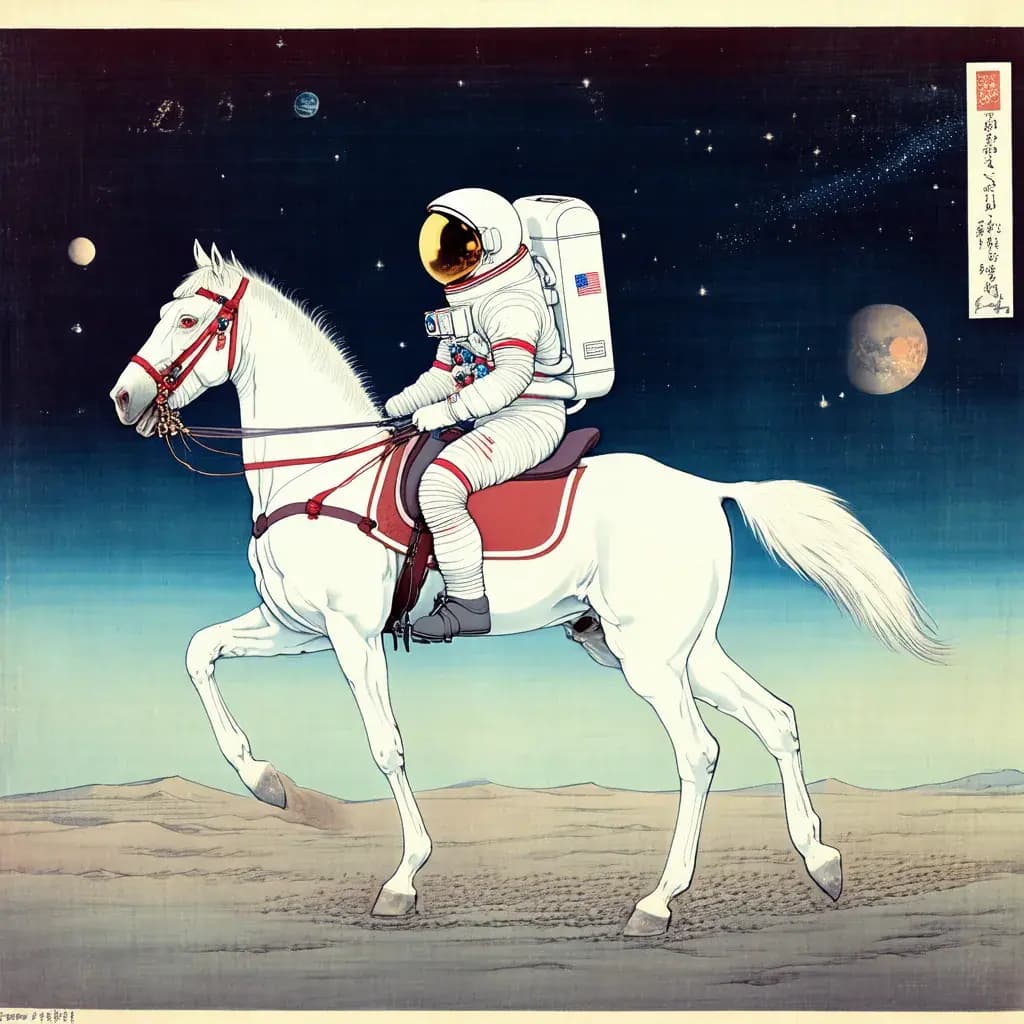
Text-to-Image Generation: From Words to Pixels
Text-to-image models act like a digital artist, translating language into visuals. They're used to create art, marketing materials, and prototype designs. The main footgun is prompt ambiguity, which can lead to bizarre or nonsensical images.
Latent Space: A Map Where Distance is Similarity
A latent space is a map of concepts where distance equals similarity. Similar items are clustered together, which powers image generation and recommendation engines. The footgun is that the map's dimensions are abstract, not human-interpretable features.
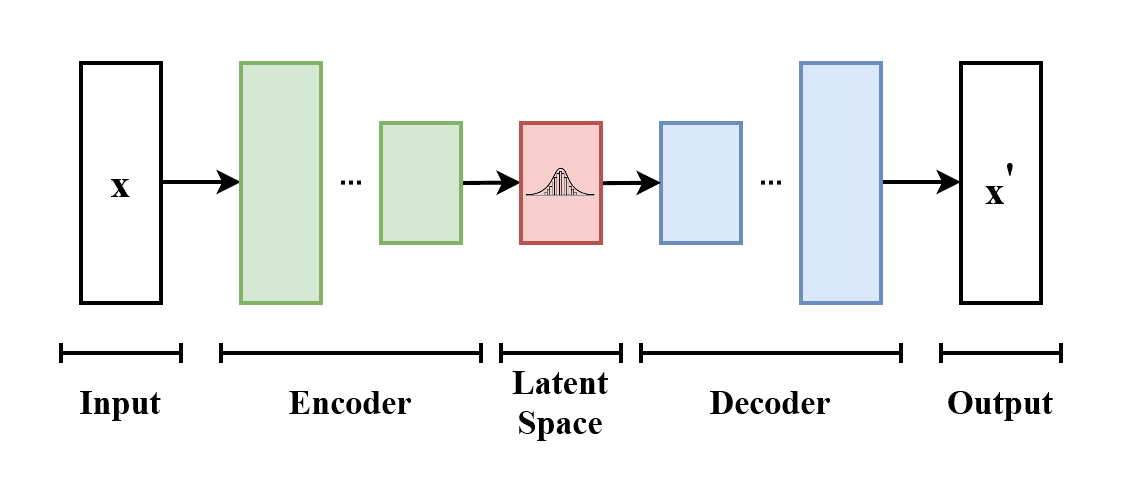
Variational Autoencoders: Learning to Generate Data
A VAE learns to create new data by compressing examples into a "latent space" of core features and then decoding from it. It's used for generative art and data augmentation, but its outputs can be blurrier than those from other models like GANs.
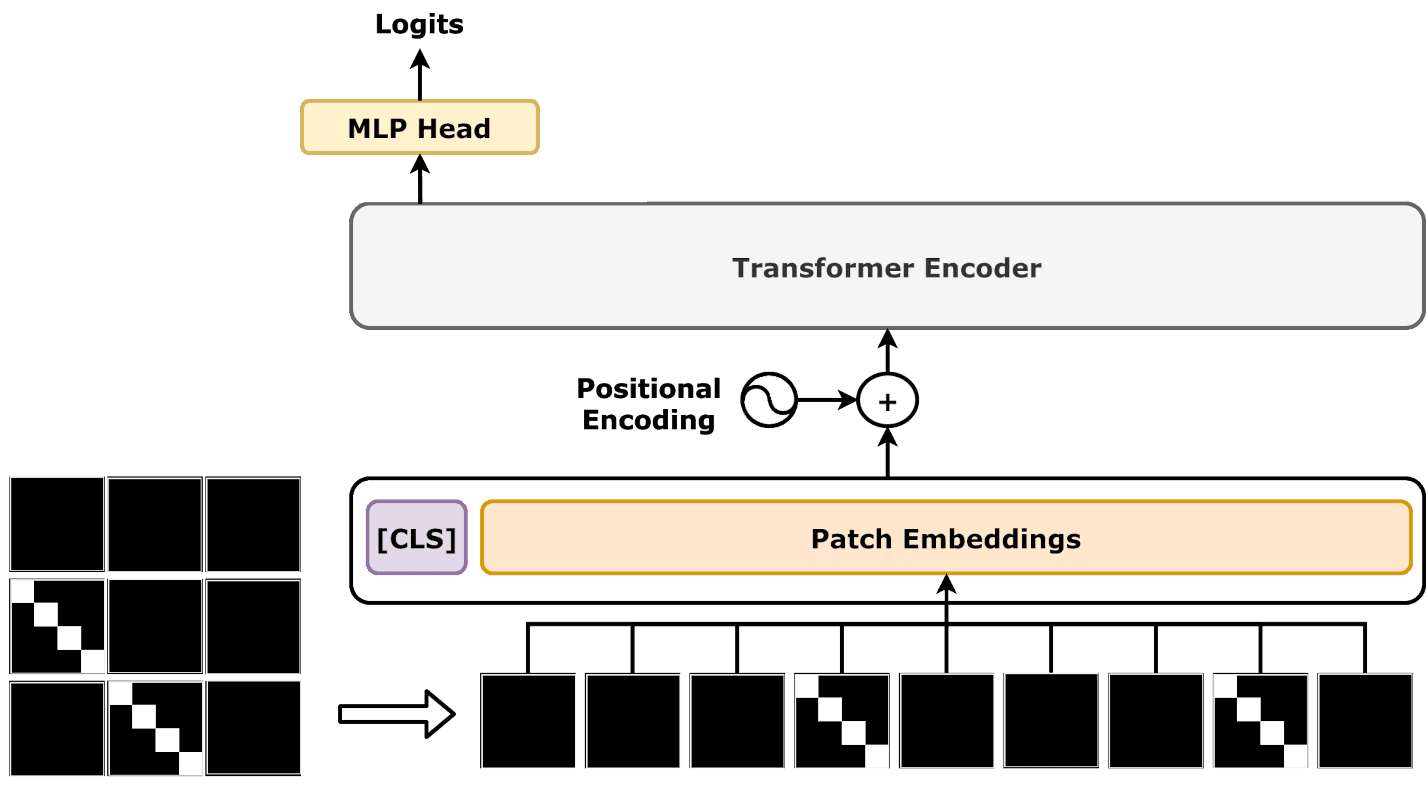
Patch Embedding: Turning Images into Words for Transformers
Patch embedding chops an image into a grid of squares, turning each into a vector. This lets sequence-based models like Transformers "read" images. It's the core of Vision Transformers (ViTs), but it discards the fine-grained detail inside each patch.

Generative Adversarial Networks (GANs): A Forger and a Detective
A GAN pits two neural networks against each other: a Generator that creates fakes and a Discriminator that spots them. This adversarial game forces the Generator to produce highly realistic outputs, like photorealistic faces. The main footgun is mode collapse.

Attention in Vision: Teaching Models Where to Look
Attention teaches a model where to look in an image by dynamically weighting important pixels or features. It's used in object detection to focus on relevant regions. The footgun is assuming it's free; attention adds computational cost and complexity.
Action Recognition: Teaching Machines to Understand 'Doing'
Action recognition teaches computers to understand *what* is happening in a video by analyzing motion over time. It's used for fall detection in healthcare, sports analysis, and security. The footgun is confusing it with single-frame object detection.
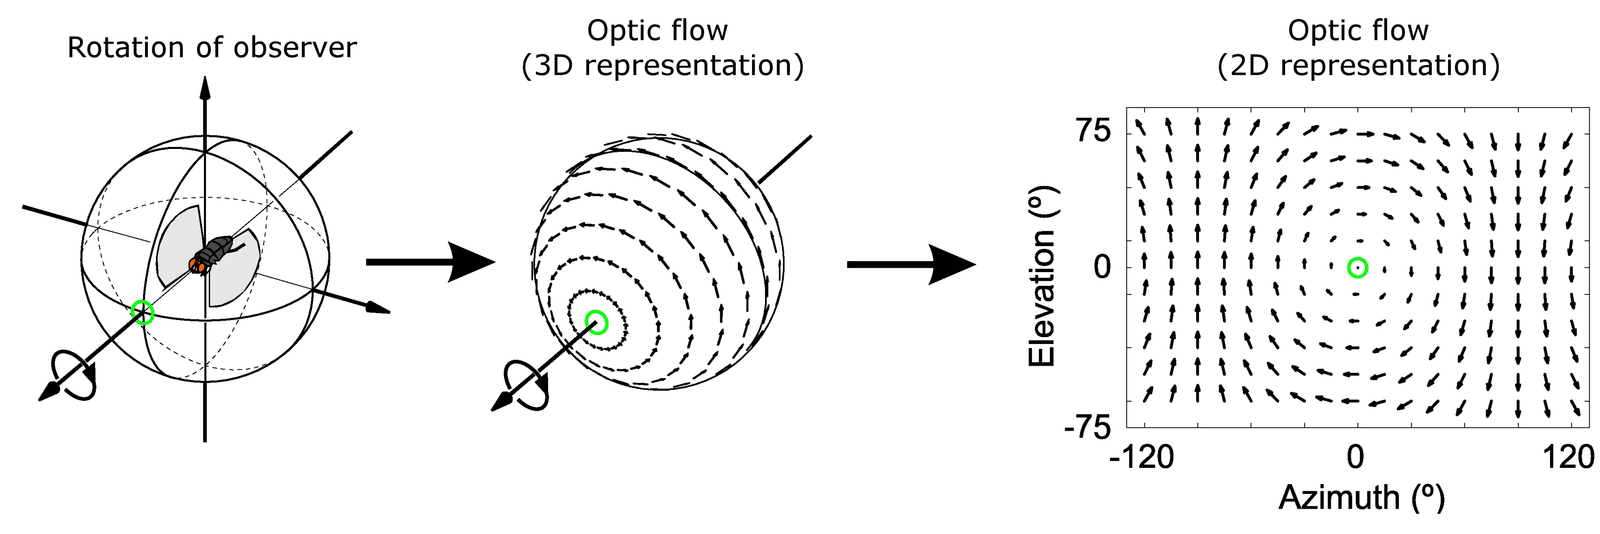
Optical Flow: Tracking Motion by Watching Pixels
Optical flow tracks motion by watching how brightness patterns move between video frames. It's used for video compression and robot navigation. The main footgun is that it can mistake lighting changes, like a shadow moving, for actual object motion.
Background Subtraction: Finding What's Moving in Video
Think of a security camera that has memorized the empty room. Background subtraction digitally 'subtracts' this static view from the live feed, leaving only moving objects. It’s used to spot intruders or count cars, but fails if the background itself changes.
Frame Differencing: The Simplest Way to See Motion
See motion by subtracting one video frame from the next; what's left over is what moved. This is used for simple motion detection but is easily fooled by lighting changes or camera shake, which it misinterprets as movement.
Intersection over Union (IoU): How Good is Your Bounding Box?
Intersection over Union (IoU) scores how well a predicted box matches the real one by dividing their overlap area by their total area. It's vital for object detection in self-driving cars and medical imaging.
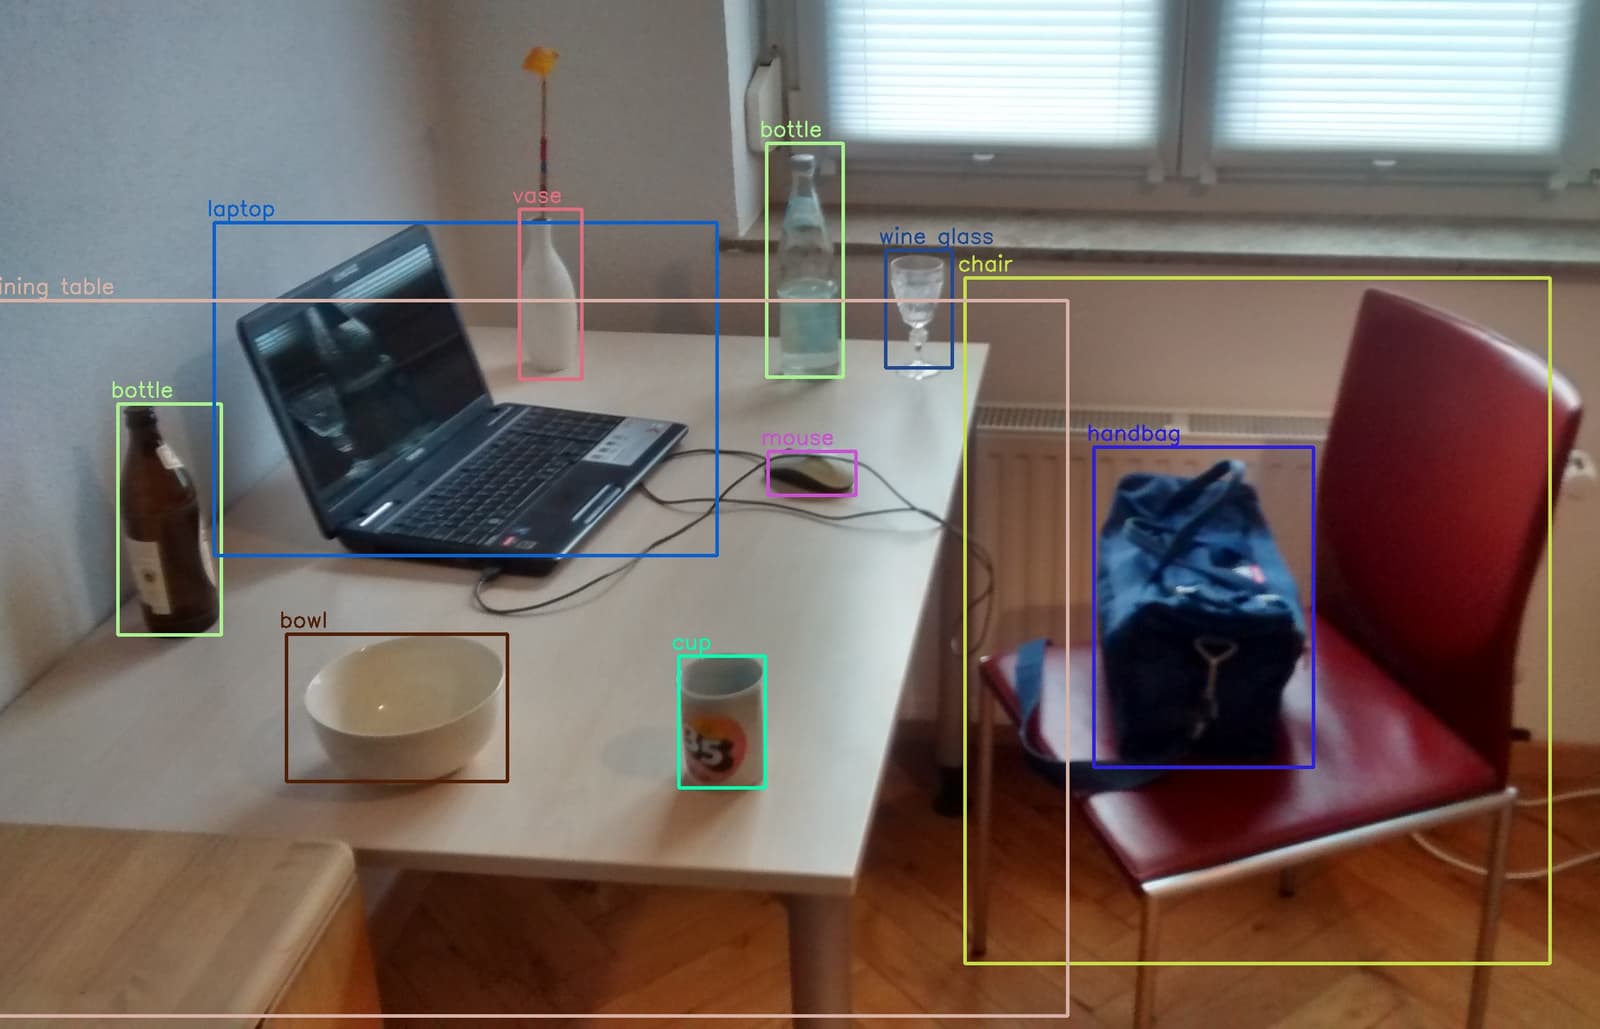
Localization vs. Detection: One Box or Many?
Object localization draws one box around an image's main object. Object detection finds and boxes *every* instance of a class, like all pedestrians. Use localization for single-subject tasks, detection for finding everything.
Pooling Layers: Summarizing What Matters in an Image
A pooling layer is like squinting at an image; you lose fine detail but see the main shapes. It summarizes features in a region, reducing computation and making the model robust to small shifts.
Feature Maps: What a Neural Network 'Sees'
A feature map is the output of a filter in a neural network, highlighting where a specific pattern (like an edge or curve) appears. In CNNs, each layer generates dozens of these maps. The footgun is thinking one map sees an object, not just a.
Convolutional Layers: Finding Features Anywhere
A convolutional layer is like a flashlight sliding over an image, looking for a specific pattern like an edge or corner. It's the core of computer vision, letting networks find features anywhere.
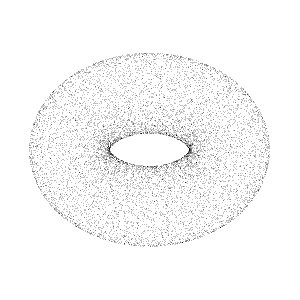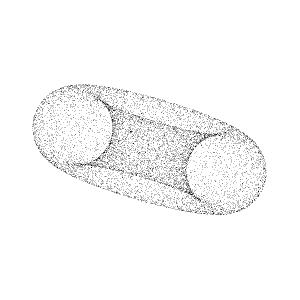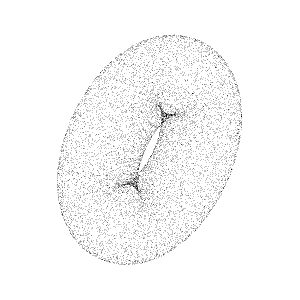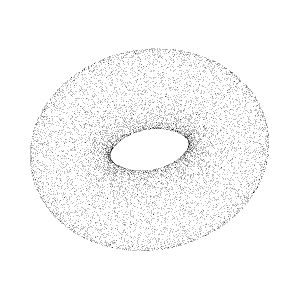
Point Cloud: A 3D Shape as a Dust Cloud of Data
A point cloud represents a 3D object as a cloud of individual data points in space. It's the raw output from 3D scanners, used to create CAD models or GIS maps. The footgun is assuming it's a solid model; it has no surfaces, only disconnected.
Disparity Map: Seeing Depth from Two 2D Images
A disparity map is a grayscale image encoding 3D depth from two 2D images. Brighter pixels mean objects are closer, because they appear to shift more between the left and right camera views. This is key for robotics and autonomous navigation.
The Stereo Correspondence Problem: How Cameras See in 3D
The stereo correspondence problem is how computers see in 3D, like your two eyes. It involves matching the same point in a left and right image to calculate depth. This is key for self-driving cars and robotics. The footgun: textureless walls create ambiguity.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles