Advanced concepts in Analytics & Metrics, page 2

Simpson's Paradox: When Averages Mislead
Simpson's Paradox is when a trend seen in separate groups reverses when you combine them. This happens when a hidden variable, like user experience level, skews the results, making a bad feature look good overall. Always segment your data to avoid this trap.

Principal Component Analysis (PCA)
PCA finds the most informative axes in your data, letting you compress many features into a few "principal components." Use it to visualize high-dimensional datasets or preprocess features for machine learning, but beware: the components are hard to interpret.
Time Series Decomposition: Separating Signal from Noise
Time series decomposition breaks a metric into its core parts: long-term trend, repeating seasonal patterns, and random noise. This helps you understand *why* a metric changed—was it a real shift or just the usual holiday rush?
Bayesian Inference: Updating Beliefs with Data
Bayesian inference formalizes learning from experience, updating your belief in a hypothesis as you gather evidence. It's used in A/B testing and medical diagnostics. The footgun is that a poor initial belief (the prior) can skew your conclusions.
ANOVA: Comparing Group Averages by Analyzing Spread
ANOVA checks if group averages are different by comparing the spread *between* groups to the spread *within* them. It's used to see if three ad campaigns yield different click-through rates.
Statistical Power: Detecting Real Effects in Your Tests
Think of statistical power as your experiment's sensitivity. It's the probability of detecting a real effect, like a true lift in an A/B test. The main footgun is running a low-power test, which will likely miss a real improvement and lead you to discard good.
Bootstrapping: Quantifying Uncertainty with Resampling
Bootstrapping estimates uncertainty by resampling your own data. It's used to find confidence intervals for complex stats like medians where no simple formula exists. The footgun: it can't fix a biased sample, only reveal the uncertainty within it.

The Multiple Comparisons Problem
Running many statistical tests on one dataset is like buying many lottery tickets; your chance of a "winning" false positive increases with each test. This happens in A/B tests with many metrics.
Multi-Armed Bandit: The Explore vs. Exploit Trade-off
A multi-armed bandit algorithm balances exploring new options with exploiting the current winner, like a gambler trying slot machines to find the best payout.
Isolating Impact with Difference-in-Differences (DiD)
Difference-in-Differences (DiD) isolates an intervention's true effect by comparing a treatment group's change over time to a control group's. This reveals if a new feature truly boosted engagement, not just rode a general upward trend.
Regression Discontinuity Design (RDD)
RDD finds a natural experiment at a cutoff point, like a test score threshold for a scholarship. By comparing people just above and below the score, you can estimate the program's effect. The footgun is assuming this local effect applies to everyone.
Instrumental Variables: Isolating True Cause and Effect
Instrumental Variables (IV) isolate true causality when a key variable is tainted by hidden factors. An IV is a "clean" substitute that influences your cause without directly touching your effect, letting you measure the true relationship, free from…
Propensity Score Matching: Mimicking an A/B Test
Propensity Score Matching (PSM) mimics a randomized trial with observational data by finding a "statistical twin" for each subject. It's used to estimate a feature's impact when a true A/B test isn't possible. The footgun is assuming it removes all bias.
ARIMA: Forecasting by Modeling Autocorrelation
ARIMA models forecast a time series by learning its "memory"—how past values influence the next. It's used for forecasting sales or server load where patterns are driven by internal dynamics.

Granger Causality: Forecasting, Not Causing
Granger Causality tests if one time series can forecast another, not if it causes it. It's used in econometrics to see if money supply changes predict inflation. The footgun is the name itself: it only shows predictive power, not true cause-and-effect.

LSTMs: Giving Neural Networks a Long-Term Memory
LSTMs give neural networks a selective memory, letting them remember important information over long sequences. This is key for language translation or time-series forecasting where old context matters.
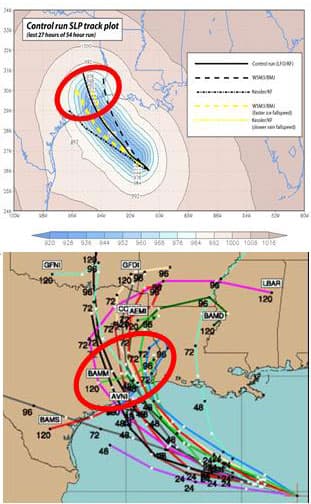
Ensemble Forecasting: Predicting with a Crowd of Models
Instead of one 'best guess,' ensemble methods generate many forecasts to map the range of possibilities. This is crucial for complex systems like weather prediction, where a single model is misleadingly precise.
Marketing Mix Modeling (MMM): Isolating Marketing's Impact on Sales
Marketing Mix Modeling (MMM) statistically links aggregate marketing efforts to sales outcomes over time. It's used to determine the ROI of past campaigns, like a TV ad blitz. The main footgun: the model is only as good as the historical data you feed it.
Business Analytics vs. Business Intelligence
Business Analytics predicts the future and prescribes actions, while Business Intelligence describes the past. BI reports last month's sales; BA forecasts next month's demand.
Workforce Analytics: Data-Driven People Decisions
Workforce Analytics applies systematic data analysis to people-related decisions, moving beyond gut feelings for hiring and promotions. It's used to predict turnover or measure training ROI.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles