Concepts in Computer Vision, page 2
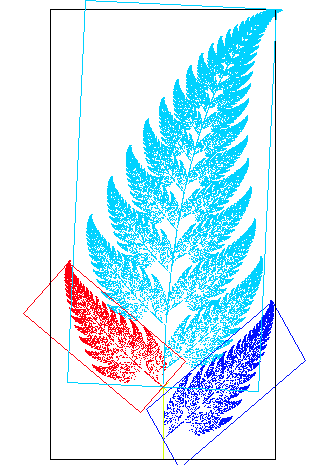
Affine Transformations: Move, Scale, and Rotate Without Bending
An affine transformation is a way to move, scale, rotate, or shear an object while keeping all lines straight and parallel lines parallel. It's used everywhere in computer graphics.
Laplacian of Gaussian (LoG) for Blob Detection
LoG finds blobs by blurring an image then finding points of maximum curvature, like finding the top of a hill by looking where the slope changes fastest. It's used in medical imaging and astronomy. The footgun: the blur size dictates the blob size you can.
Harris Corner Detector: Finding Sharp Changes in Images
The Harris detector finds corners by looking for points where image intensity changes sharply in all directions. It's used in image stitching and object tracking to find stable feature points. A key weakness is its sensitivity to image scale.
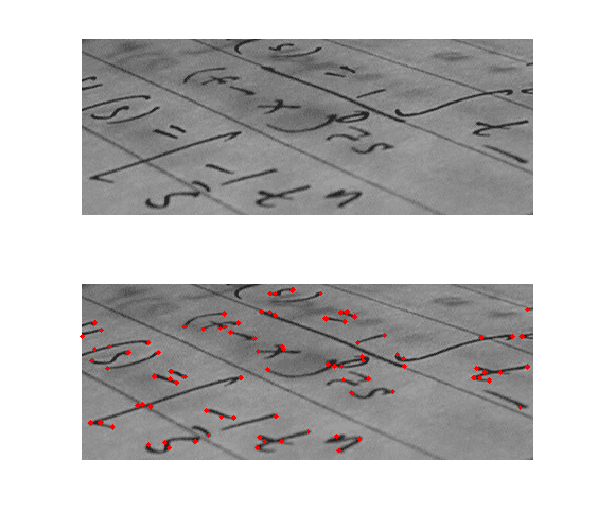
Corner Detection: Finding Stable Points in Images
Corner detection finds stable reference points in an image by looking for areas where pixel intensity changes sharply in multiple directions. It's used to track objects in video, stitch panoramas, and recognize objects by their features.
Hough Transform: Finding Shapes by Voting
The Hough Transform finds shapes by letting pixels "vote" for all lines or circles they could belong to. It's used to detect features like road lanes in noisy images.
Scale-Space: Analyzing Images at Multiple Scales
Scale-space representation is like viewing an image from far away and up close simultaneously. It creates a stack of progressively blurred images to reveal structures at different sizes, which is key for robust feature detection.
Difference of Gaussians: Finding Edges by Subtracting Blurs
Difference of Gaussians (DoG) finds features by subtracting a heavily blurred image from a lightly blurred one, isolating details at a specific scale. It's used for fast blob and edge detection.
FAST: High-Speed Corner Detection for Real-Time Vision
FAST finds corners by checking if a pixel is significantly brighter or darker than a ring of its neighbors. This simple, high-speed test makes it perfect for real-time video processing.
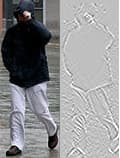
Histogram of Oriented Gradients (HOG)
HOG describes an object's shape by summarizing the directions of local intensity changes (gradients). It's a classic computer vision method for tasks like pedestrian detection where form matters more than color.
SIFT: Finding Image Features That Scale
SIFT finds key points in an image that are stable across changes in scale. It's used for object recognition or stitching panoramas by matching these features between images. The main footgun is assuming it's invariant to all changes, not just scale.
SURF: A Faster, Patented Alternative to SIFT
SURF is a faster, more robust alternative to SIFT for finding key points in an image. It's used for real-time object recognition or stitching images where SIFT is too slow. Beware: its core algorithms are patented, limiting commercial use without a license.
ORB: Fast, Free Feature Detection for Computer Vision
ORB combines the speedy FAST keypoint detector with a rotation-aware BRIEF descriptor. It offers a fast, royalty-free alternative to SIFT for finding and describing unique points in an image, even when the object is rotated.
Local Binary Patterns (LBP) for Texture Classification
LBP is a 'visual descriptor' that summarizes an image's texture into a feature set for a machine to read. It's a powerful tool for texture classification, but its performance often improves significantly when combined with other descriptors like HOG.
FLANN Matcher for Feature Correspondence
OpenCV's FLANN matcher pairs query and train descriptors to find cross-image feature correspondences as an alternative to Brute-Force. Engineers often assume FLANN shares Brute-Force's normType and crossCheck parameters, causing silent configuration errors…

Epipolar Geometry: Finding 3D Points from 2D Images
Epipolar geometry finds a 3D point from two 2D views by constraining the search. Instead of scanning the whole second image for a match, you only look along a single line. It's key for 3D reconstruction. The footgun is assuming perfect pinhole cameras.
The Stereo Correspondence Problem: How Cameras See in 3D
The stereo correspondence problem is how computers see in 3D, like your two eyes. It involves matching the same point in a left and right image to calculate depth. This is key for self-driving cars and robotics. The footgun: textureless walls create ambiguity.
Disparity Map: Seeing Depth from Two 2D Images
A disparity map is a grayscale image encoding 3D depth from two 2D images. Brighter pixels mean objects are closer, because they appear to shift more between the left and right camera views. This is key for robotics and autonomous navigation.
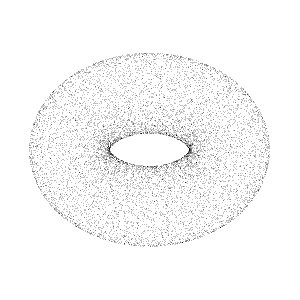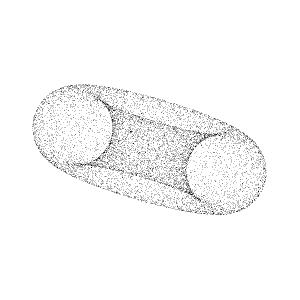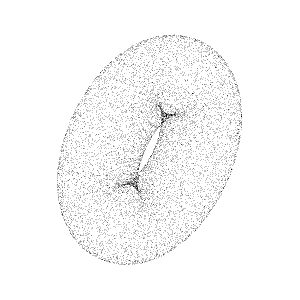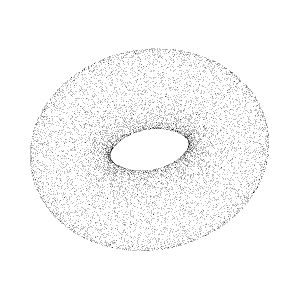
Point Cloud: A 3D Shape as a Dust Cloud of Data
A point cloud represents a 3D object as a cloud of individual data points in space. It's the raw output from 3D scanners, used to create CAD models or GIS maps. The footgun is assuming it's a solid model; it has no surfaces, only disconnected.
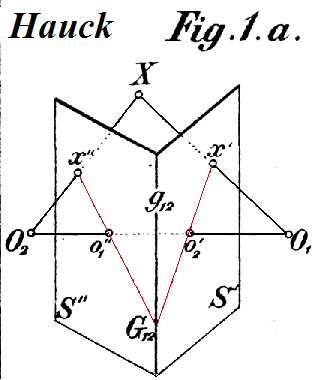
Homography: Mapping Flat Surfaces Between Images
A homography is a 3x3 matrix that maps points between two images of a flat surface. It's used for panorama stitching and perspective correction. The footgun: it only works for planes or pure camera rotation, failing on scenes with depth.
The Fundamental Matrix: Constraining 3D Search to a Line
The Fundamental Matrix reduces a 2D search for a point in a second image to a 1D search along a line. It's the geometric glue linking two uncalibrated camera views of the same scene, crucial for stereo vision and 3D reconstruction.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles