Concepts in Computer Vision, page 8
Data Labeling: Teaching Computers How to See
Data labeling is like creating flashcards for an AI. You show it an image and explicitly tell it what's important, like 'this is a cat.' It's essential for training models for self-driving cars or medical imaging.
Confusion Matrix: Grading Your Model's Predictions
A confusion matrix is a scorecard showing how a classification model gets confused. It grids predicted labels against actual labels to reveal specific error types. It's essential for diagnosing failures that overall accuracy metrics might hide.

Precision vs. Recall: The Classifier's Trade-off
Precision is the quality of your positive predictions; Recall is the quantity you find. A spam filter with high precision avoids false alarms, while high recall catches most spam.
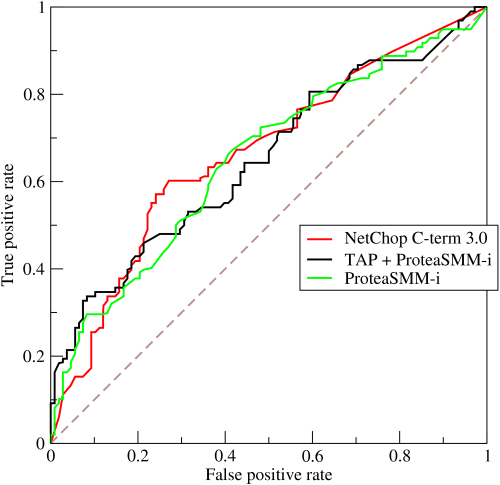
ROC Curve and AUC: Measuring Classifier Performance
An ROC curve visualizes a classifier's trade-off between catching true positives and flagging false ones across all thresholds. It's used to evaluate models like medical diagnostics or spam filters.
Model Quantization: Trading Precision for Performance
Model quantization trades numerical precision for a smaller memory footprint. It reduces model weights from high-precision types like fp32 to lower ones like int8 or int4, making large models fit on consumer hardware.
ONNX: The Universal Translator for ML Models
ONNX is a universal translator for ML models, letting you train in one framework (like PyTorch) and run in another. It's used to deploy models to diverse hardware without rewriting them.
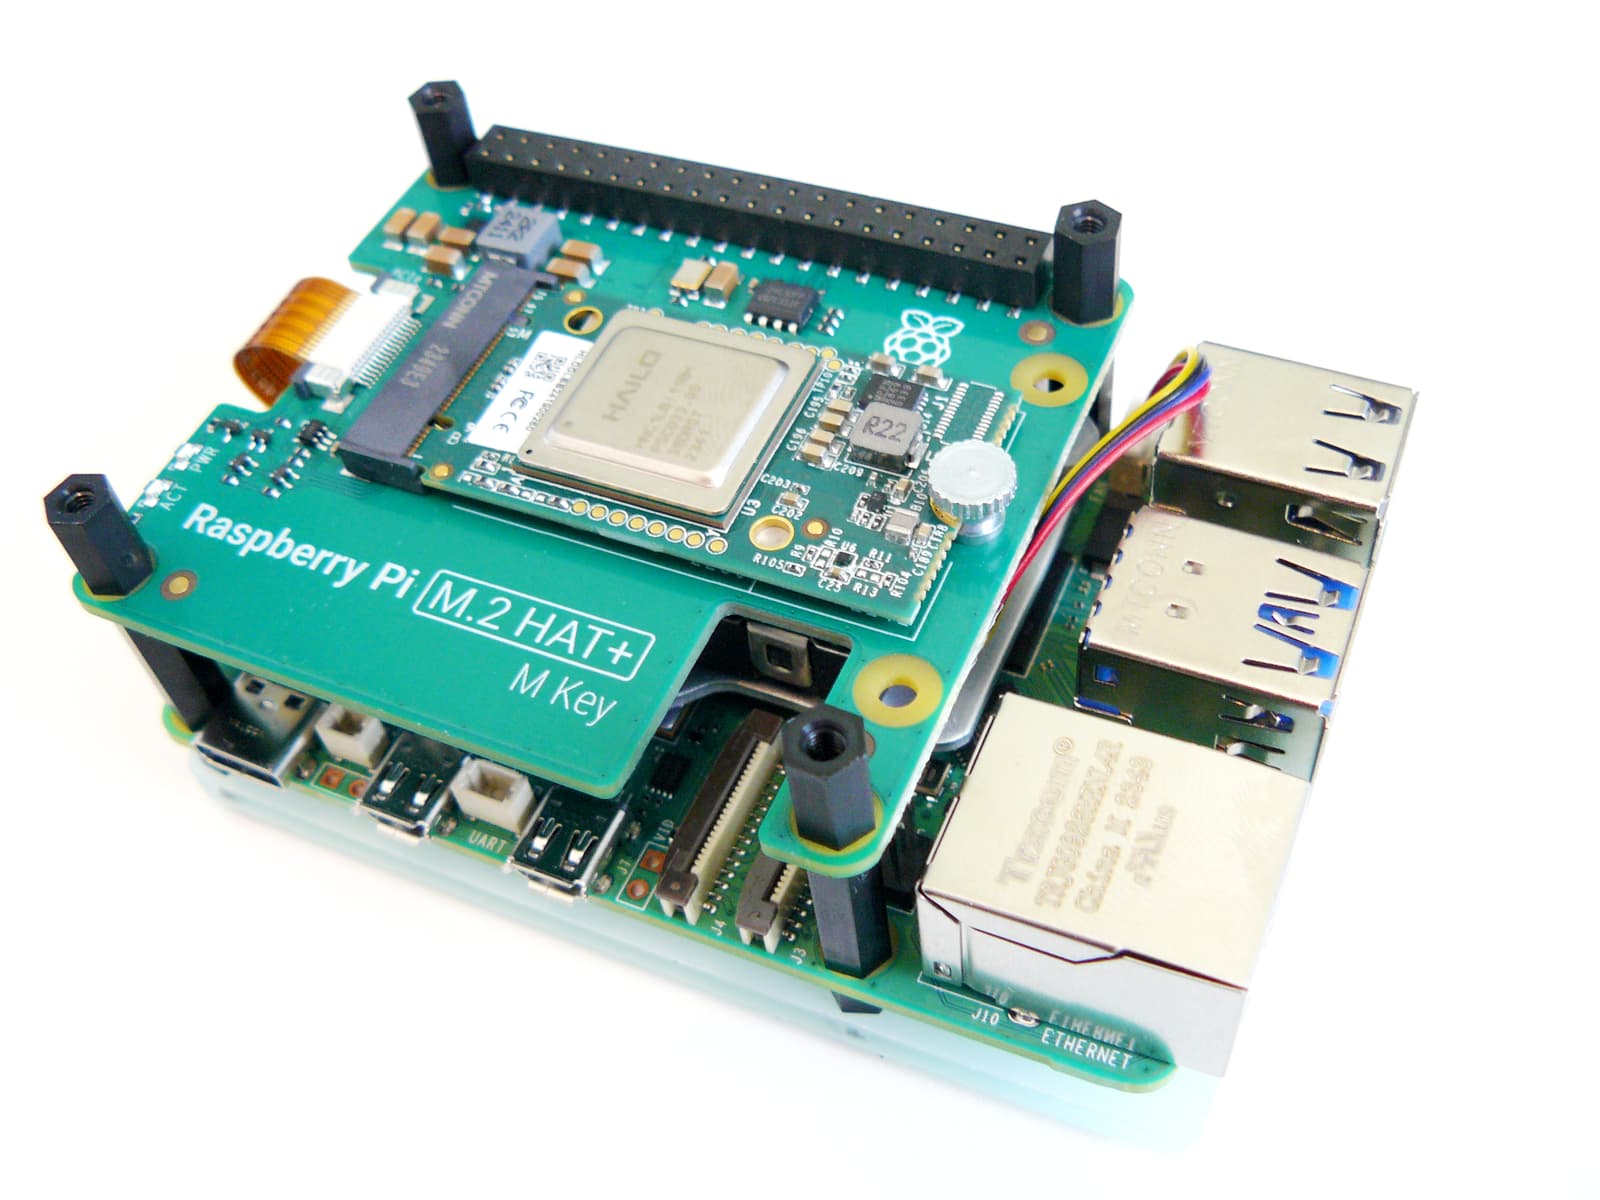
Edge AI Accelerators: Inference Without the Cloud
An Edge AI accelerator is a specialized, low-power chip that runs AI models directly on a device, skipping the cloud. It's used for real-time tasks like object detection where latency and privacy are critical.
Knowledge Distillation: Shrinking Models, Not Performance
Knowledge Distillation trains a small "student" model on the nuanced outputs of a large "teacher" model. This is how huge, accurate models are shrunk to run on phones. The footgun is assuming performance is identical; there's always a trade-off.
TensorRT: From Trained Model to Production Speed
TensorRT is a compiler that turns a trained model into a specialized, high-speed engine for a specific NVIDIA GPU. It's used to deploy models in production where low latency is critical.
FPGA in Computer Vision
An FPGA is reconfigurable silicon wired into a custom digital circuit rather than programmed as instructions, letting a vision pipeline like demosaicing and feature extraction run in dedicated hardware with low latency and high throughput per watt.
Image Thresholding: Separating Foreground from Background
Image thresholding turns a grayscale image into black and white by setting a brightness cutoff. It's used to isolate features for analysis, like finding text on a page.

Perspective Transformation: Making 3D Look Right on a 2D Screen
Perspective transformation is like looking through a camera lens; it makes distant objects smaller to create the illusion of depth on a flat screen. It's essential for 3D games and computer vision.
BRIEF: Fast, Compact Binary Feature Descriptors
BRIEF describes image features as a compact binary string instead of a complex vector. This makes it extremely fast for real-time matching on low-power devices. The footgun: its raw form isn't rotation-invariant, trading that robustness for raw speed.
Sliding Windows: Scanning Images for Objects
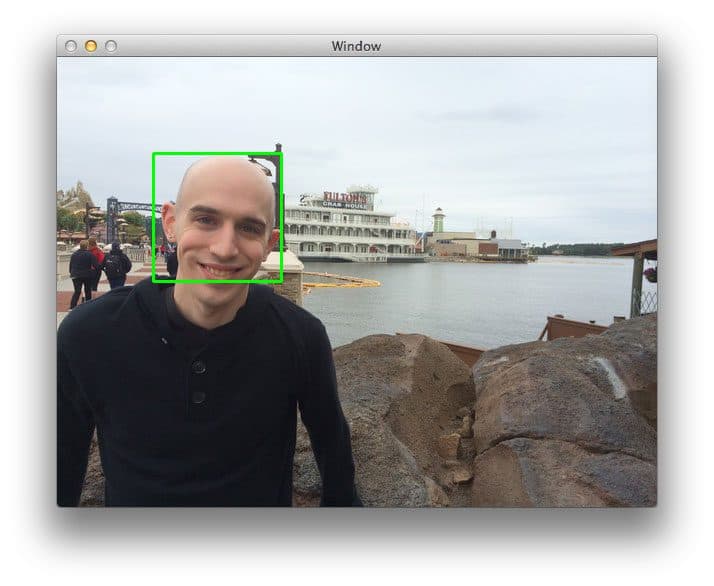
A sliding window scans an image with a fixed-size box to find objects. At each location, a classifier checks the window's contents. Combined with an image pyramid, it can detect objects at various scales, localizing exactly where they are.
Anchor Boxes: Pre-defined Guesses for Object Detection
Anchor boxes are predefined 'template' boxes of various sizes and shapes. Object detection models use them as a starting point, predicting how to shift and scale these templates to fit actual objects, making detection faster.
Watershed Algorithm: Segmenting by Topography
The watershed algorithm treats an image as a landscape where pixel brightness is height. It finds the 'ridges' separating distinct 'valleys,' effectively segmenting touching objects. Its main footgun is extreme sensitivity to noise, causing over-segmentation.
U-Net: Encoder-Decoder for Image Segmentation
U-Net segments images by first compressing them to capture context, then expanding to localize features precisely. It excels in biomedical imaging where annotated data is scarce.
Self-Attention: How Models Weigh Word Importance
Self-attention lets a model weigh the importance of all words in a sequence simultaneously, asking "which other words are most relevant?" It's the core of Transformers, enabling parallel processing for tasks like translation, unlike sequential RNNs.
Autoregressive Models: Generating Images One 'Word' at a Time
Autoregressive models generate images sequentially, like writing a sentence word by word. Each new pixel or patch depends on what came before. This creates high-fidelity images but is much slower than one-shot models, a key trade-off in generative AI.
Semantic Scene Classification: Understanding Context, Not Just Objects
Scene classification tells you the context of an image ("this is a forest"), not just the objects in it ("there's a tree"). It's used by self-driving cars to identify a highway vs. a residential street and by apps to organize photos.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles