Concepts in MLOps & Infrastructure, page 4
NVIDIA Triton: A Universal AI Model Server
Triton Inference Server is like a universal remote for AI models, providing a standard API to serve models from any framework. Use it to deploy diverse models (PyTorch, ONNX) without custom serving stacks.

Load Balancing for Model Serving
A load balancer is a traffic cop for your AI model's API, directing requests to multiple model copies to prevent overload. It's essential for production systems to ensure high availability. The footgun is forgetting health checks, causing failed requests.
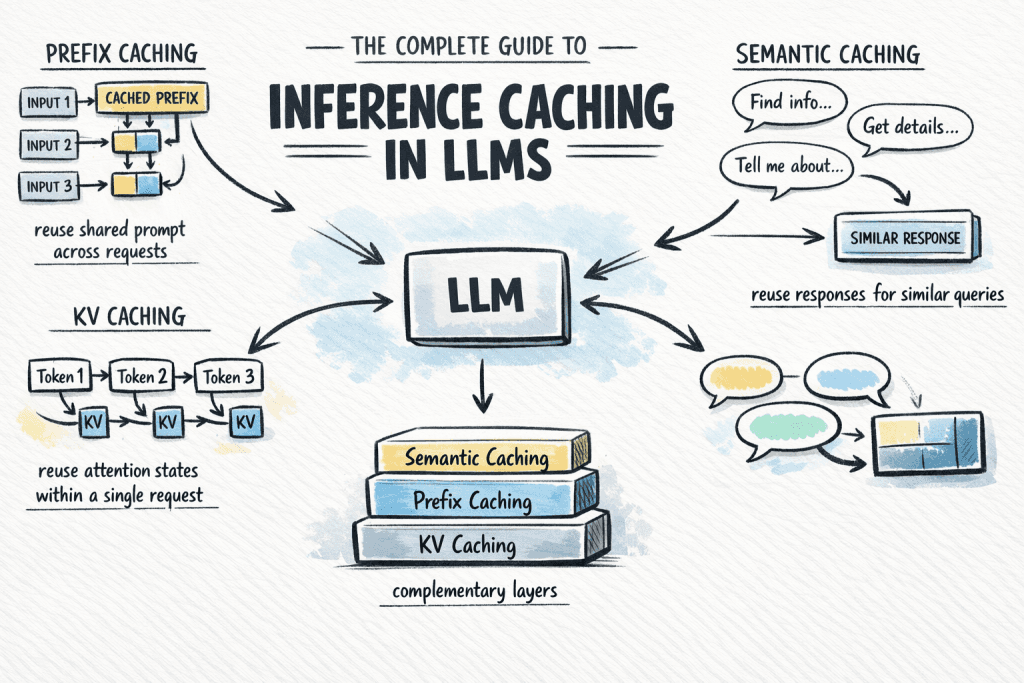
LLM Inference Caching: Pay for Computation Once
LLM inference caching reuses past computations to cut costs and latency. It avoids reprocessing shared system prompts or serves full answers for common queries without hitting the model. The footgun: semantic caches can return a "similar" but incorrect answer.
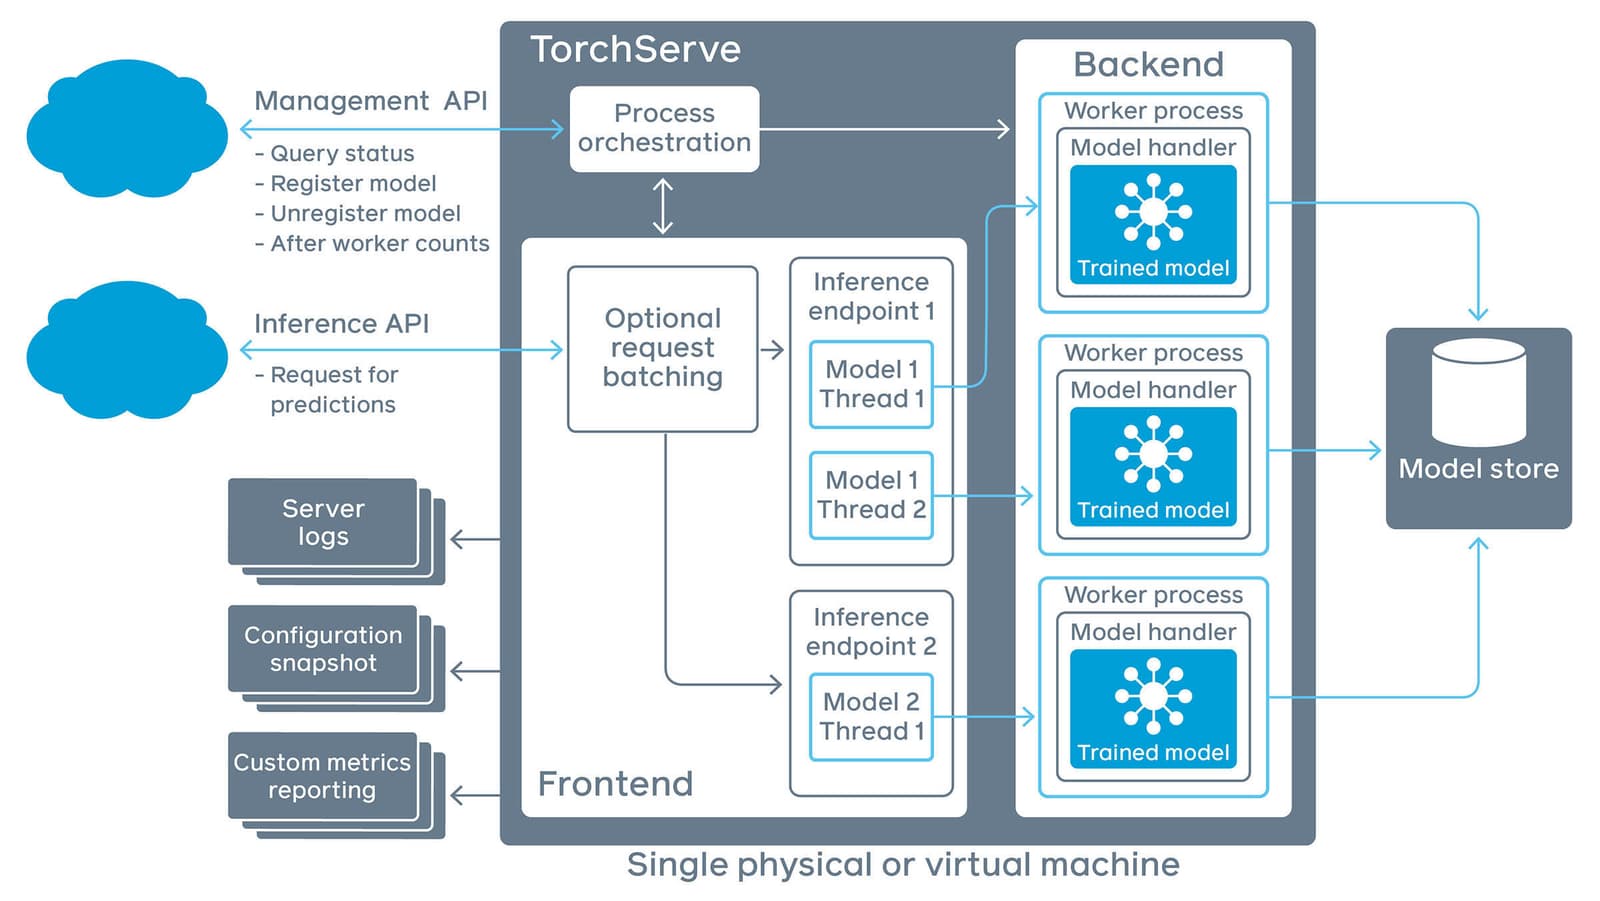
TorchServe: Serving PyTorch Models in Production
TorchServe is a web server for your PyTorch models, turning them into production-ready API endpoints. It's used to expose trained models over a network via REST or gRPC for inference, handling batching and multi-model serving.

Inference Batching: Grouping Requests for Throughput
Think of inference batching as a carpool for your ML model. Instead of sending each request in its own car, you wait a few microseconds to fill a bus, dramatically improving GPU efficiency.

Autoscaling ML Inference Endpoints
Autoscaling matches your ML model's compute to real-time demand, like an elastic container for your inference service. It handles spiky traffic for online endpoints, scaling up for peaks and down to save costs.
BentoML: Packaging Models for Production APIs
BentoML is a standardized shipping container for your ML models, packaging them into production-ready API endpoints. Use it to deploy LLMs or RAG systems without managing complex infrastructure. Its focus is purely on inference, not model training.
Model Pruning: Making ML Models Smaller and Faster
Model pruning is like trimming a bonsai tree; you remove the least important weights to create a smaller, faster model. It's essential for running large models on devices like smartphones, but over-pruning can irreversibly damage accuracy.
Model Compilation: Bridging Models and Hardware
An ML compiler translates a model's abstract math into optimized instructions for specific hardware. This lets you run the same model efficiently on cloud GPUs, mobile CPUs, or edge devices.
Multi-Model Serving: Packing More Models into Less RAM
Multi-model serving is a carpool for your ML models. Instead of one server per model, you pack many into a single process to share resources and cut costs. It's ideal for serving many models with intermittent traffic.

Inference Throughput: How Many Predictions Per Second?
Inference throughput measures how many predictions your system can make per second, not how fast a single one is. It's the system's total capacity, critical for high-volume tasks like recommendation engines. The footgun is confusing it with latency.
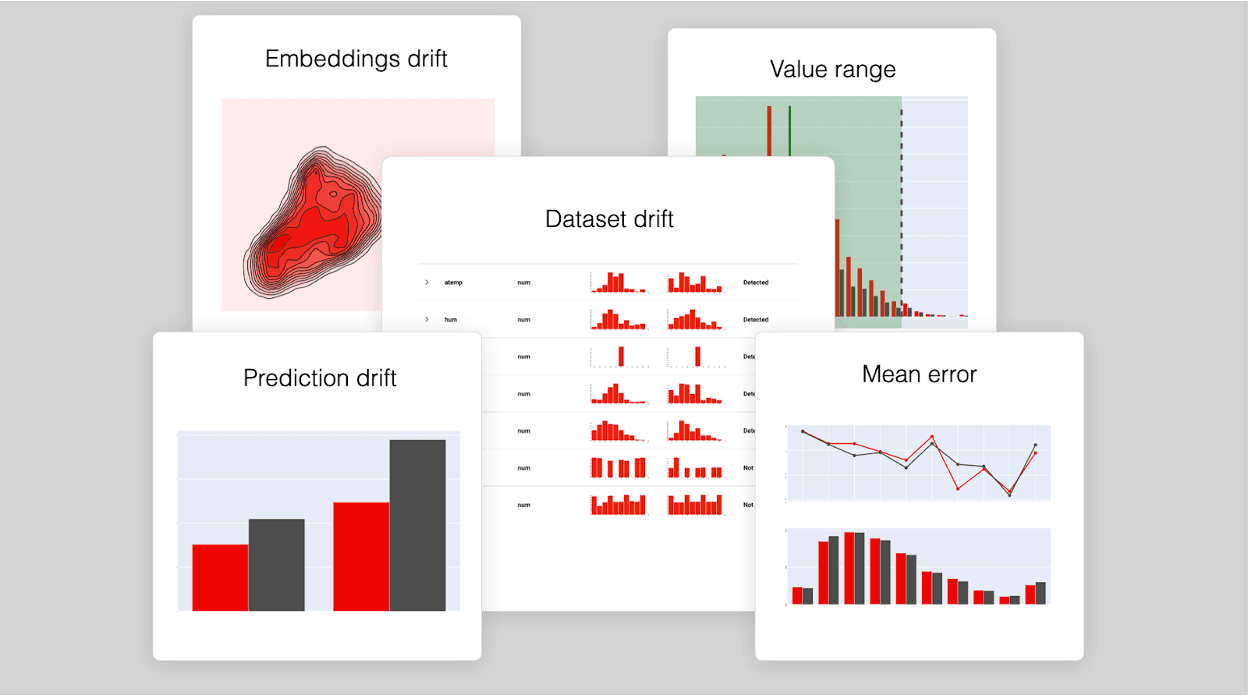
ML Monitoring Dashboards: Your Model's Health Chart
An ML monitoring dashboard is a health chart for your production model, showing how its performance decays. It tracks silent failures like data drift or concept drift, where user behavior changes and makes your model obsolete.

Population Stability Index (PSI): Quantifying Data Drift
The Population Stability Index (PSI) gives you a single number to quantify data drift between training and live data. It's used in MLOps to monitor model health, especially in finance. The footgun is ignoring a high PSI, which signals silent prediction decay.
Logging Model Explanations, Not Just Predictions
Log *why* your model makes a prediction, not just the output. This captures the model's reasoning, creating a debuggable audit trail. It's essential for diagnosing model drift and ensuring fairness.
DDM: Detecting Drift with Error Rate Statistics
DDM acts as a statistical alarm on your model's error rate, watching for spikes that signal the underlying data has changed. Use it for online binary classification with immediate feedback, like spam filtering.
Workflow Engine: The Conductor for Your Business Logic
A workflow engine conducts your business logic, ensuring complex tasks run in the right order. It's for multi-step processes like order fulfillment or data pipelines. The footgun is building one from scratch—you'll poorly reinvent state management and retries.
TensorFlow Extended (TFX): Production ML Pipelines
TFX is an end-to-end platform for building production ML pipelines, like an assembly line for your models. It automates data validation, training, analysis, and serving. The footgun: TFX is not one tool, but a suite of libraries you must learn and connect.
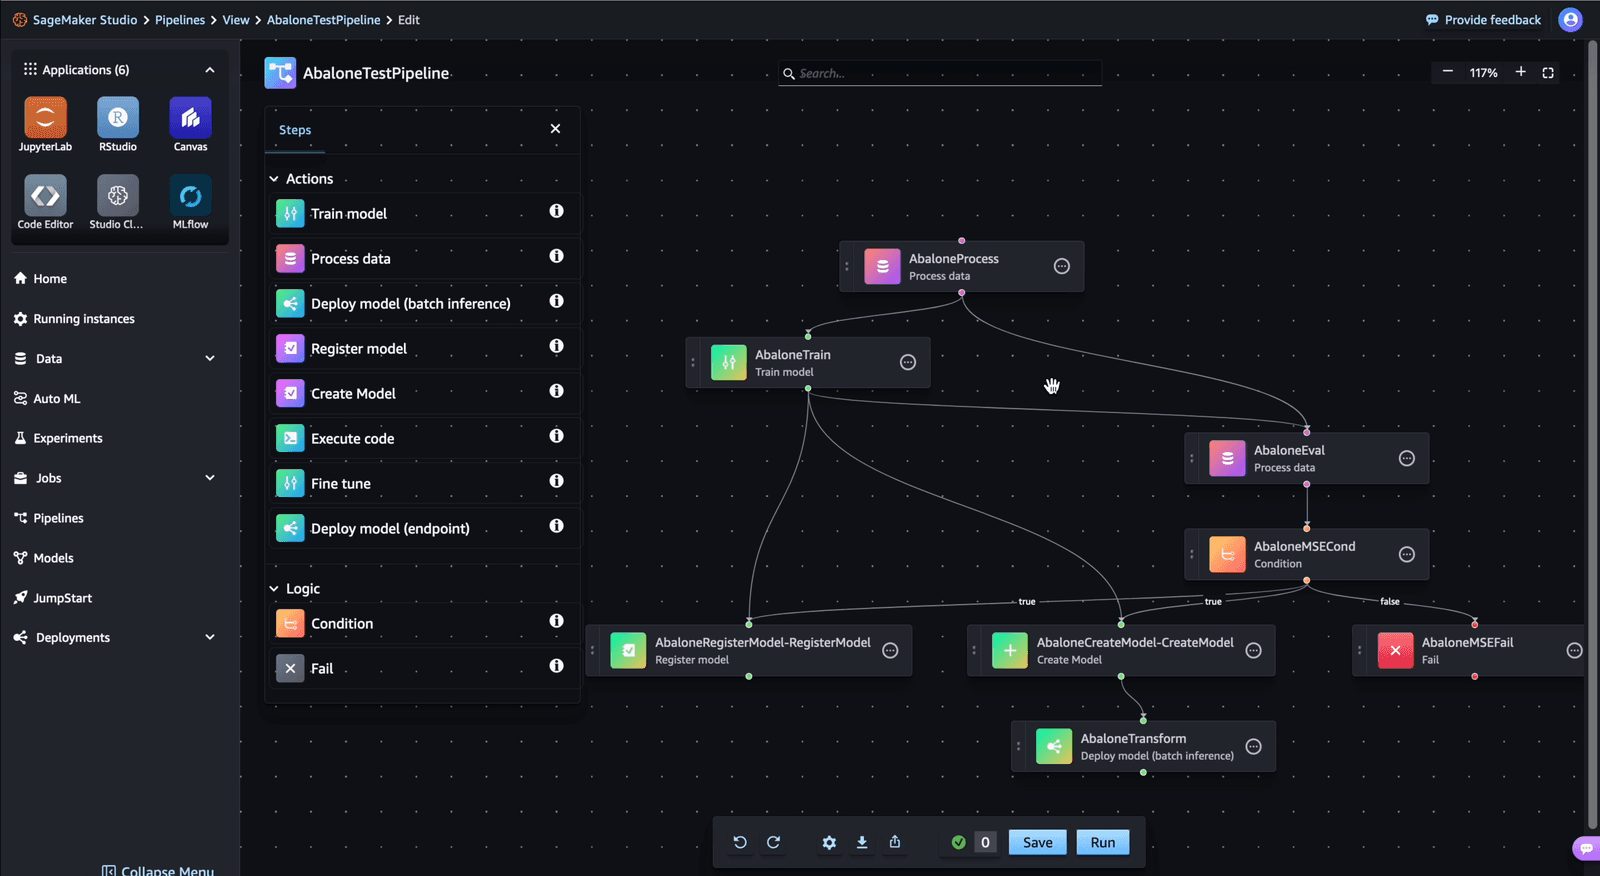
Amazon SageMaker Pipelines: Repeatable ML Workflows
Think of SageMaker Pipelines as a CI/CD pipeline for ML models, automating workflows from data prep to deployment. Use it for reproducible training and automated retraining.
Vertex AI Pipelines: Orchestrating ML Workflows
Think of it as an assembly line for your machine learning models, automating everything from data prep to deployment. Use it to build reproducible, production-grade ML systems on Google Cloud.
Argo Workflows: Run Complex Jobs on Kubernetes
Think of Argo Workflows as a script runner for Kubernetes, where each command is a container. It runs multi-step jobs like CI/CD or ML pipelines. The footgun is treating it like a full CI server; it's just an engine and lacks features like Git polling.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles