Interview questions in Product Management, page 27
How do you measure forecast accuracy and compare MAE to RMSE?
This tests out-of-sample validation and how MAE and RMSE weight errors. A strong answer demands a train-test split, defines both, and notes RMSE punishes outliers more while MAE is more robust. A red flag is citing in-sample fit instead of held-out error.
How would you apply RICE scoring to prioritize these three initiatives?
This tests translating technical tradeoffs into quantified RICE scores. A strong answer maps Reach to users, Impact to latency or revenue, Confidence to data quality, and Effort to person-weeks. Red flag: uniform confidence or vague t-shirt sizing.
How would you design international monetization with multi-currency and tax?
Localized pricing, jurisdictional tax, gateway routing, async reconciliation.
Describe the initial columns for a new Kanban board and their purpose
Tests whether you understand Kanban as a flow visualization tool. A strong answer names Backlog, To Do, In Progress, and Done, explaining each as a handoff or state change. Red flag: adding too many columns upfront or conflating the board with Scrum.
How would you measure a sales forecast model's accuracy?
Tests if you can link statistical metrics to business outcomes. Define MAE (average error) and RMSE (penalizes large errors). Choose RMSE when large misses are costly (e.g., stock-outs), MAE otherwise. A red flag is reciting formulas without business context.
What columns would you set up on a new Kanban board?
Tests your grasp of workflow visualization, not just Agile terms. A good answer starts with To Do/In Progress/Done, then adds columns like Code Review to mirror the real process, and crucially, mentions setting WIP limits to manage flow and identify…
How would you measure a sales forecast model's accuracy?
This tests your ability to connect statistical metrics to business impact. A great answer defines MAE (linear error cost) and RMSE (penalizes large errors), explains the choice depends on business context, and stresses using a test set.
What initial columns would you set up on a Kanban board?
Tests your grasp of Kanban's core goal: visualizing workflow. Start with a simple board (To Do, In Progress, Done), explaining how each column represents a work state. A red flag is creating an overly complex board without justifying the need for each stage.
Stationarity in time series and why ARIMA needs it
Constant mean/variance/autocovariance; ARIMA's coefficients assume them; test with the ADF test and ACF plots; achieve it via differencing or log transforms.
Decide between cutting a feature versus taking technical debt for a deadline
Quantify business risk of both paths, secure buy-in, and lock a time-boxed post-launch remediation plan.
How would you instrument a key activation milestone event?
Tests schema design beyond a bare event name. A strong answer includes the event key, user ID, timestamp, and properties like project_id and is_first_project. Red flag: omitting the user ID or sending only a human-readable label without structured context.

Lead Time vs Cycle Time in Kanban and measuring Cycle Time
Tests whether you distinguish customer wait time from active work. Strong answer: Lead Time is request-to-delivery with queues; Cycle Time is active start-to-finish measured from In Progress to Done. Red flag: treating them as synonyms or ignoring wait states.
Explain time series stationarity and how to achieve it
Tests your grasp of core time series assumptions. Define stationarity (constant mean/variance over time), explain why models need it for stable predictions, and name methods to test and achieve it. A red flag is just saying the data looks 'flat'.
Explain Lead Time vs. Cycle Time on a Kanban board
This tests your grasp of core Kanban flow metrics. Define Lead Time (customer request to delivery) and Cycle Time (work start to finish). Measure Cycle Time from the first 'In Progress' column to 'Done'. Red flag: defining terms without explaining their value.
Explain stationarity in a time series
This tests your grasp of core time series modeling assumptions. A strong answer defines stationarity (constant mean/variance), explains its importance for ARIMA (stable patterns), and names a test (ADF) and a fix (differencing).
Lead Time vs. Cycle Time in Kanban
Tests your understanding of core Kanban metrics for process improvement. Define Lead Time (request to delivery) and Cycle Time (work start to completion), noting Cycle Time is a subset. A red flag is confusing the two or being imprecise about start/end points.
Use Cost of Delay to decide which project to start first
Tests if you quantify economic burn rate of sequencing, not raw ROI. Calculate CoD by dividing monthly value by duration: Project B is $5k/mo, Project A is $2.5k/mo, so start B first. Red flag: static NPV or "quick win" logic without computing delay cost.
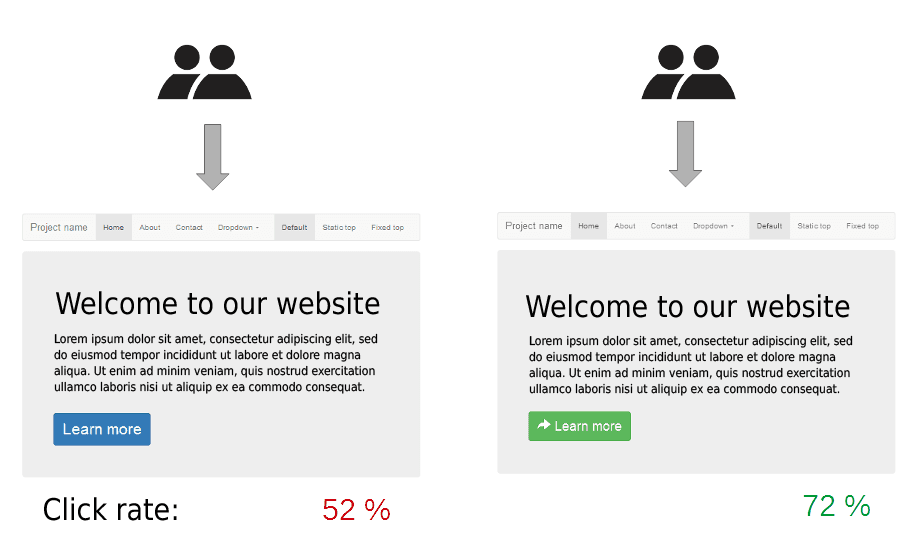
Implement a 10% onboarding tutorial feature flag and track success
Tests lightweight experiment design and metric selection beyond vanity numbers. Strong answers cover user-ID bucketing, conversion tracking, and guardrail metrics like drop-off. Red flag: manual toggles or click-through without downstream outcomes.
Random split vs walk-forward validation in forecasting
Random splits leak future data into training; walk-forward validation rolls the origin ahead, testing only on later observations.
How would you implement Classes of Service in Kanban?
Tests whether you segment work by risk and cost of delay. A strong answer defines explicit policies, visualizes classes with color or lanes, and reserves WIP capacity per class. Red flag: using classes as simple priorities without capacity rules.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles