Intermediate everything in Product Management, page 20
How do you create a 'golden record' from fragmented data?
Tests your ability to design a data reconciliation system. A great answer outlines a process: profiling sources, defining survivorship rules, implementing a matching engine, and creating a stewardship process. A red flag is suggesting a simple one-off script.
Handle Schema Evolution in a CDC Analytics Pipeline
This tests your ability to design robust data systems that anticipate change. A great answer includes a schema registry, compatibility rules, a dead-letter queue for non-compliant records, and automated alerting.
Explain data lineage and how you would implement it
This tests your ability to design for data observability. Define lineage (origin, transformation, movement), then propose a solution using metadata extraction (OpenLineage) and a central graph store/UI (Marquez) to trace data from microservices to analytics.
Data Warehouse vs. Data Lake vs. Lakehouse
Tests your grasp of modern data architectures. A great answer defines warehouses (structured, schema-on-write) and lakes (raw, schema-on-read), then explains how a lakehouse adds ACID transactions and governance on top of a lake.
What is data partitioning in a cloud data warehouse?
Tests your grasp of physical data layout optimization. A good answer defines partitioning as dividing a table by a column (e.g., date), then explains how this enables partition pruning to improve query speed and reduce cost by scanning less data.
Handling Late-Arriving Data in a Streaming Pipeline
Tests your grasp of event time vs. processing time. A great answer defines watermarks to track completeness, uses event-time windowing to group data, and sets triggers with allowed lateness to correctly incorporate out-of-order events.
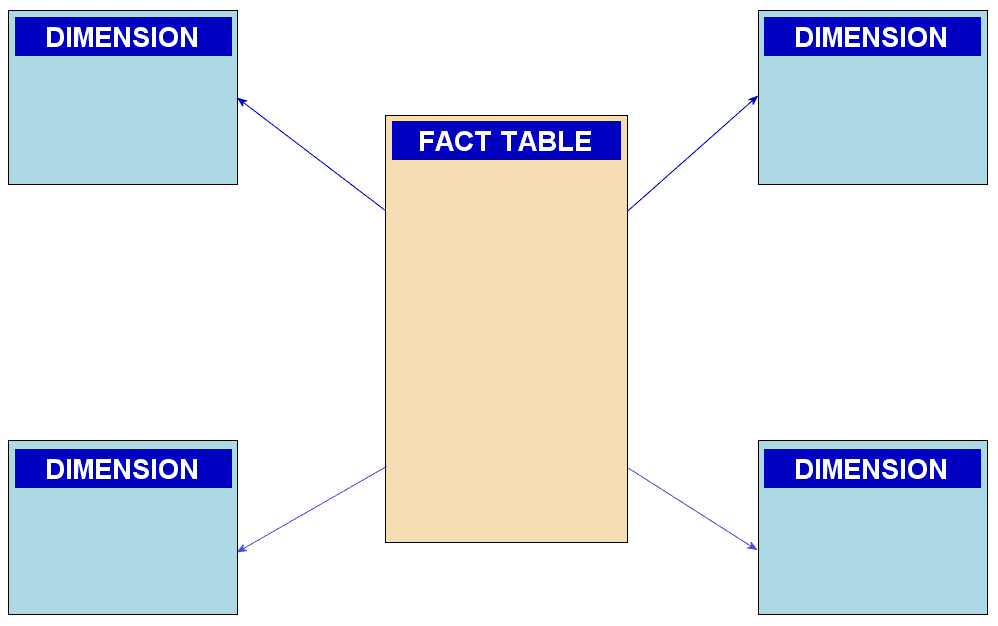
Star vs. Snowflake Schemas: Trade-offs
Tests your grasp of data warehouse design trade-offs. Define star (denormalized, fast queries) and snowflake (normalized, storage efficient) schemas. Explain the core trade-off: star's query speed vs. snowflake's storage/integrity.
How do you approach user identity stitching?
This tests your grasp of data architecture for analytics, not just a simple algorithm. A strong answer defines anonymous vs. known IDs, explains the backfilling/rekeying process upon authentication, and notes the need for a central event store.

Build vs. Buy: Third-Party Analytics SDK or In-House Pipeline?
This tests your grasp of the time vs. control trade-off. A great answer weighs the speed of buying against the total control of building, focusing on the hidden, long-term maintenance costs of an in-house solution.
Sudden metric drop, no recent deployments. What's the cause?
This tests your ability to debug data discrepancies beyond code, focusing on the analytics pipeline. First, distinguish data loss from misattribution. Then, check processing delays and hidden data sources. A red flag is not segmenting data first.
How do you track page views in a Single Page Application?
Tests your grasp of SPA navigation vs. traditional page loads. A great answer explains how SPA routers use the History API (pushState) and how to listen for changes to send analytics events. A red flag is suggesting polling the URL.

Explain the North Star Metric and propose one for a product
Tests your ability to connect user value to business outcomes. A great answer defines the NSM, proposes one for a product (e.g., Spotify), and justifies how it links customer value to business success. A red flag is picking a vanity metric like DAU or revenue.
How would you diagnose why a new feature isn't being adopted?
This tests your ability to diagnose a flat KPI. A great answer outlines a funnel (awareness, activation, usage) and combines quantitative data with qualitative insights from session replays. A red flag is proposing solutions without a diagnostic plan.
Pitfalls of 'Conversion Rate' as a North Star Metric
Tests your ability to see beyond a single metric. A good answer identifies how optimizing conversion can hurt revenue or UX, and proposes guardrails like Average Order Value, support tickets, and return rates.
AI Use Creates 'Cognitive Debt' in Scrum Teams
Over-relying on AI for sprint planning and backlog refinement creates "Cognitive Debt," eroding a team's problem-solving skills. While AI boosts productivity, it can eliminate the collaborative friction that builds shared understanding and critical reasoning.
How do you build a business case for technical debt?
This tests your ability to translate engineering problems into business impact. A strong answer quantifies the debt's cost (e.g., slower velocity), frames it as risk, and proposes a concrete payback plan like allocating 20% capacity.

Throughput vs. Velocity in Agile Planning
This tests your grasp of flow vs. estimation metrics. Define throughput as a count of delivered items and velocity as a sum of estimated points. Throughput measures actual output, making it better for forecasting. Red flag: claiming velocity is more accurate.

How do you coach a team to self-management?
Tests your grasp of situational leadership. A great answer uses a maturity model like Tuckman's stages to show how your coaching evolves from directive teaching (Forming) to strategic advising (Performing), and explains which techniques you retire.
How do you handle wildly fluctuating team velocity?
Tests if you know velocity is for team planning, not a manager's KPI. A good answer reframes the goal to predictability, investigates root causes with the team (e.g., story sizing, unplanned work), and proposes experiments.

Advocating to decentralize a deployment approval board
Tests your ability to influence change with data. A good answer frames deployments as frequent, time-critical decisions ideal for decentralization, proposes a phased rollout with metrics like cycle time, and defines new guardrails.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles