Intermediate everything in UX Research, page 3

How can Private Set Intersection enable joint research without exposing raw lists?
Tests cryptography for cross-party data sharing. Strong answers describe PSI's encrypted intersection, cite homomorphic encryption or oblivious transfer, and note key management and compute cost.

How do you avoid confirmation bias when interpreting usability test actions?
This tests recognition that prior beliefs distort observation. A strong answer defines confirmation bias as favoring confirming evidence, then lists guardrails like silent observation and neutral observers. A red flag is vague claims to just stay objective.

How do you align research roadmaps and resolve tactical-strategic conflicts?
Map work to 3 horizons with user-need-outcome framing; protect 30% capacity for strategy; negotiate via visible scorecard.

Propose a framework for measuring the impact of UX research
Propose HEART mapped to KPIs; cite task success, error rate, conversion lift, ticket drops; prove causality.

Design a centralized research repository for discoverable, actionable insights
Tests knowledge-management system design and metadata taxonomy. Strong answers separate raw artifacts, insights, and reports; build faceted search; and integrate with engineering workflows.

How would you quantify a critical UX issue to justify architectural work?
Tests translating UX findings into business metrics to prioritize engineering. Strong answers pair task-success rates with financial impact, benchmark against industry baselines, and frame the fix as risk mitigation.
How would you mitigate latency in a low-bandwidth remote usability study?
Tests planning for 2-5Mbps rural 3G research constraints. Strong answers cover: lightweight prototypes with compressed assets; 3G-throttled environments plus backup comms; data-cost compensation. Red flag: heavy screen-share tools without offline fallbacks.

What instrumentation would you add to validate the user's 'job'?
This tests whether you instrument for intent and struggle, not vanity metrics. Strong answers log pre-export context, abandonment flows, post-export file usage, and workaround signals.
Fix keyboard trap in a custom modal dialog
Tests accessible modal focus management. Strong answers: role="dialog" and aria-modal="true", move focus on open, trap Tab/Shift+Tab cycles inside, Escape to close, return focus to trigger. Red flag: CSS-only fixes or aria-hidden without JS focus control.

How would you prioritize a live usability fix during a full sprint?
Cross-functional negotiation and prioritization under fixed capacity. Present failure-rate or ticket data, map the fix on an impact-effort matrix, and jointly swap a low-impact sprint item or schedule a hotfix.
What research validates a three-sprint feature without delaying engineering?
One week of interviews and prototype tests, with concept testing while engineering spikes.
How do you translate field-study findings into user stories and acceptance criteria?
Tests turning qualitative findings into engineer-ready backlog items. Strong answers: synthesize personas from observations, map pain points to epics, break into As-I-want-so-that stories with acceptance criteria, and co-create with engineers.
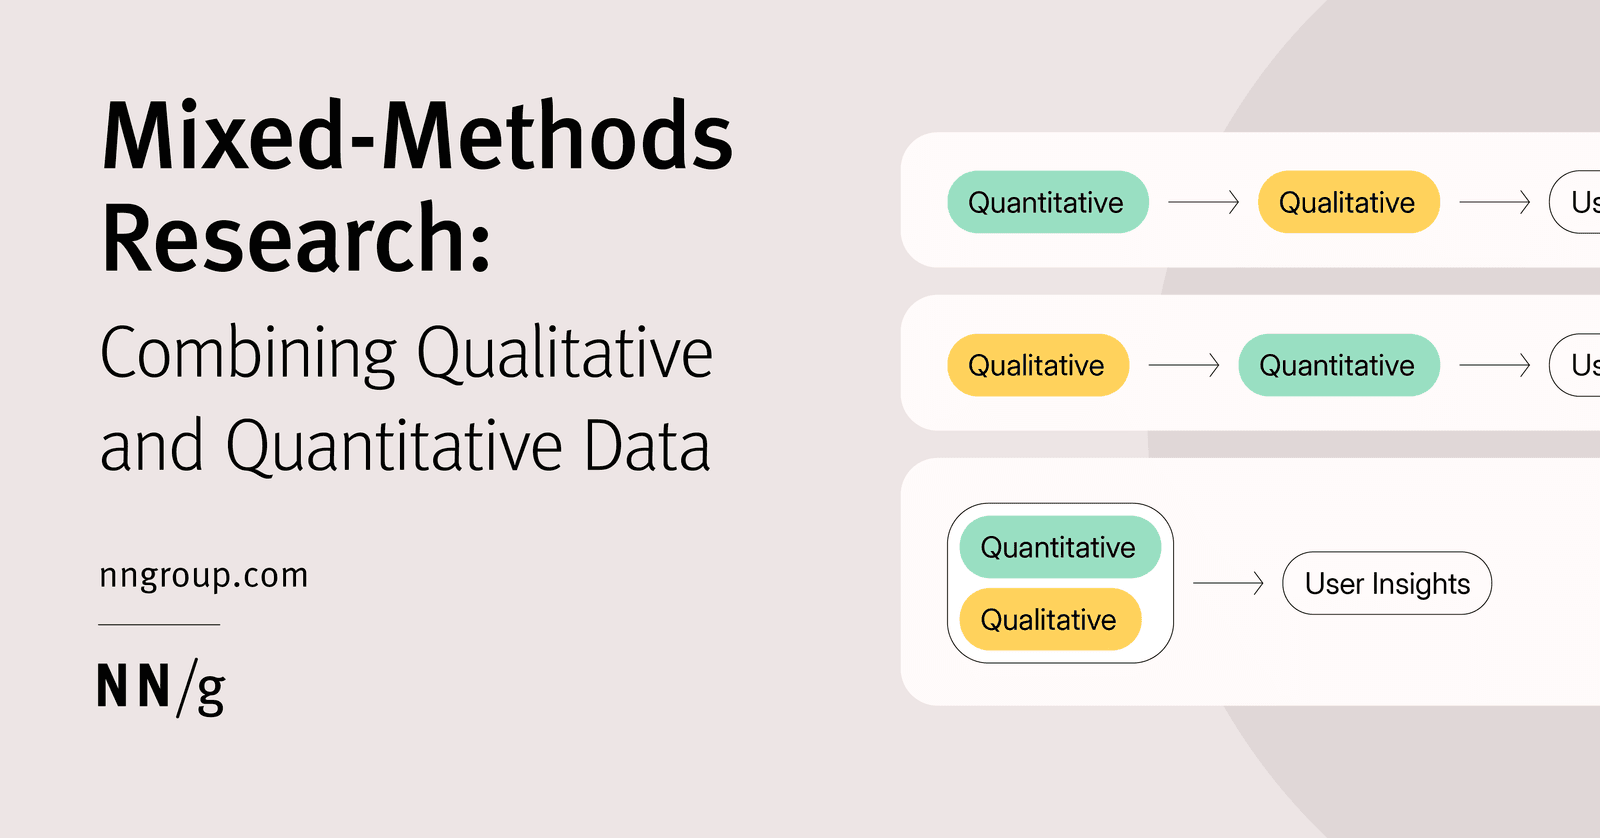
How would you architect a unified quantitative and qualitative user experience view?
This tests intentional mixed-methods integration. A strong answer covers: shared research questions and user IDs; using quant struggles to guide qual interviews; linking datasets by session.
How would you architect a centralized research repository for heterogeneous data types?
Tests designing systems that unify unstructured UX artifacts into a queryable graph. Cover: ingestion with transcription, a metadata schema linking insights to evidence, and faceted cross-type search. Red flag: a flat file dump without structured tagging.
How do you reconcile conflicting qualitative stories with quantitative data?
Integrating mixed-methods without picking sides. A strong answer triangulates definitions, scope, and timing; uses qualitative context to explain outliers; and treats conflict as a signal to dig deeper.

What is the multiple comparisons problem in UX research?
This tests whether you know running many tests inflates false positives. Strong answers define family-wise error, give a UX example like comparing twenty metrics in one A/B test, and name a correction like Bonferroni.
How many users do we need to survey?
Tests pragmatism over guesswork. A strong answer asks if this is a census or sample, population size, whether stratified or multi-group designs apply, and cost, time, and power constraints. Red flag: blurting a number without probing scope, design, or budget.
How do you handle a powerful emergent theme outside original research questions?
Validate recurrence and density, weigh timeline and goals, then document separately, expand formally, or park.
How do you determine when you've reached thematic saturation?
This tests operationalizing saturation beyond gut feel. A strong answer cites Guest et al.'s Base Size, Run Length, and New Information Threshold, and flags consecutive interviews adding no new high-level themes.

What is your process for reconciling significant coding differences?
This tests intercoder reliability and systematic reconciliation. Quantify divergence via agreement metrics; convene to refine codebook definitions and edge-case rules; re-code a sample to verify alignment. Red flag: treating coding as pure subjective opinion.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles