Intermediate everything in MLOps & Infrastructure, page 3
Design a near real-time cost visibility system for ML teams
Tests cost attribution across shared ML infrastructure and streaming pipeline design. Strong answers combine billing exports with resource labels, sub-hour aggregation, and anomaly detection for training spikes.
How do you adapt ML training for spot instance interruptions?
Tests resilience under preemption. Strong answers cover frequent checkpoints to durable storage, SIGTERM handling, idempotent retries with budgets, and compute-state separation. Red flag: saving checkpoints only on local ephemeral disks or solely at epoch end.

What is the wrong and right way to manage ML database secrets?
This tests secret management hygiene for ML pipelines. A strong answer rejects hardcoded secrets and env vars, then proposes AWS Secrets Manager with IAM retrieval, TLS, caching, and rotation. A red flag is suggesting .env files, ConfigMaps, or CLI arguments.
How would you programmatically monitor a deployed model for demographic bias?
Tests operationalizing fairness beyond static audits. Track group metrics like parity and equalized odds; slice by protected attributes; alert on drift; route violations to review. Red flag: treating fairness as a one-time check versus continuous monitoring.
Describe securing an automated ML pipeline and CI/CD integration points
Tests ML supply-chain depth versus bolt-on appsec. Strong answers stage checks across
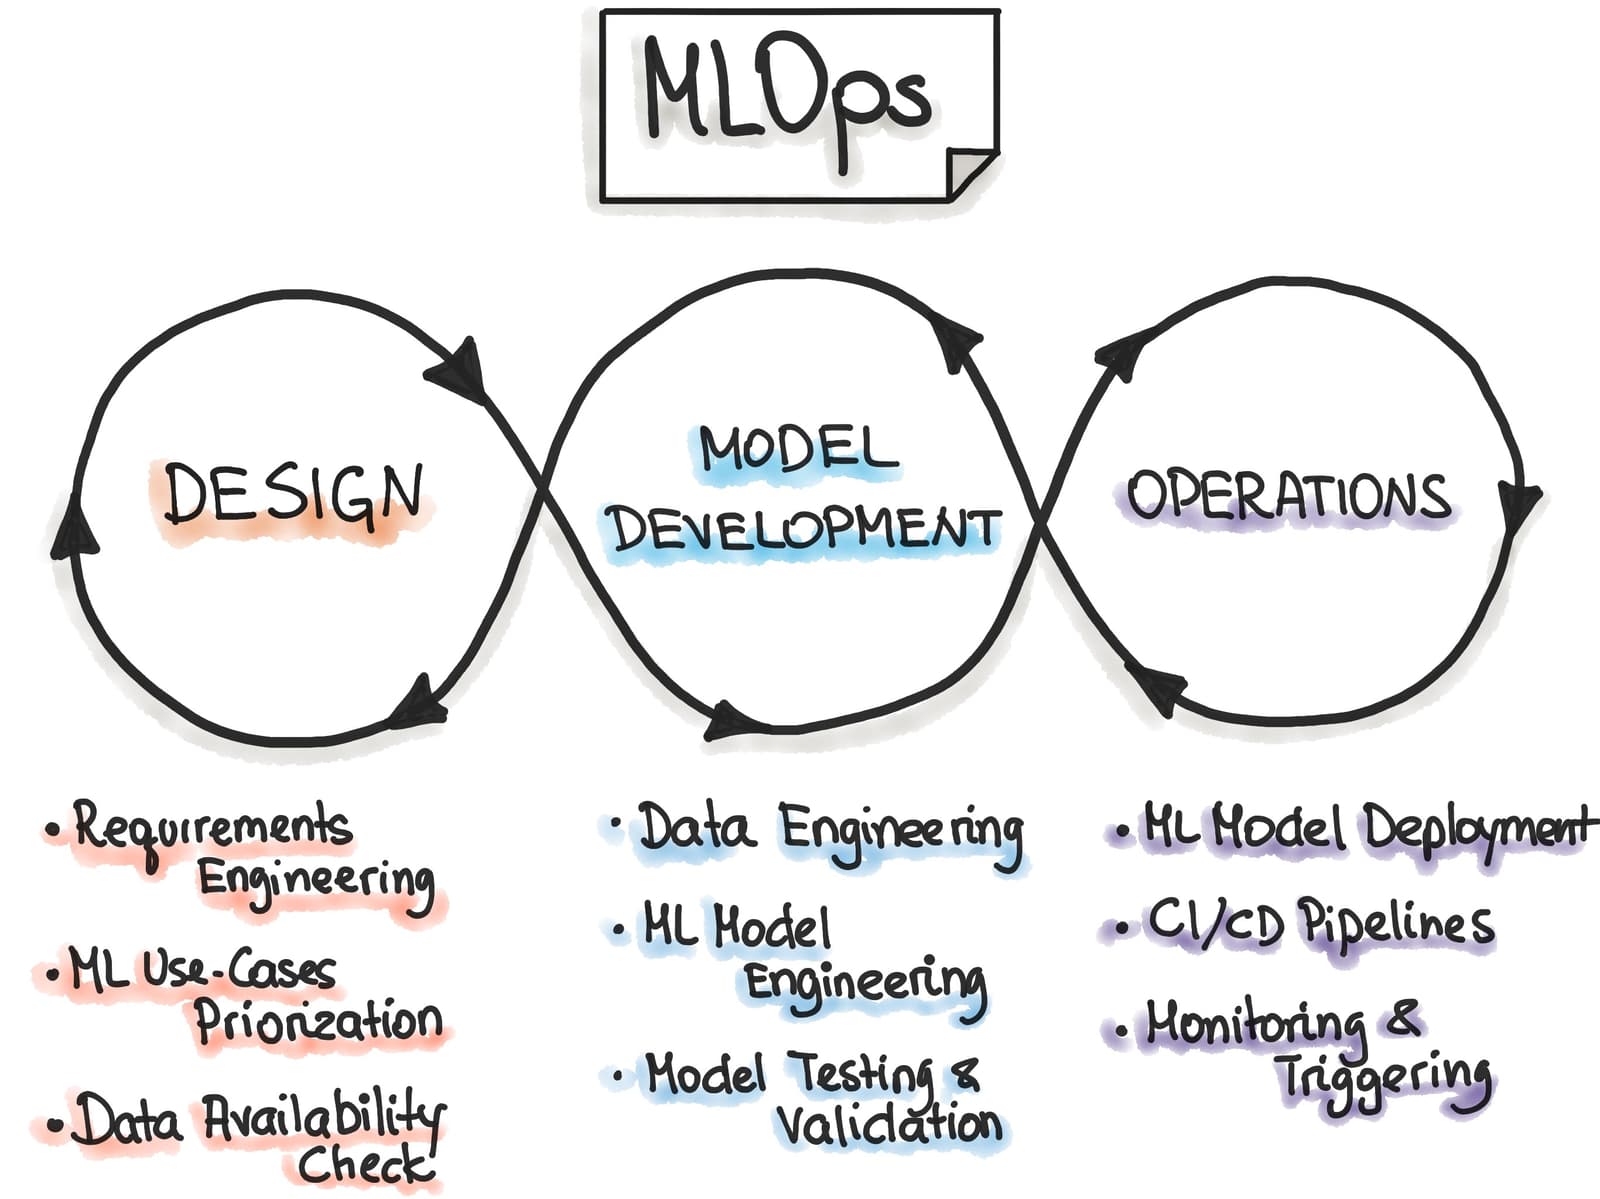
How would you design a reproducible ML training pipeline?
Tests if you can version ML's three moving parts: code, data, and environment. Good answers cover Git for code, DVC or lakehouse versioning for data, and Docker plus locked dependencies for environments.

What trade-offs decide managed ML platforms versus open-source Kubernetes?
Weigh total cost plus hidden engineering headcount, lock-in vs flexibility, and audit feature gaps.
How do you programmatically promote a retrained model to production?
Compare on held-out data using significant metric uplift, schema, latency, and drift checks before shadow release.
How would you implement automated data validation before training?
Enforce schema contracts, halt training on failure, quarantine bad batches, and alert owners.
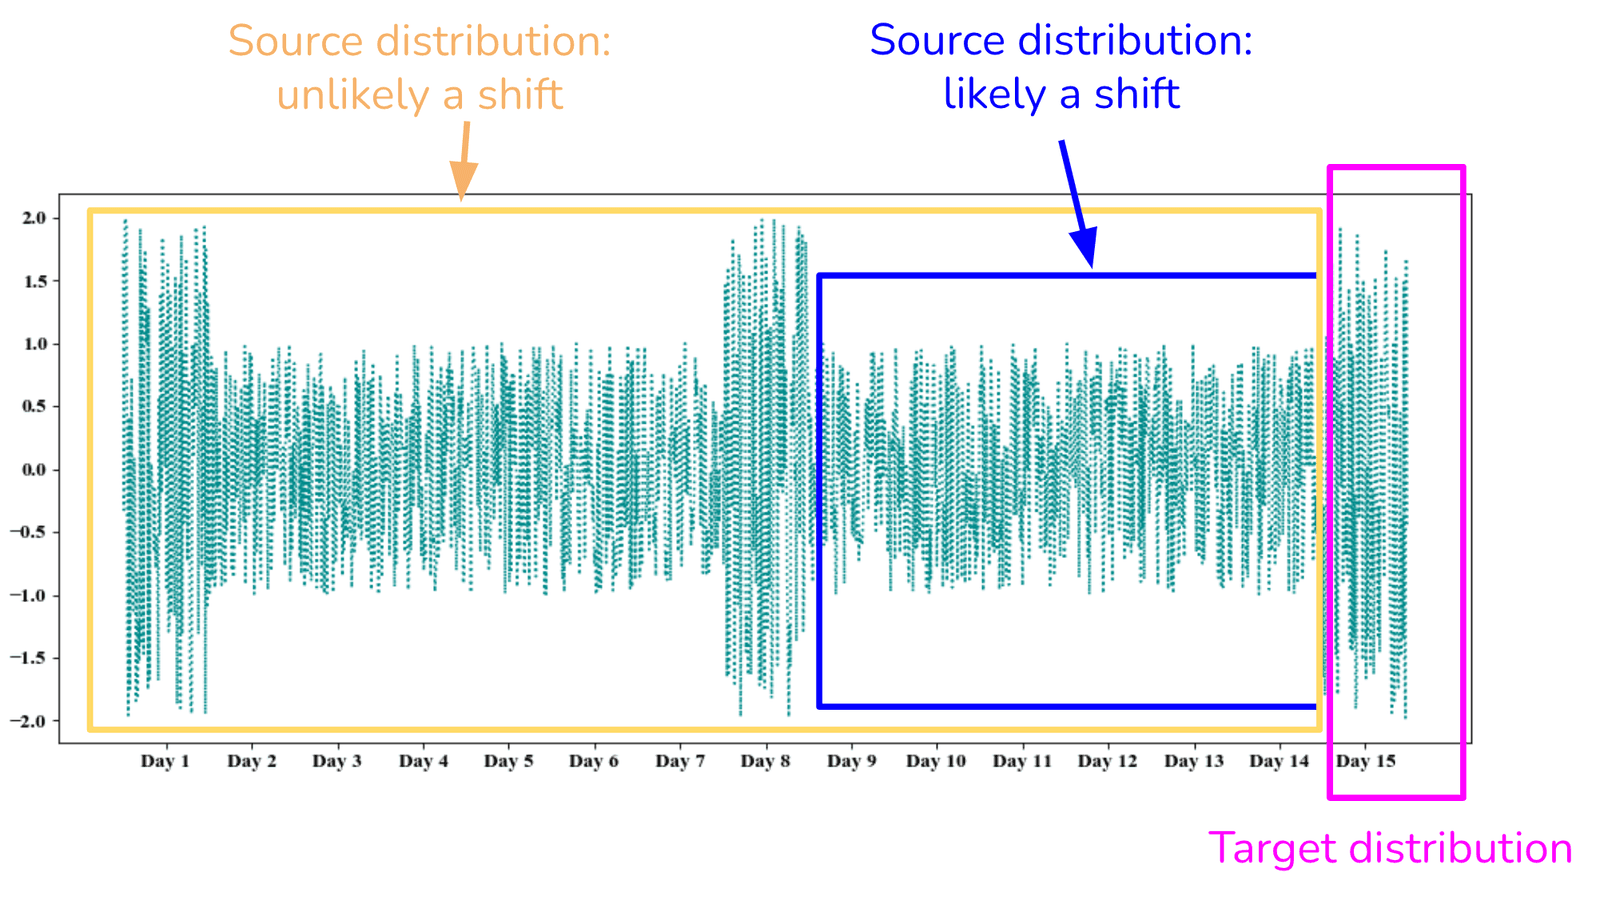
Model output distribution shifts. What are root causes and next steps?
This tests covariate vs label shift vs concept drift when outputs shift. A strong answer checks features before labels, then feedback loops or staleness. A red flag is generic drift without separating P(X), P(Y), and P(Y|X).

Design a system to monitor a real-time prediction service for feature drift
Async feature logging, distribution comparison via PSI/KS against training baseline, and threshold-based anomaly alerts.
How would you design an A/B test for two live ML models?
Tests production experimentation rigor beyond random splitting. Strong answers cover: consistent user hashing for sticky assignment, isolated feature stores, guardrail metrics, and pre-calculated statistical power.
Explain model quantization, its benefits, drawbacks, and validation approach
Tests precision trade-offs in production. Answer: define lowering weights from fp32 to int8/int4; cite memory and latency gains versus accuracy loss; validate with downstream benchmarks and shadow A/B. Red flag: treating as lossless or skipping task metrics.
How would you systematically diagnose high latency in an online inference service?
Check p90/p99 and TTFT to split queuing from compute; inspect queue depth, batch size, GPU, and benchmarks; check cache.

Design a system for batch scoring millions of customer records daily
Shard jobs via scheduler; partition storage; right-size CPU/GPU on spot; retry.

Where to place feature transformations: client, serving API, or upstream service?
Tests separation of concerns in ML systems. Client causes duplication and skew; serving API couples compute to requests; dedicated service adds a network hop but centralizes logic. Red flag: ignoring training-serving skew.
What infrastructure is needed for a Continuous Training pipeline?
Tests event-driven ML system design beyond CI/CD. Strong answers name orchestrators, feature stores, model registries, and validation gates, mapping triggers to retraining and promotion. Red flag: conflating CT with CI/CD or skipping model validation.

How would you implement shadow deployment and which metrics justify promotion?
Tests zero-impact validation when feedback loops are broken. Mirror traffic to a shadow variant, log predictions, and compare latency, errors, and drift against SLAs. Red flag: calling it A/B testing or claiming live business metrics from unserved responses.
What events trigger automatic model retraining beyond code changes?
This tests whether you treat ML pipelines as event-driven systems, not just software CI/CD. A strong answer lists data drift, scheduled cron jobs, production metric degradation, schema changes, and upstream data pipeline completion.
Compare Airflow and Kubeflow for ML training pipelines
Tests orchestrator-to-workload fit. Strong answers contrast Airflow's data integration and Python DAGs with Kubeflow's K8s scaling, container reproducibility, and experiment tracking. Red flag: claiming one is always better without stage-specific reasoning.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles