Concepts in Computer Vision, page 6
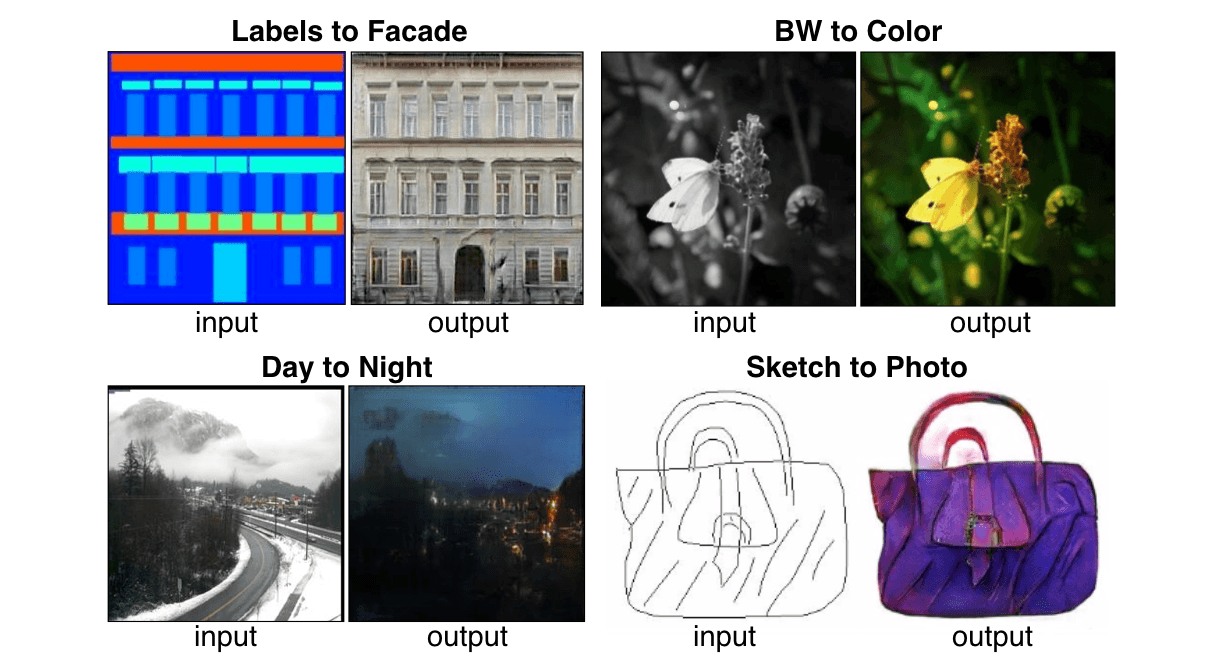
Image-to-Image Translation: One Model, Many Styles
Think of it as a universal visual translator. Given paired examples, it learns to convert one image style to another, like turning a building sketch into a photorealistic rendering. The footgun: it needs a large, aligned 'before-and-after' dataset.
StyleGAN: Controllable, High-Fidelity Image Generation
StyleGAN generates images by controlling 'style' at different levels, like a painter layering coarse, medium, and fine details. It excels at creating hyper-realistic images with tunable features.
CLIP: Teaching AI to See with Words
CLIP creates a shared map for images and text, letting you classify images with natural language prompts. It's used for zero-shot classification and semantic search, bypassing the need for task-specific labeled data.
Perceptual Loss: Judging Images by Vibe, Not Pixels
Perceptual loss judges an AI-generated image by its 'vibe,' not just pixel-for-pixel accuracy. It compares high-level features, making it key for style transfer and super-resolution.
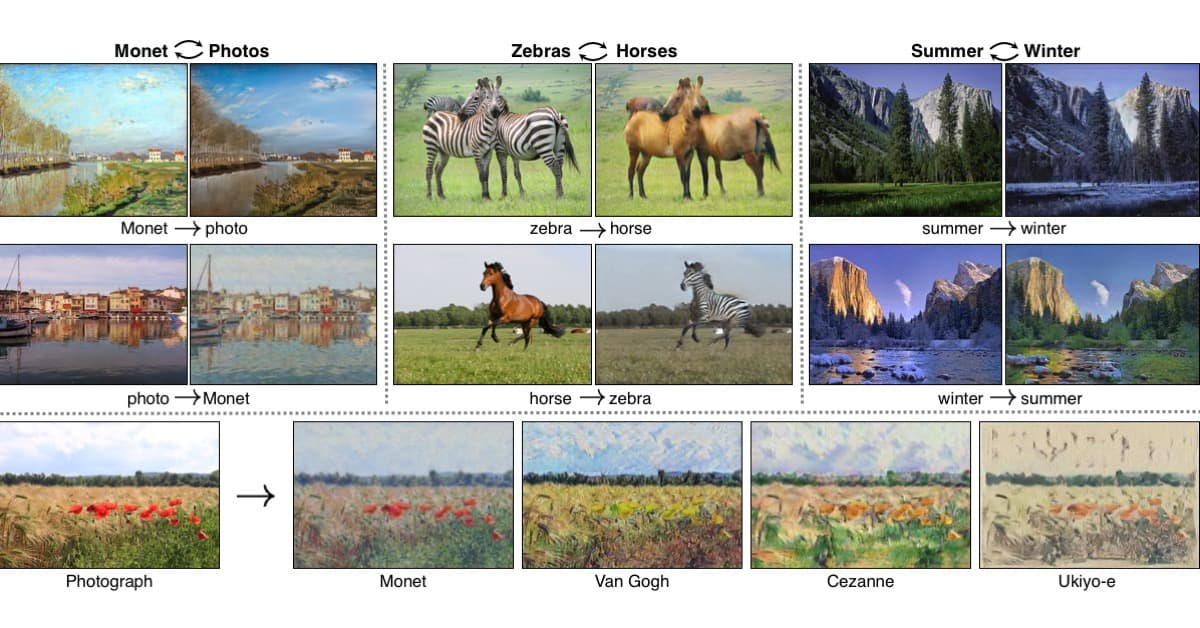
CycleGAN: Image Translation Without Paired Data
CycleGAN translates images between domains (e.g., photos to paintings) without direct 'before' and 'after' examples. It's used for style transfer or turning horses into zebras. The footgun is that it hallucinates details, making it unsafe for critical tasks.
Normalizing Flows: Shaping Simple Distributions into Complex Ones
Normalizing flows transform a simple probability distribution, like a Gaussian, into a complex one, like images. This allows generative models to explicitly calculate the probability of any data point. The footgun is that the transformation must be invertible.
GAN Inversion: Editing Real Photos with Fake Image Generators
GAN Inversion finds the latent code "recipe" inside a pre-trained GAN that best recreates a real image. This lets you use a generator's powerful editing features on real photos for tasks like manipulation or restoration.
Image Captioning: Teaching Machines to Describe What They See
Image captioning teaches a computer to generate a human-readable sentence describing an image, translating pixels into words. This powers accessibility features and better image search.
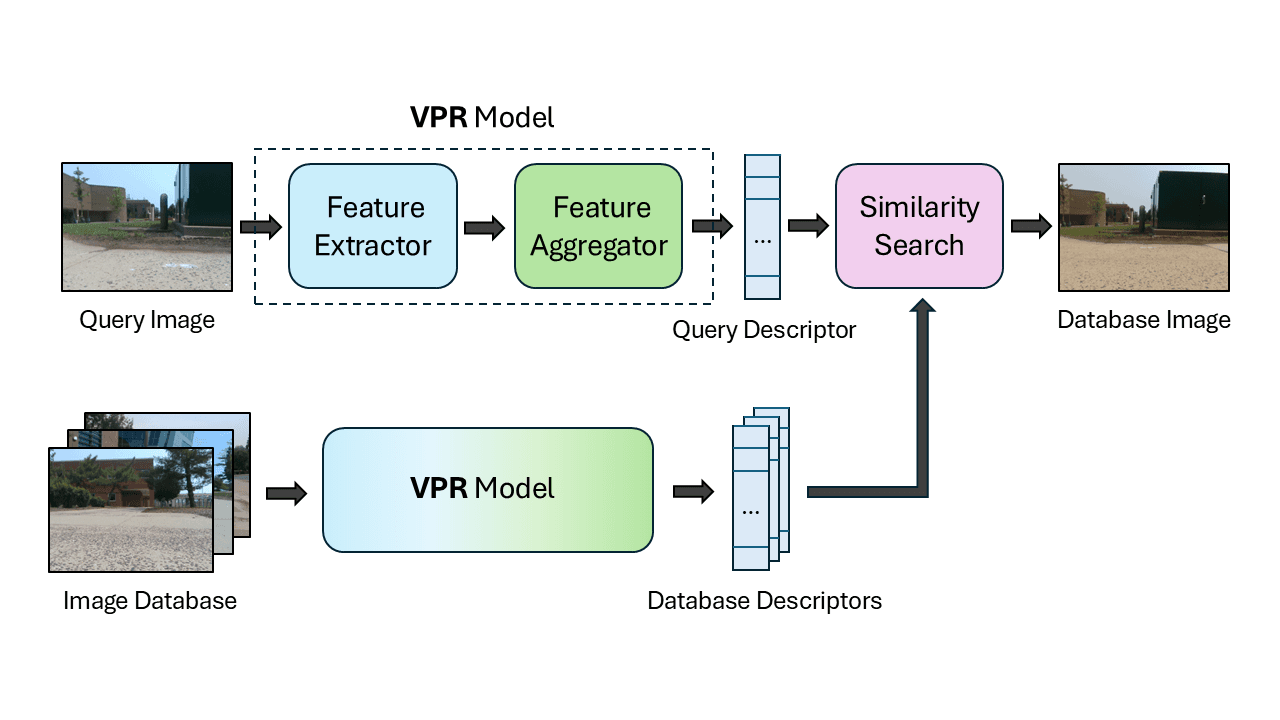
Visual Place Recognition: Finding Your Location from a Picture
Visual Place Recognition (VPR) answers "Where am I?" by matching a live camera image to a database of pre-recorded pictures. It's a visual GPS for robots and self-driving cars to find their position when GPS is unreliable, like in cities or indoors.

Scene Parsing: Labeling Every Pixel in an Image
Scene parsing is like digital coloring-by-numbers, assigning a category like 'road' or 'sky' to every pixel. It's used by autonomous vehicles to understand the road and AR apps to place objects.

Visual Question Answering (VQA): Teaching AI to See and Reason
VQA models combine vision and language to answer questions about an image, like a visual Turing test. It's used in assistive tech and advanced image search. The footgun is models learning to answer based on language patterns, not visual content.
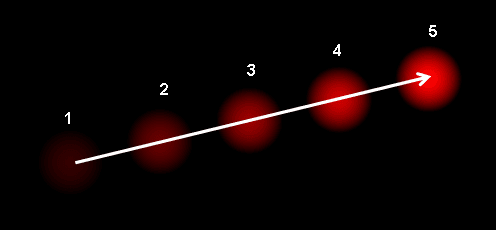
Visual Odometry: Estimating Motion from Pixels
Visual odometry is dead reckoning with a camera. It estimates movement by tracking how features shift between images, without GPS or maps. It's used in robotics and AR, but its biggest footgun is that small errors accumulate, causing it to drift over time.
Scene Graph Generation: From Pixels to Relationships
Scene Graph Generation (SGG) moves beyond just finding objects in an image; it maps out the relationships between them. This enables deeper scene understanding for tasks like advanced image search.
Visual Servoing: Using Eyes to Guide a Robot's Hands
Visual servoing is like how you reach for a cup: your eyes guide your hand. A robot uses a camera to continuously correct its motion toward a target, closing the loop between seeing and doing. It's key for robotic arms, drones, and surgical bots.
Affordance Learning: Teaching AI What Objects Do
Instead of just naming objects, affordance learning teaches AI to see potential actions—a chair is for sitting, a knob is for turning. This is crucial for robotics, where a machine must know how to interact with novel items.
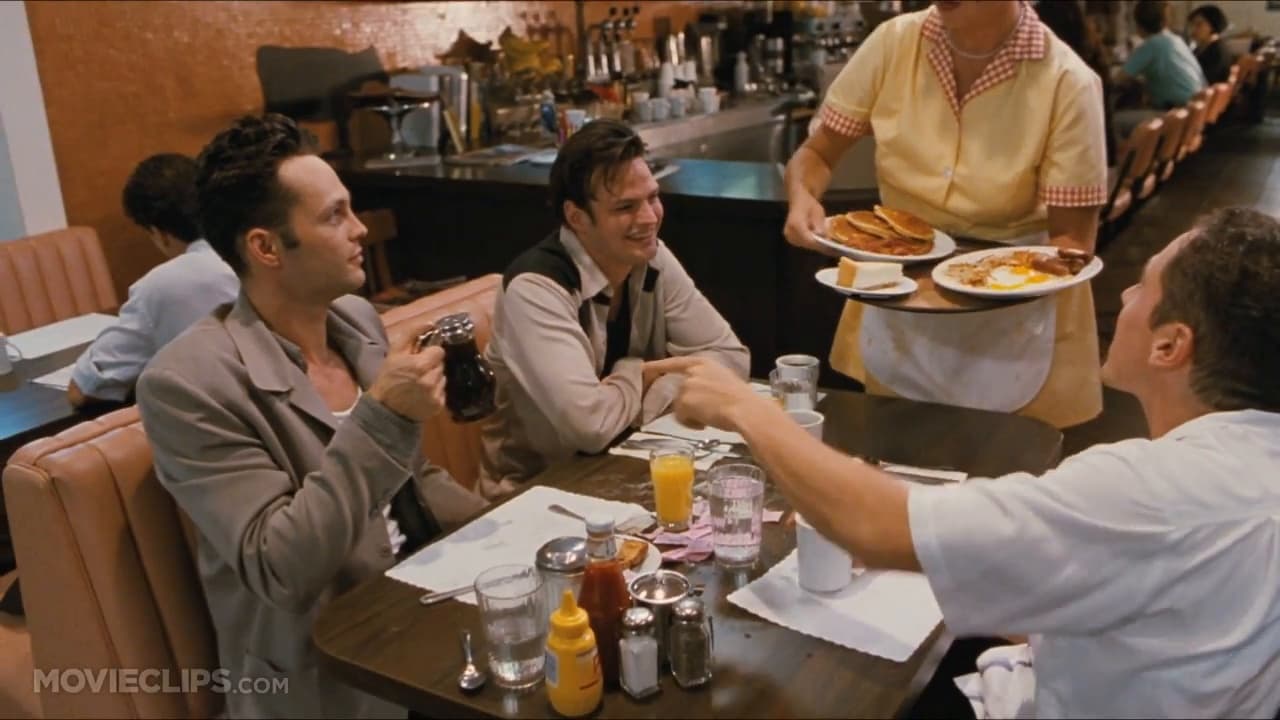
Visual Commonsense Reasoning (VCR): From Recognition to Cognition
VCR pushes AI from simple object recognition to human-like reasoning by asking not just 'what' is in an image, but 'why.' Models must select both the correct answer and the correct rationale, exposing models that guess answers based on shallow correlations.
Pretext Tasks: Making Data Teach Itself
A pretext task is a fake problem you invent for a model so it learns from unlabeled data. For example, asking it to predict a missing image patch forces it to learn about objects. This is the core of self-supervised learning.
Semi-Supervised Learning: More From Less Data
Semi-supervised learning uses a small set of labeled data and a large set of unlabeled data to train a model. It's ideal for tasks like image classification where labeling is costly. The footgun: if your unlabeled data is noisy, it can degrade performance.
N-way-K-shot: Classifying with Few Examples
N-way-K-shot is a framework for testing a model's ability to learn from scarce data. It asks: 'Can you classify between N categories after seeing only K examples of each?'

Zero-Shot Learning: Classifying the Unseen
Zero-Shot Learning lets a model classify things it never trained on. It works by linking visual features to semantic descriptions, like identifying a 'zebra' from the description 'striped horse'. The footgun is assuming it creates knowledge from nothing.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles