Concepts in Computer Vision, page 7
Prototypical Networks: Learning from a Handful of Examples
Prototypical Networks classify new categories from few examples by finding the average representation, or 'prototype,' for each class. This is key for few-shot image recognition where you have only 1-5 examples.
Weakly Supervised Learning: Cheaper Labels, Smarter Models
Weakly Supervised Learning trains models on cheap, imprecise labels to perform complex tasks. It's used for object detection when you only have image-level tags, not pixel-perfect annotations.
SimCLR: Learning Powerful Vision Features Without Labels
SimCLR learns image features from unlabeled data by teaching a model that two augmentations of one image are similar, and all other images are different. It's used to pre-train models on vast, unlabeled datasets.
Momentum Contrast (MoCo): A Dynamic Dictionary for Unsupervised Learning
MoCo learns visual features without labels by treating contrastive learning as a dynamic dictionary lookup. A momentum-updated encoder creates a large, consistent set of keys on-the-fly, enabling powerful pre-training on unlabeled data for downstream vision…
Masked Autoencoders: Learning Vision by Filling in the Blanks
Masked Autoencoders (MAEs) teach models vision by playing "fill-in-the-blanks" with images, masking most of an image (e.g., 75%) and learning to reconstruct it. This is used for self-supervised pre-training of large Vision Transformers on unlabeled data.
MAML: Learning to Learn Quickly
MAML trains a model to be easy to fine-tune, finding an initial set of parameters that serve as a great starting point for many new tasks. It's used in few-shot learning where models must adapt with minimal data.
High Dynamic Range (HDR): Seeing More Light
HDR captures a wider range of light and dark than standard images, preventing blown-out highlights and crushed shadows. It's used to show scenes as the human eye sees them. The footgun is thinking HDR is just 'brighter'—it's about more detail in the extremes.
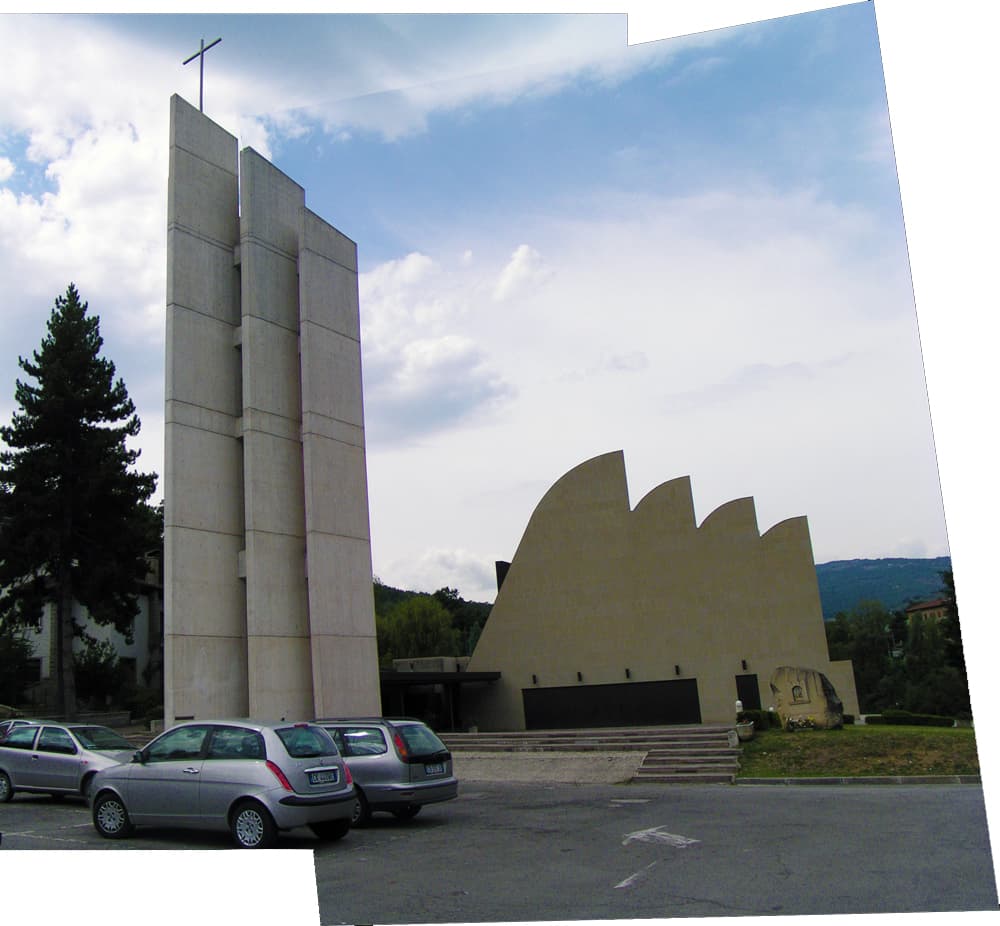
Image Stitching: Creating Panoramas from Overlapping Photos
Image stitching digitally 'tapes' together overlapping photos to create a single, wider panorama or a super-high-resolution image. It's used in phone panorama modes and for creating gigapixel photos. The main footgun is insufficient overlap between shots.
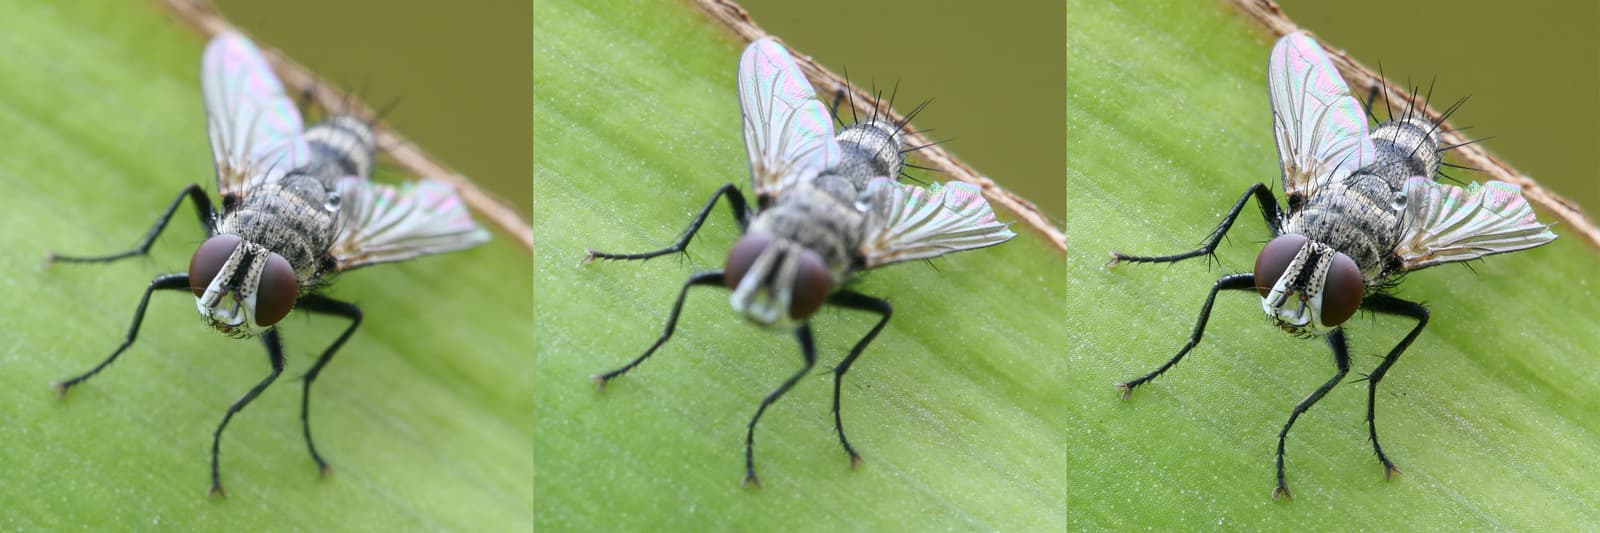
Focus Stacking: Combining Focal Planes for Ultimate Sharpness
Focus stacking creates an image with impossible depth of field by combining the sharpest parts of multiple photos. It's essential for macro, landscape, and microscopy where one shot can't keep everything sharp.

Tone Mapping: Fitting HDR Light onto LDR Screens
Tone mapping compresses a vast range of light (HDR) to fit on a standard screen (LDR). It's how HDR photos and games look good on your monitor instead of having blown-out whites or crushed blacks. The footgun is creating unnatural, "over-cooked" images.
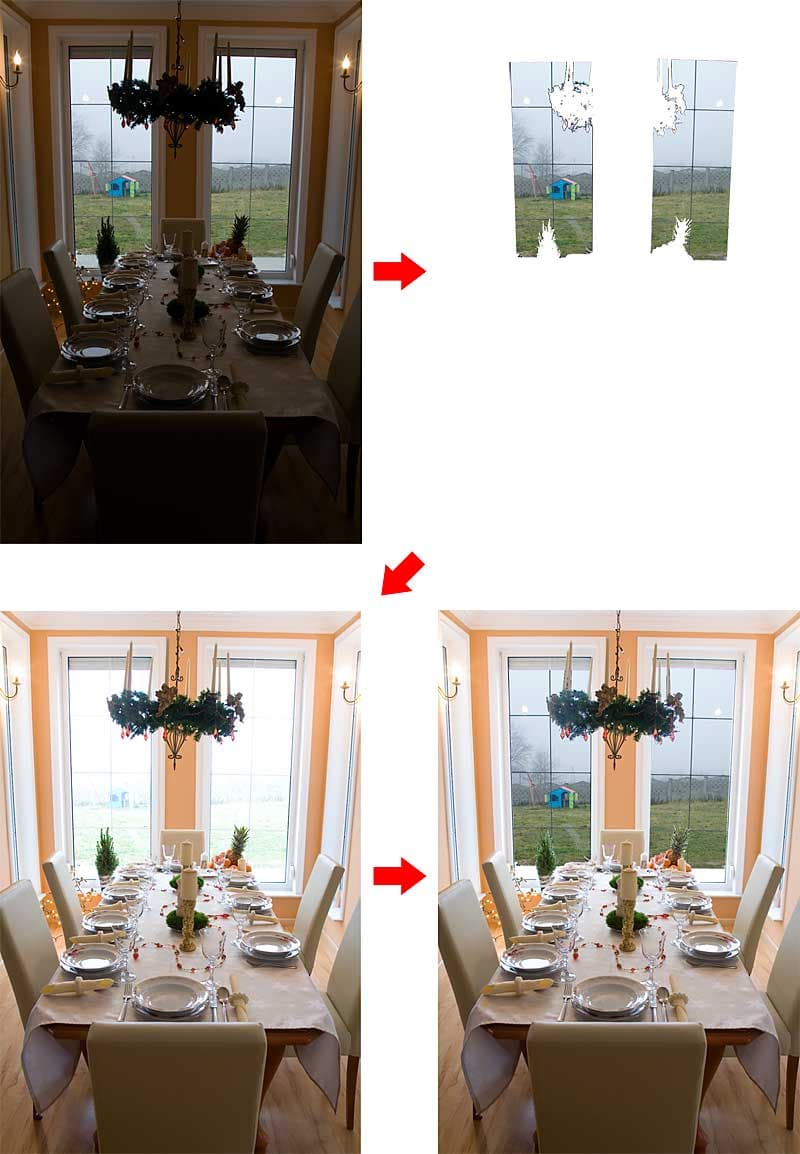
Exposure Fusion: HDR Looks Without the HDR File
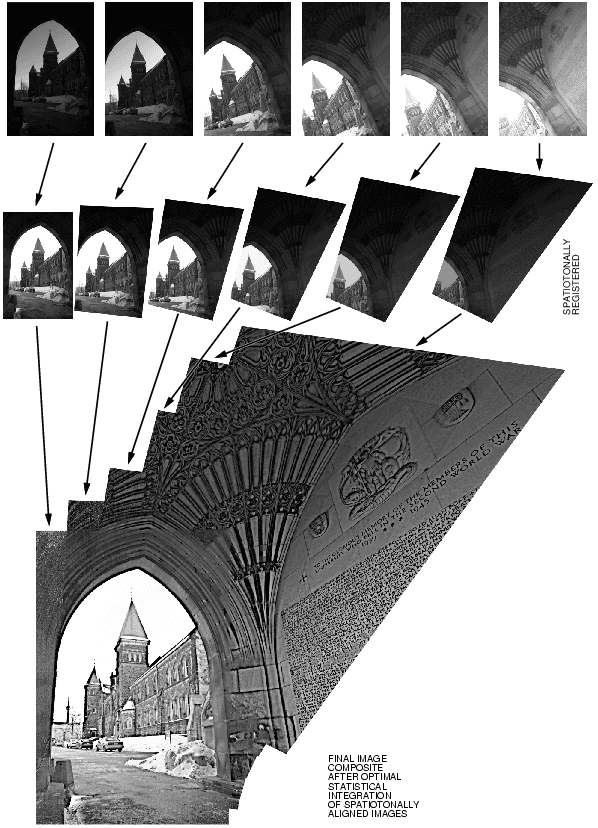
Exposure fusion blends the best-lit pixels from several bracketed shots into one image. This lets you capture high-contrast scenes, like a bright window in a dark room, without creating a full HDR file.
Multi-frame Noise Reduction: Finding Signal in the Noise
Multi-frame noise reduction averages multiple shots to isolate the true signal. The underlying image is consistent, while random noise cancels out. It's key for low-light phone photos and video.
Synthetic Aperture: Faking a Big Lens with Software
Synthetic aperture uses depth data to computationally fake the shallow depth-of-field of a large lens. It's the magic behind smartphone 'Portrait Mode,' blurring the background to make a subject pop.
Super-Resolution: Creating Detail from Less
Super-resolution creates a high-res image from low-res sources by inferring missing details. It powers smartphone digital zoom and video upscaling. The footgun: generated details are plausible hallucinations, not ground truth, making it risky for scientific…
Seam Carving: Resizing Images Without Distortion
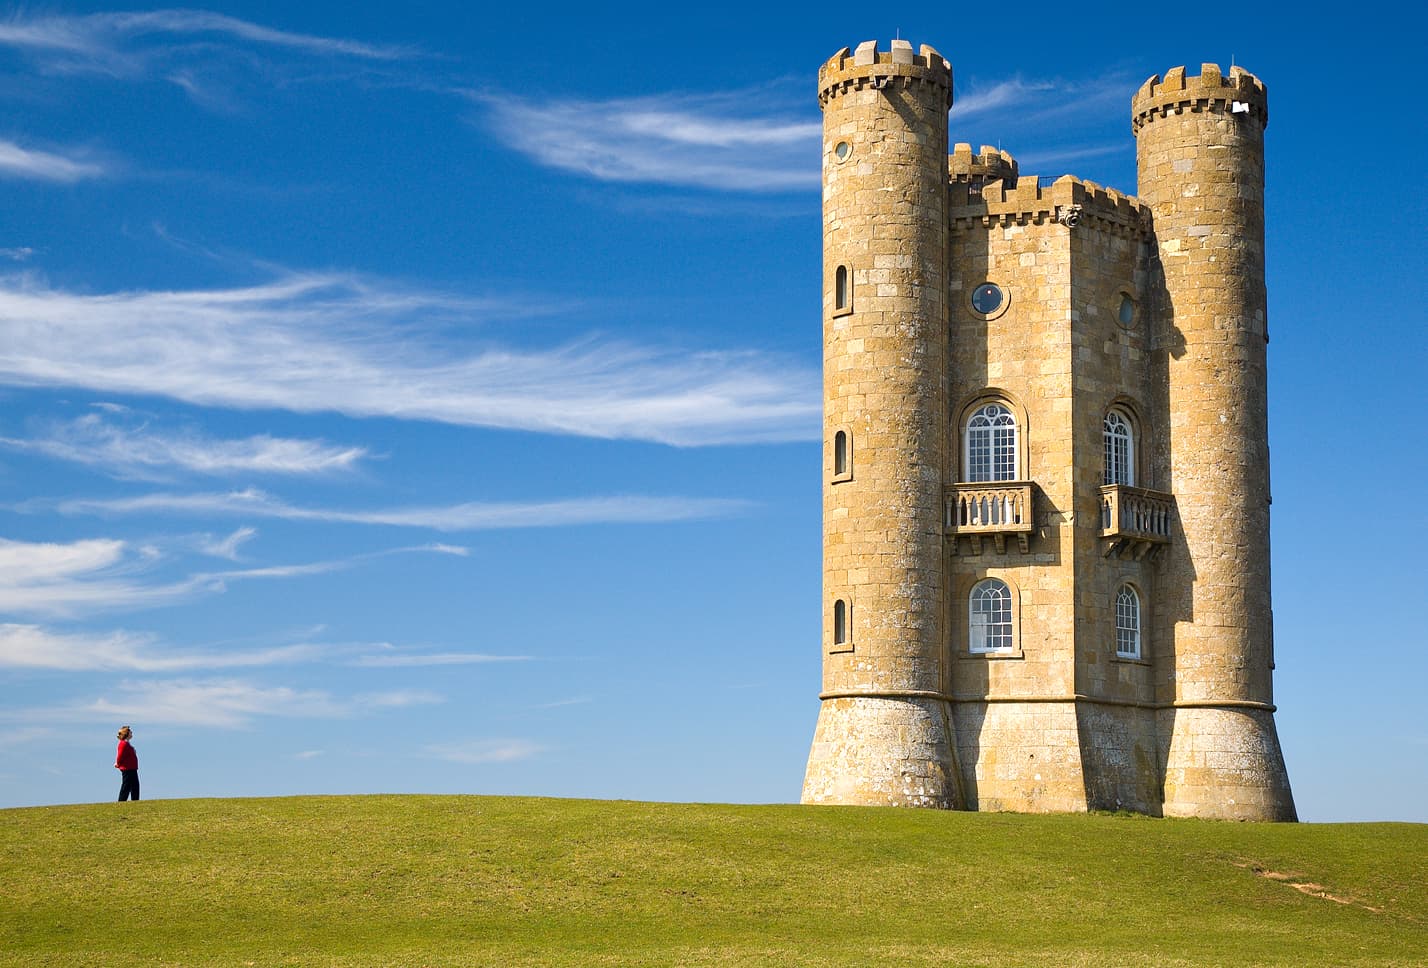
Seam carving resizes images by removing or adding pixel "seams" of low importance, not by squashing or cropping the whole frame. It's used in content-aware tools to change aspect ratios without distorting key subjects like faces or buildings.
Photometric Stereo: Reconstructing Shape from Light
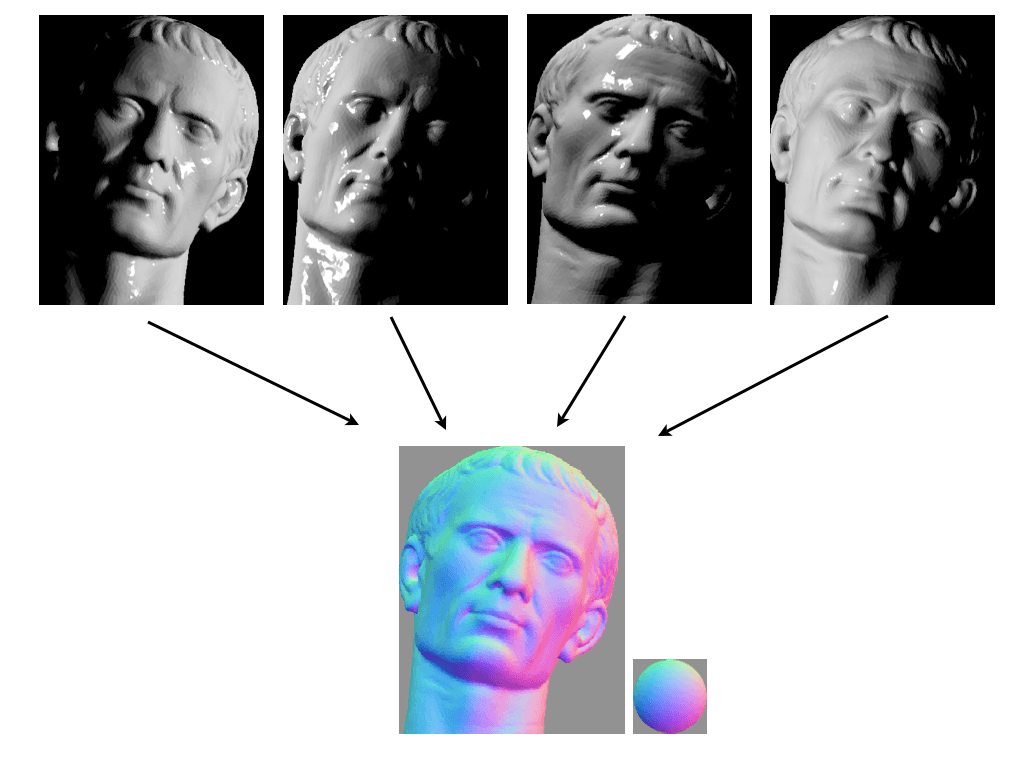
Photometric stereo deduces an object's 3D shape by watching how its surface reflects light from different directions. It’s used in industrial inspection and computer graphics to capture detailed surface geometry. The footgun is assuming it works on any object.
Light Field Photography: Capturing Light's Direction
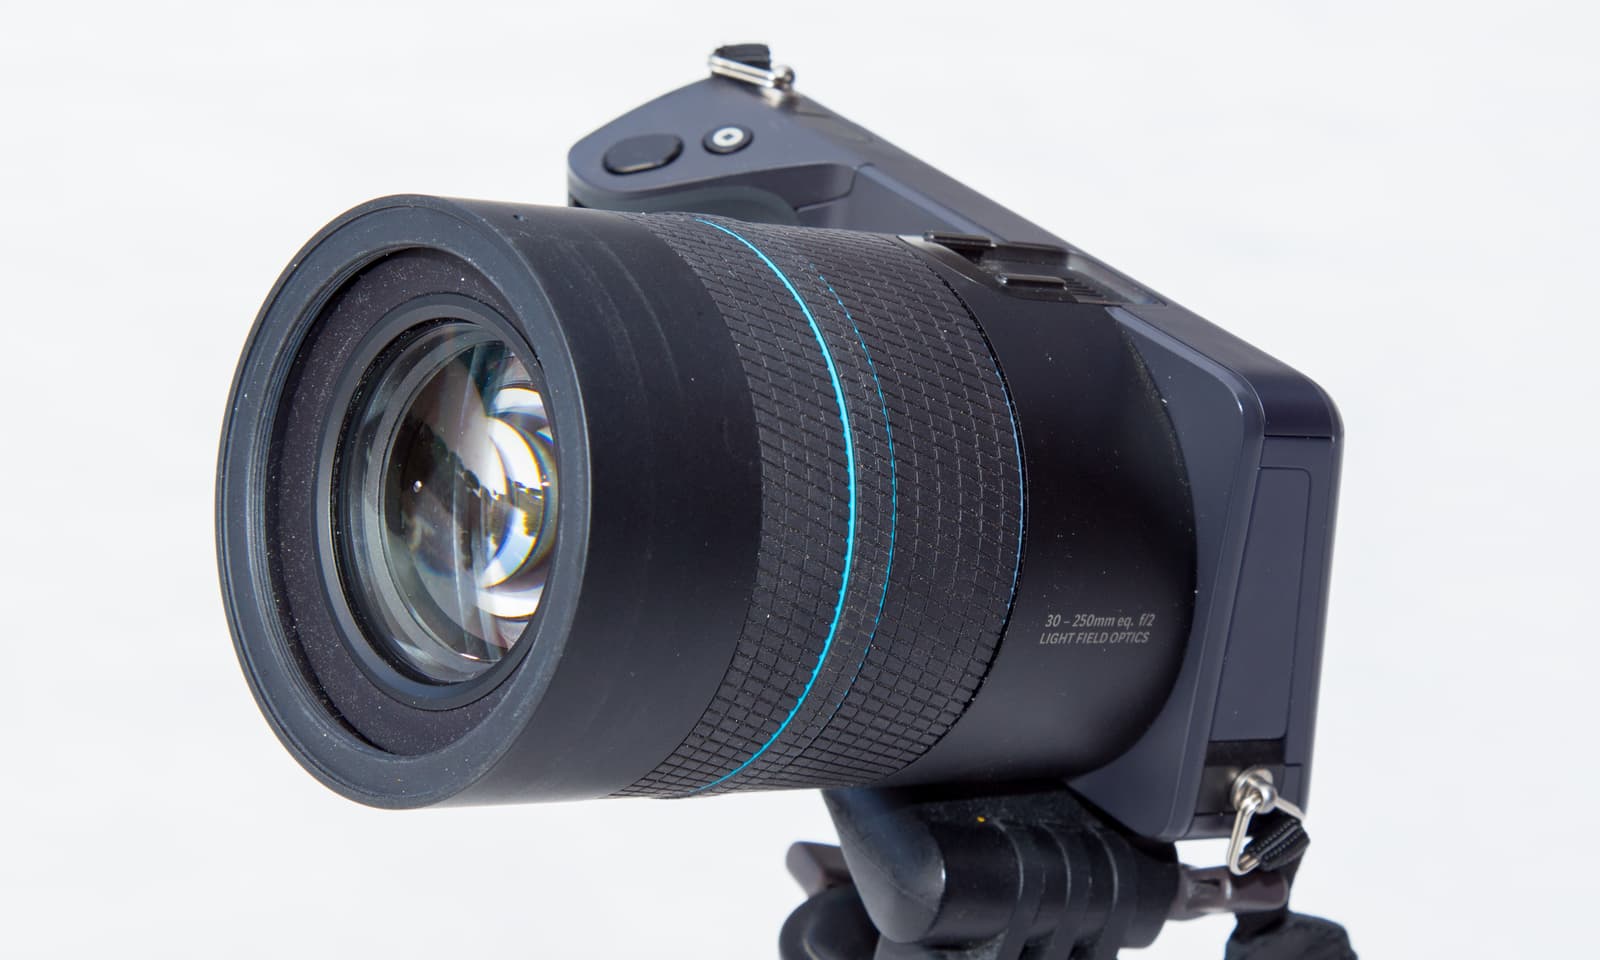
A light field camera captures not just what light hits the sensor, but where it came from. It records both the intensity and direction of every ray, unlike conventional cameras that only see intensity. The footgun is thinking it's just a better 2D camera.
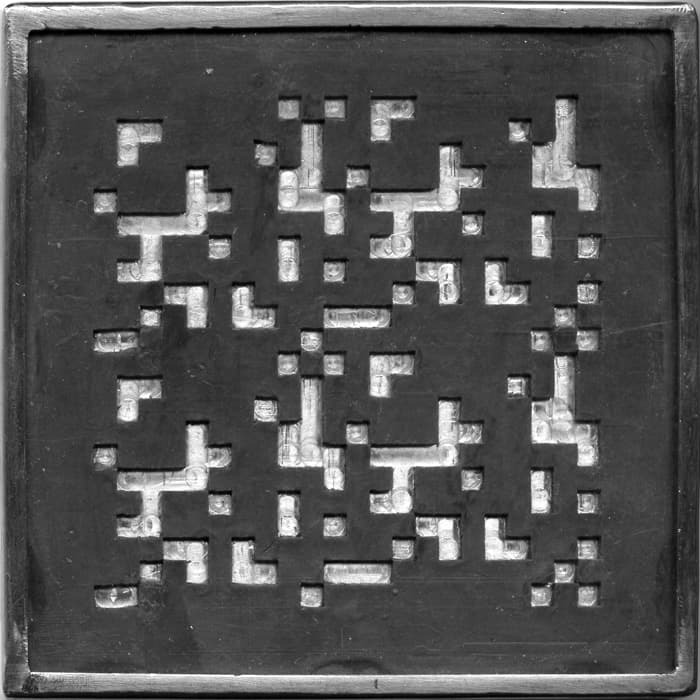
Coded Aperture: Imaging Without a Lens
A coded aperture images radiation that can't be focused, like X-rays. Instead of a lens, it uses a patterned mask to cast a complex shadow, which is then mathematically decoded into an image. It's crucial for X-ray astronomy.
Image Sensors: Converting Light to Data
An image sensor is the digital equivalent of film, turning light into electrical signals. It's the core component in everything from your phone's camera to medical imaging.
ImageNet: The Dataset That Launched the Deep Learning Boom
ImageNet is a massive, human-labeled image library that became the standard benchmark for teaching computers to "see". It's the dataset behind the deep learning revolution, used to pre-train models for photo search and more.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles