Intermediate everything in Data Science & Analytics, page 6
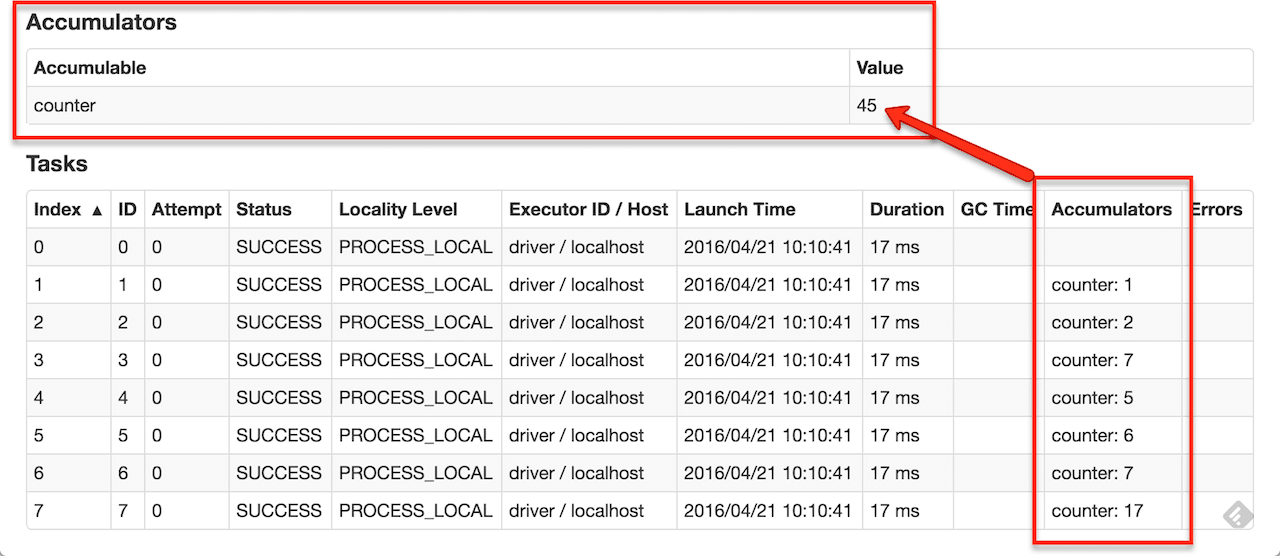
Spark RDDs: Immutable, Distributed Data Collections
An RDD is Spark's core abstraction: an immutable, partitioned collection of items processed in parallel. It's the go-to for low-level, unstructured data tasks. The main footgun is using RDDs when higher-level DataFrames offer better performance.
YARN: Hadoop's Cluster Operating System
YARN acts as the operating system for a Hadoop cluster, separating resource management from job processing. This allows multiple engines like Spark or MapReduce to run on the same hardware.
Markov Decision Process: A Map for Sequential Decisions
A Markov Decision Process models sequential choices with uncertain outcomes. Think of it as a game with states, actions, and rewards, but where your next move is probabilistic.
Q-Learning: Teaching an Agent by Trial and Error
Q-Learning teaches an agent the 'quality' of an action in a given state through trial and error, like training a pet with treats. It's used in robotics for navigation or in games where an AI learns optimal moves.
Named Entity Recognition: Finding the 'Who, What, Where' in Text
Named Entity Recognition (NER) is a smart highlighter for text, automatically finding and tagging nouns like people, places, and organizations. It powers search and extracts structured data from news or support tickets.
Topic Modeling: Finding Themes in Unstructured Text
Topic modeling automatically finds themes in text by grouping words that often appear together. It's used to analyze customer feedback or organize large document sets.
Recurrent Neural Networks: Networks with Memory
An RNN is a neural network with a memory loop, processing sequential data by feeding its own output back in as input. It's used for text generation or time-series analysis where context is key.
Hierarchical Clustering: Building a Family Tree for Data
Hierarchical clustering builds a family tree of your data, not just a single set of groups. It's used when you don't know the number of clusters beforehand, like in biology or market segmentation. The main footgun: early merges are final and can't be undone.
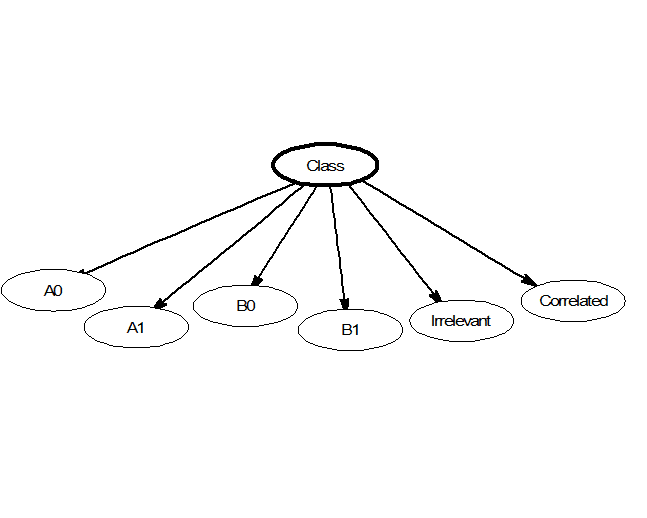
Naive Bayes: Fast Classification by Assuming Independence
Naive Bayes classifies data by assuming its features are unrelated, like judging a fruit's type by color and shape independently. This makes it fast for tasks like spam filtering or real-time predictions. Its core 'naive' assumption is almost always wrong.
Support Vector Machine: Finding the Widest Street
A Support Vector Machine (SVM) finds the widest possible "street" to separate data classes. It's used for classification tasks like text analysis. The footgun is forgetting the "kernel trick," which lets SVMs solve non-linear problems, not just draw lines.
Cross-Validation: Don't Test on Your Training Data
Cross-validation stops a model from 'cheating' by testing it on unseen data. It repeatedly splits your dataset into training and testing portions to simulate real-world performance.

Q-Q Plot: Visually Test if Data Fits a Distribution
A Q-Q plot visually checks if your data fits a theoretical distribution (like normal). If the points form a straight line, it's a match. Use it to validate model assumptions.

Kernel Density Estimation: Beyond the Histogram
A KDE plot is a smoothed histogram, revealing a variable's distribution by summing 'bumps' over each data point instead of using rigid bins. It's great for data exploration, but the 'smoothness' (bandwidth) choice can drastically alter the plot's story.
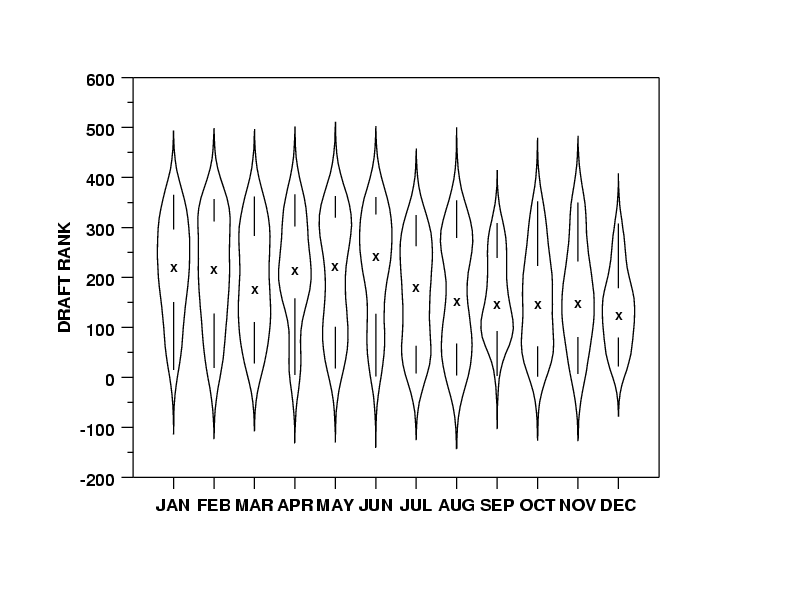
Violin Plots: Box Plots with a Sense of Shape
A violin plot is a box plot that also shows the data's shape. It reveals multi-modal distributions or skews that a simple box plot would hide. Use it to compare distributions across categories, like server response times.
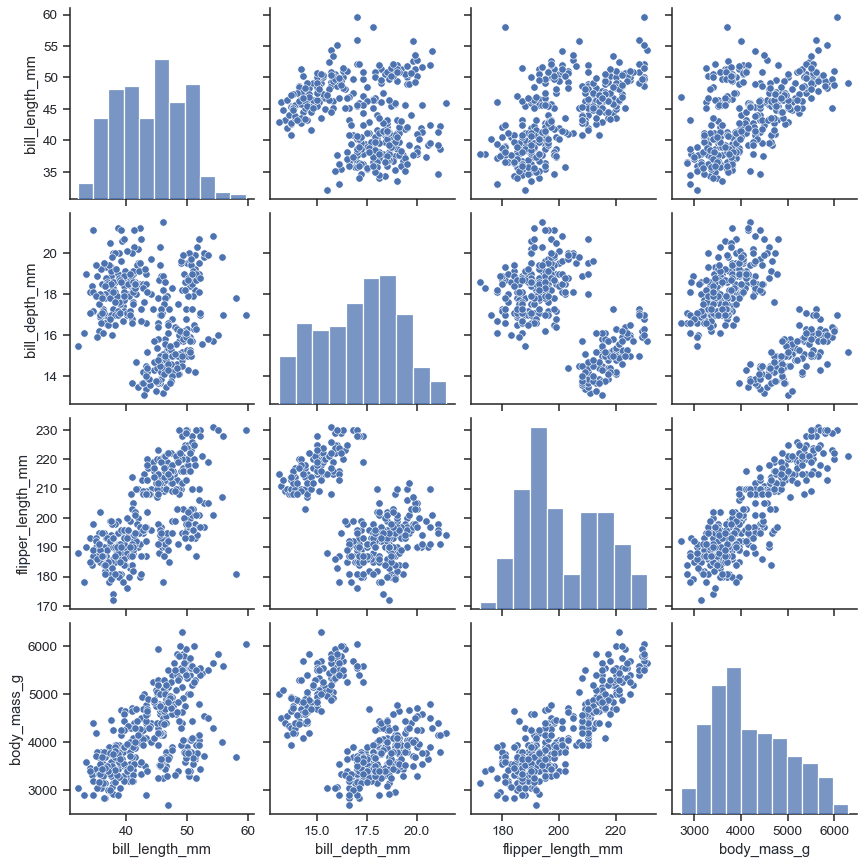
Pair Plot: See All Your Data's Relationships at Once
A pair plot is a matrix of charts showing every pairwise relationship in a dataset. Use it in exploratory data analysis to spot correlations and distributions at a glance. The footgun: it becomes unreadably large and slow with more than ~10 variables.
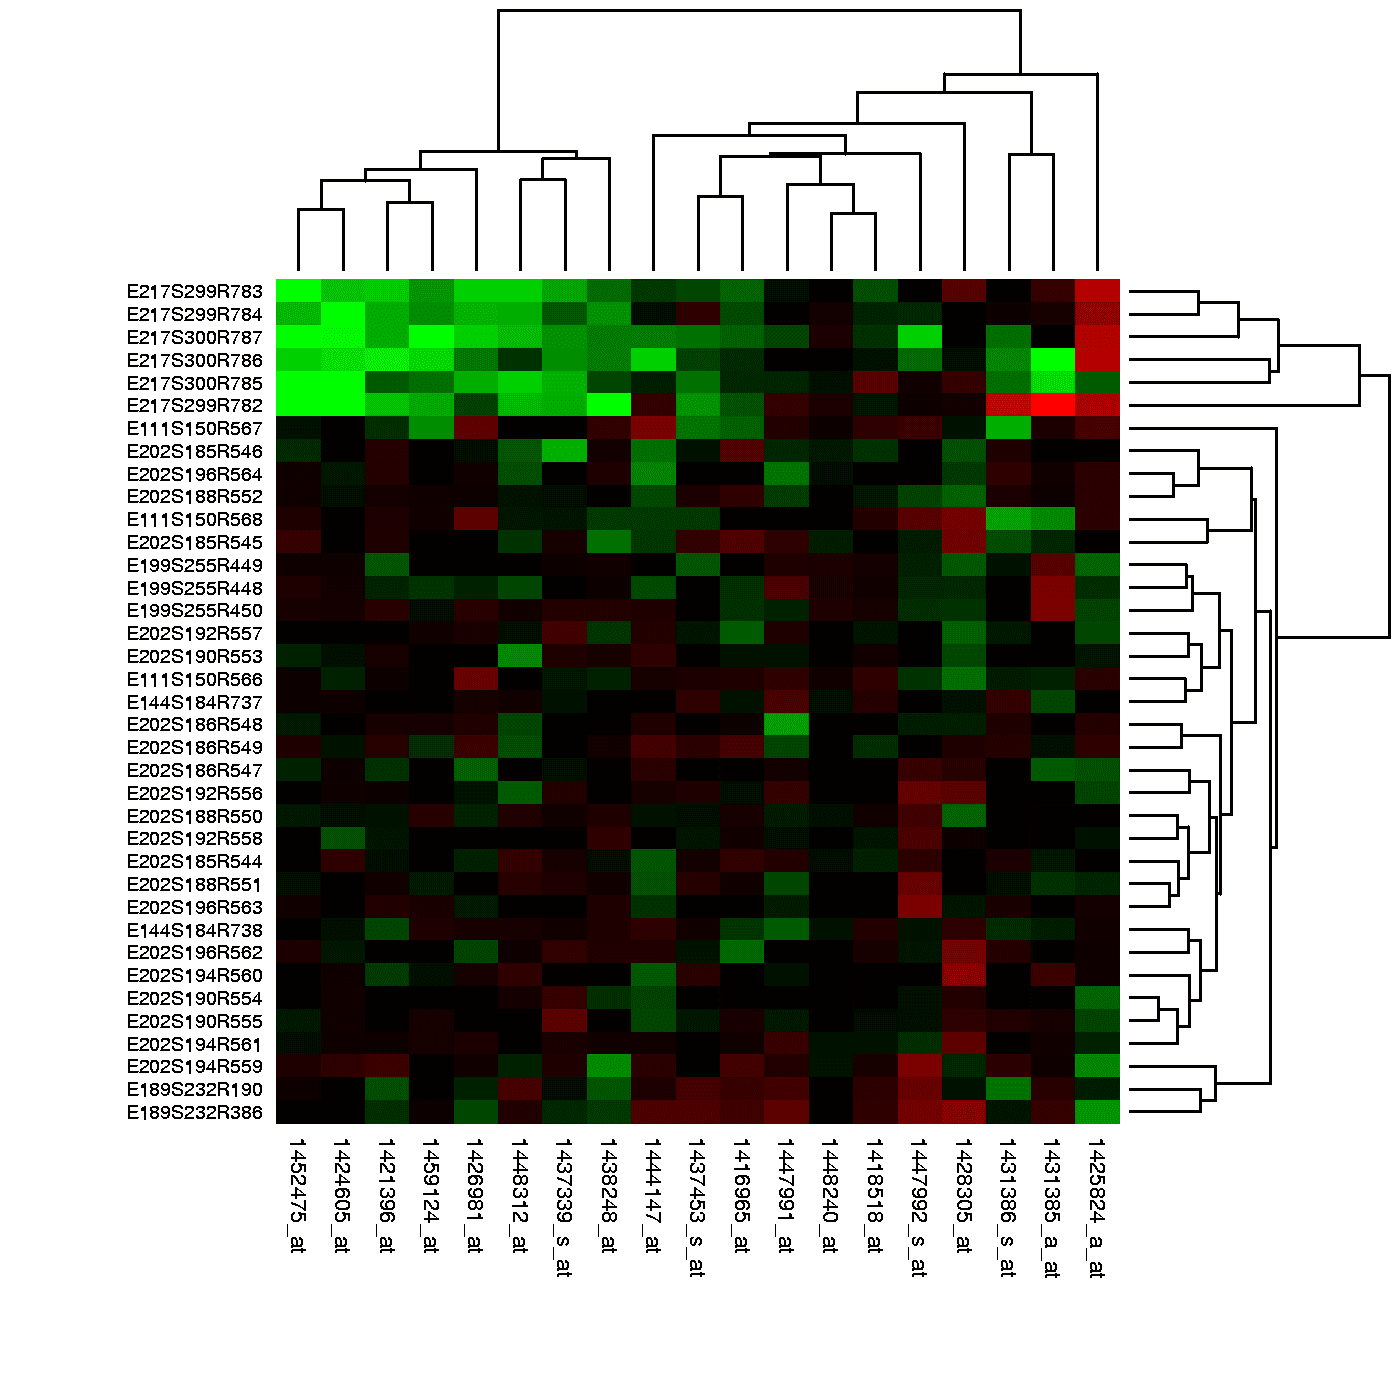
Heatmap: Visualizing Magnitude with Color
A heatmap is like coloring in a spreadsheet, using color to show the magnitude of values in a 2D grid. It's used to spot user engagement hotspots on a webpage, analyze financial data, or visualize gene expression.
Data Quality Management: Is Your Data Fit for Use?
Data quality management ensures data is "fit for purpose." It's vital when training ML models or creating financial reports, as outcomes depend on data reliability. The footgun is treating quality as a one-time project, not a continuous process.

Label Encoding: Turning Categories into Numbers
Label Encoding turns text categories into numbers, like assigning bib numbers to runners. It's essential for algorithms that need numerical input, but its biggest footgun is creating a fake order (e.g., 2 > 1) that can mislead linear models and neural…
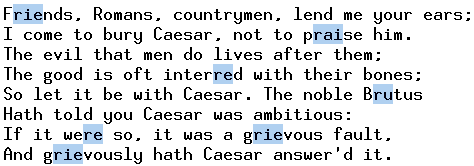
Regular Expressions for Data Cleaning
Regex is a mini-language for describing text patterns, letting you find and fix messy data at scale. It's used to standardize phone numbers or extract zip codes from addresses. The footgun: complex regex is often unreadable and a maintenance nightmare.
Binning: Grouping Continuous Data into Buckets
Binning is like rounding, but for ranges. It groups continuous data into discrete 'buckets' to reduce noise. This turns messy user ages (21, 22.5) into clean categories (20-29) for analysis. The footgun: poor bin sizes can hide or create false trends.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles