Everything in LLMs & Generative AI, page 13
Tree of Thoughts: LLM Reasoning Beyond a Single Path
Tree of Thoughts (ToT) lets an LLM explore multiple reasoning paths at once, like a human brainstorming. It generates several 'thoughts' and pursues the most promising ones. This is crucial for planning tasks where one wrong turn fails.
Self-Consistency: Majority Rules for LLM Reasoning
Self-consistency makes an LLM solve a problem multiple ways, then picks the most common answer. It's like asking a committee of experts for their reasoning and taking a vote. This boosts accuracy on complex math and logic puzzles.
Least-to-Most Prompting: Solving Hard Problems Incrementally
Least-to-most prompting guides an LLM by breaking a hard problem into a sequence of simpler steps. It excels at complex math or logic where chain-of-thought fails, solving each subproblem using the answer to the previous one.
Chain-of-Thought Prompting: Making LLMs 'Show Their Work'
Chain-of-Thought (CoT) prompting gets better answers from LLMs by asking them to 'show their work.' It's best for complex reasoning like math problems or logic puzzles where breaking the problem down helps.

In-Context Learning: Teaching a GPT Without Retraining
In-context learning is like giving an LLM a cheat sheet in the prompt. You provide examples of a task, and the model follows the pattern for your new query without any permanent changes. Use it for one-off tasks like reformatting text or classifying sentiment.
Zero-Shot Prompting: Ask, Don't Show
Zero-shot prompting is asking an LLM to do a task without examples, relying on its pre-existing knowledge. Use it for simple tasks like basic translation or sentiment analysis where instructions are self-explanatory, but expect it to fail on complex tasks.
Prompt Engineering: Guiding LLMs to Better Answers
Prompt engineering means structuring instructions, context, constraints, and examples to make a model's output more useful for a task. For example, asking for JSON with a schema and one valid example can improve format consistency, but prompting alone cannot guarantee accuracy.

Tensor Parallelism: Split Layers, Not Just Models
Tensor Parallelism splits a single large model layer, like a weight matrix, across multiple GPUs to run in parallel. This is crucial for inference with models whose layers exceed a single GPU's VRAM.
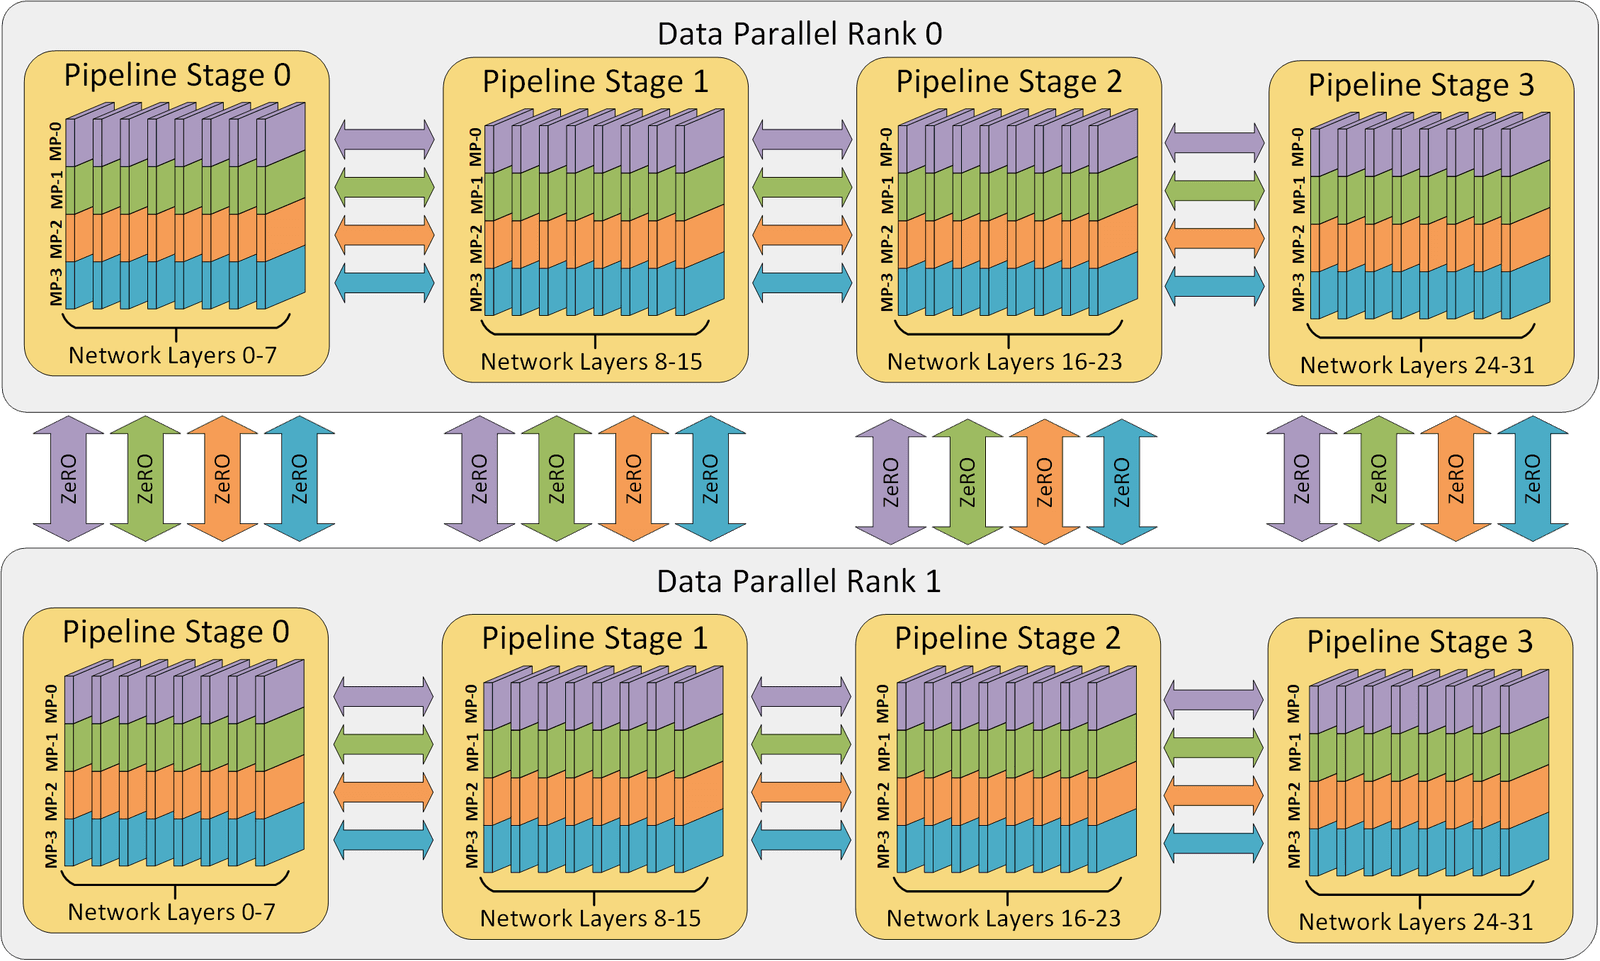
Pipeline Parallelism: An Assembly Line for Your Model
Think of training a huge model like an assembly line. Pipeline parallelism splits a model's layers into stages across multiple GPUs, allowing you to train models too large for one device.
What is a Large Language Model (LLM)?
An LLM is a neural network trained on vast text data to process and generate human-like language. It's the core technology behind chatbots, enabling them to generate, summarize, and translate text. Its reliability depends entirely on its training data.
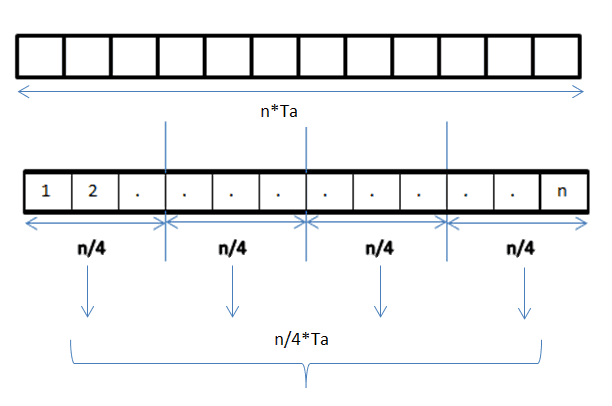
Data Parallelism: One Task, Many Data Chunks
Data parallelism splits a huge dataset across multiple processors, each running the same task on its own chunk. It's how large models are trained on massive datasets, with each GPU handling a different batch of data.

Learning Rate Scheduling: A Gearbox for Model Training
Think of a learning rate schedule as a training 'gearbox,' starting fast and slowing for precision. It's used when fine-tuning large models to adapt them without breaking them.
AdamW: Decoupling Weight Decay for Better Generalization
AdamW fixes a flaw in the Adam optimizer by decoupling weight decay from the gradient update, improving model generalization. It's a go-to for training large networks like Transformers. The footgun is thinking it's the same as Adam with L2 regularization.
Mixed-Precision Training: Faster Training with Less Memory
Mixed-precision training is like using rough estimates (FP16) for most math and a calculator (FP32) for critical steps. This speeds up deep learning on GPUs by cutting memory use, but naively switching can cause training to fail as small gradients vanish.
Common Crawl: A Free Snapshot of the Entire Web
Common Crawl is a public library of the internet—a massive, free snapshot of web text and links. It's the raw material for training many LLMs and for academic research on web-scale data. The footgun: it's unfiltered, containing everything from facts to spam.

Causal Language Modeling: The Autocomplete Engine
Causal Language Modeling is like a powerful autocomplete, predicting the next word based only on what came before. It's the engine for text generation in chatbots, creative writing tools, and coding assistants. The footgun: it can't see future words.
Transformer: The Final Linear and Softmax Layers
A Transformer's final linear layer acts as a classifier, converting the decoder's output vector into raw scores (logits) for every possible word. The softmax function then turns these scores into probabilities, allowing the model to pick the most likely next…
Transformer Preprocessing: From Text to Tensors
Transformers don't read text; they read numbers. A tokenizer is the translator, converting sentences into numerical tensors the model understands. This is the mandatory first step for any NLP task. The footgun is using a tokenizer that doesn't match the model.
Cross-Attention: How Models Connect Two Ideas
Cross-attention lets a model, like a translator, focus on relevant parts of an input (e.g., a sentence) to generate an output (the translation). It's used in machine translation and image captioning. The footgun is confusing it with self-attention.
Residual Connections & Layer Norm: The Transformer's Stabilizers
Residual connections are shortcuts that let information bypass layers, while Layer Normalization rescales a layer's outputs. Together, they prevent training from breaking in very deep networks like Transformers, enabling signals to flow without vanishing.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles