Intermediate everything in MLOps & Infrastructure, page 6
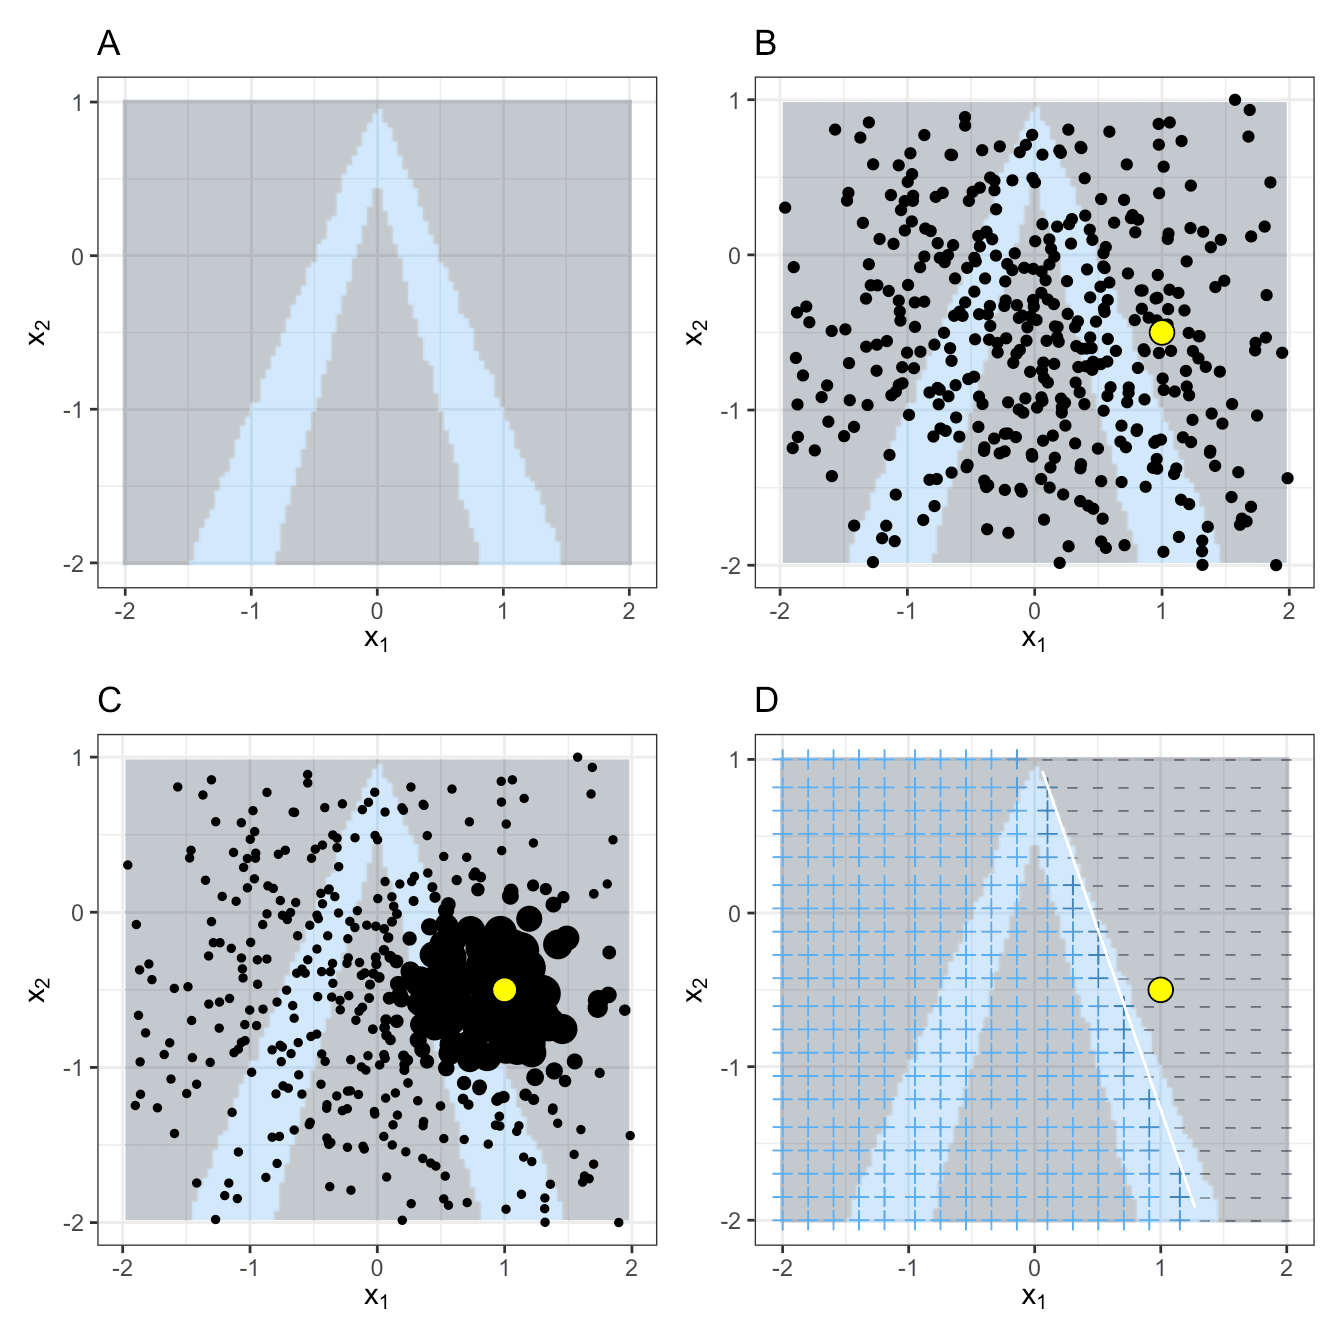
LIME: Explaining Single Predictions from Any ML Model
LIME explains a single prediction from any 'black box' model by approximating it with a simpler model that's only accurate locally. Use it to see why a specific user churned.
SHAP: Explaining Black Box Model Predictions
SHAP explains a model's prediction by treating features as players in a game and fairly distributing credit for the outcome. Use it to understand why a specific loan was denied or an image was misclassified. The footgun: SHAP explains the model, not reality.

ML Threat Modeling: Assume Your Data Is Compromised
Threat modeling for ML means assuming your training data is already compromised. This is crucial for services using public or user-supplied datasets. The main footgun is trusting data sources, as data poisoning can silently corrupt your model's behavior.
The MLOps Maturity Model: A Roadmap for Growth
The MLOps Maturity Model is a roadmap from manual chaos to automated ML systems. Use it to assess your team's current state and plan incremental improvements.

Pipeline Step Caching: Don't Recompute What You Don't Have To
Pipeline step caching is memoization for your ML infrastructure, saving time and money by reusing previous results. It's used in MLOps pipelines when inputs and code haven't changed. The footgun: the cache is scoped to one pipeline and a timeout, not globally.
Argo Workflows: Run Complex Jobs on Kubernetes
Think of Argo Workflows as a script runner for Kubernetes, where each command is a container. It runs multi-step jobs like CI/CD or ML pipelines. The footgun is treating it like a full CI server; it's just an engine and lacks features like Git polling.
Vertex AI Pipelines: Orchestrating ML Workflows
Think of it as an assembly line for your machine learning models, automating everything from data prep to deployment. Use it to build reproducible, production-grade ML systems on Google Cloud.
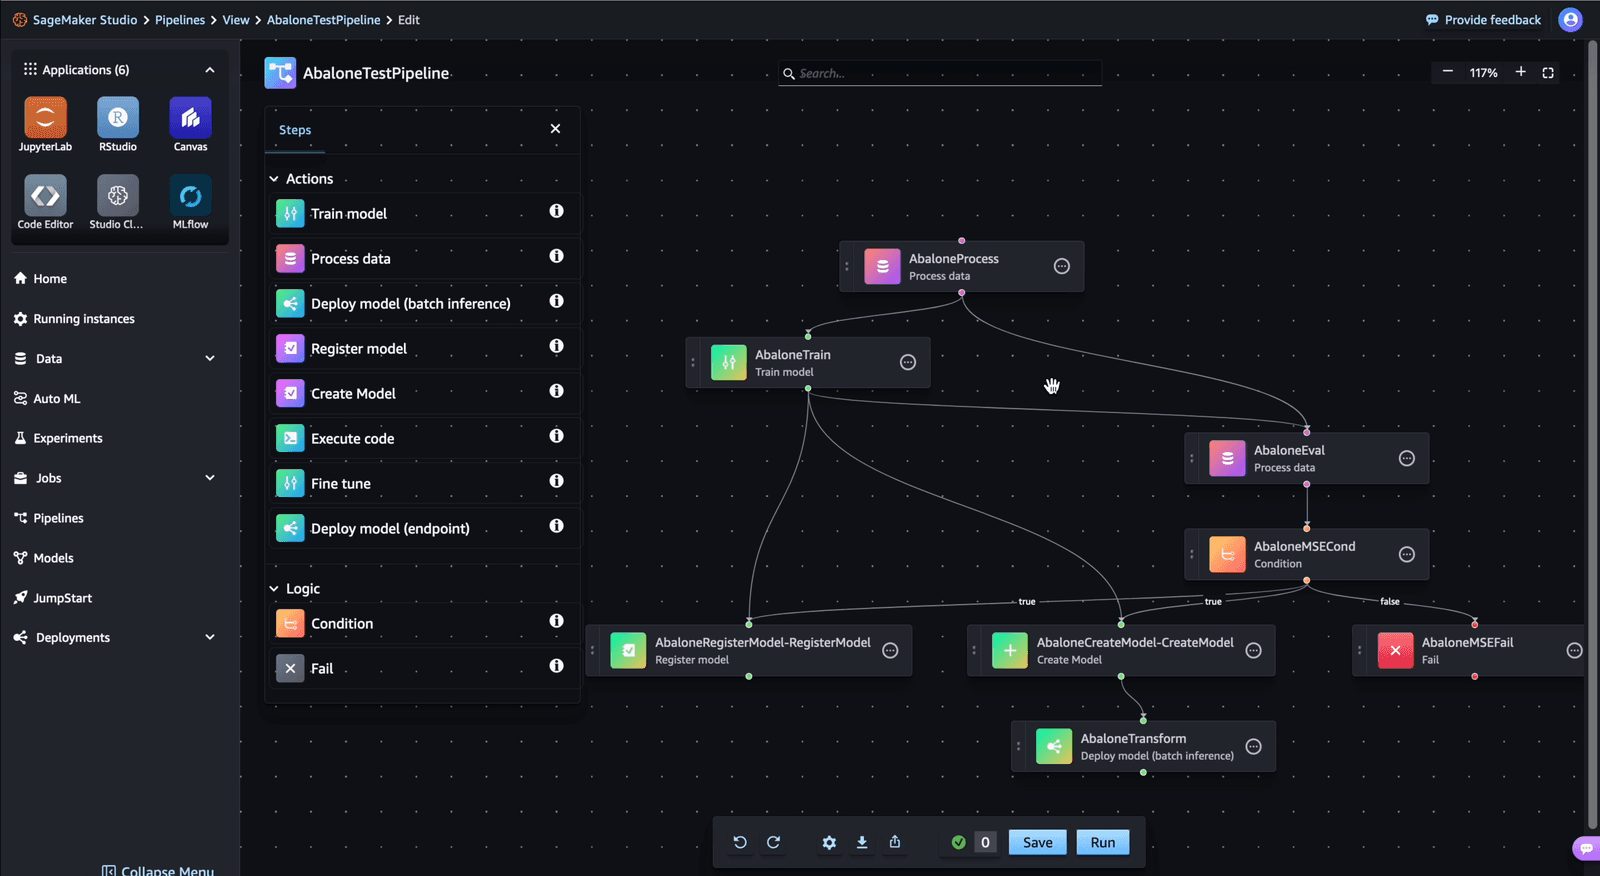
Amazon SageMaker Pipelines: Repeatable ML Workflows
Think of SageMaker Pipelines as a CI/CD pipeline for ML models, automating workflows from data prep to deployment. Use it for reproducible training and automated retraining.
TensorFlow Extended (TFX): Production ML Pipelines
TFX is an end-to-end platform for building production ML pipelines, like an assembly line for your models. It automates data validation, training, analysis, and serving. The footgun: TFX is not one tool, but a suite of libraries you must learn and connect.

Population Stability Index (PSI): Quantifying Data Drift
The Population Stability Index (PSI) gives you a single number to quantify data drift between training and live data. It's used in MLOps to monitor model health, especially in finance. The footgun is ignoring a high PSI, which signals silent prediction decay.
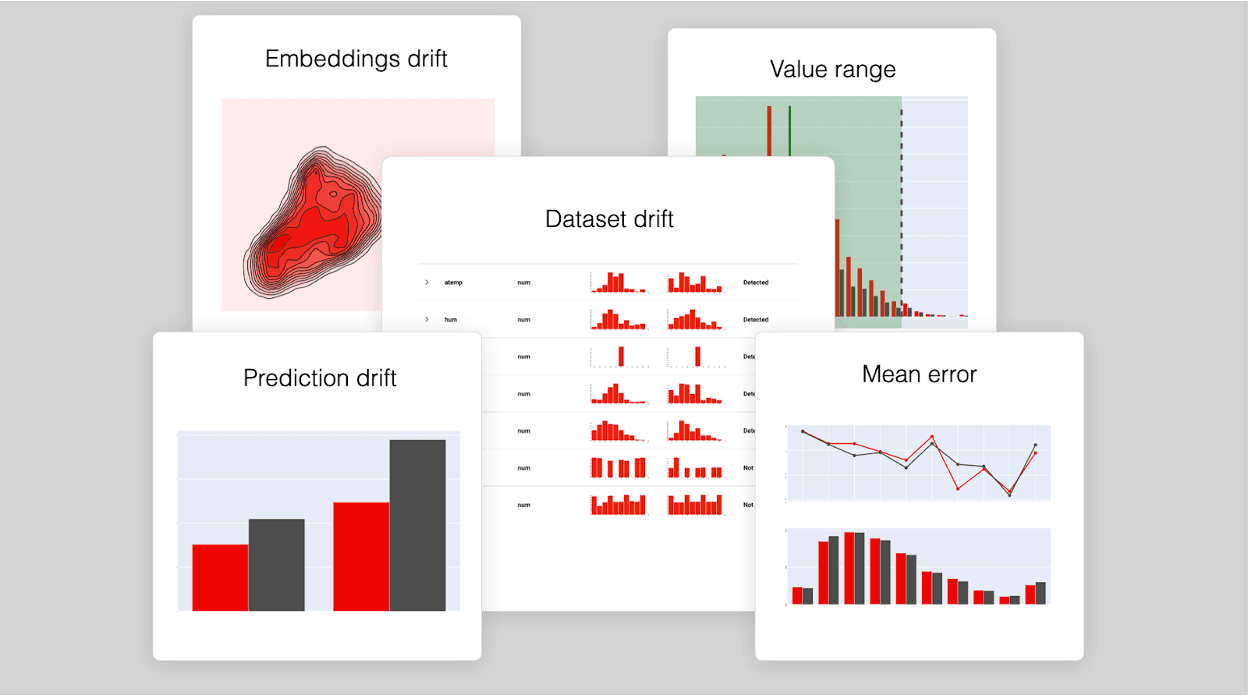
ML Monitoring Dashboards: Your Model's Health Chart
An ML monitoring dashboard is a health chart for your production model, showing how its performance decays. It tracks silent failures like data drift or concept drift, where user behavior changes and makes your model obsolete.
BentoML: Packaging Models for Production APIs
BentoML is a standardized shipping container for your ML models, packaging them into production-ready API endpoints. Use it to deploy LLMs or RAG systems without managing complex infrastructure. Its focus is purely on inference, not model training.
Autoscaling ML Inference Endpoints
Autoscaling matches your ML model's compute to real-time demand, like an elastic container for your inference service. It handles spiky traffic for online endpoints, scaling up for peaks and down to save costs.

Inference Batching: Grouping Requests for Throughput
Think of inference batching as a carpool for your ML model. Instead of sending each request in its own car, you wait a few microseconds to fill a bus, dramatically improving GPU efficiency.
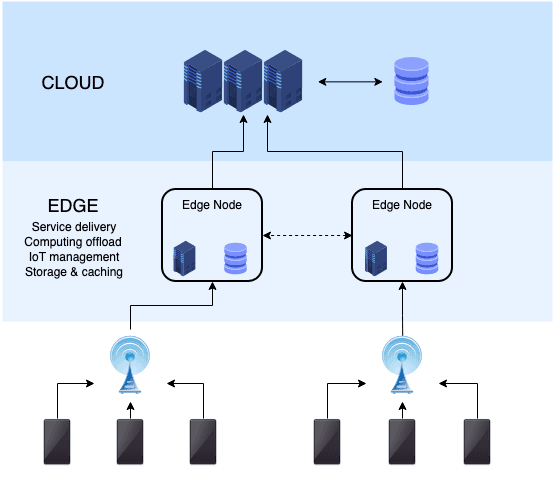
Edge AI: Running Models Where the Data Is
Edge AI runs machine learning models directly on devices, not in a distant cloud. This enables real-time, offline applications like smart cameras or voice assistants. The footgun is underestimating device hardware limits; models must be small and efficient.
Streaming Inference: Real-Time Model Predictions
Streaming inference makes predictions on data in-flight, not from a database. It's for real-time recommendations or fraud detection where millisecond decisions are critical. The footgun is assuming a single server can handle the load; you must build for scale.
Serverless Inference: Run ML Models Without Managing Servers
Serverless inference treats ML prediction like a function call, abstracting away servers. You pay for compute time per prediction, not for idle infrastructure.
Automating MLOps with GitHub Actions
Treat your ML workflow like any other CI/CD pipeline. GitHub Actions automates MLOps tasks—like training, testing, and deployment—triggered by events in your repo. Use it to run validation on PRs or deploy models on merge.
Elastic Training: Training Models on Unreliable Hardware
Elastic Training lets ML training jobs survive worker nodes being added or removed mid-run. It's like a construction crew that adapts to a changing number of workers, making it ideal for training large models on cheap but unreliable cloud spot instances.
Slurm: The Job Scheduler for Supercomputers
Slurm is the reservation system for a shared supercomputer, queuing up jobs and assigning them to available nodes. It's the backbone of high-performance computing clusters in science and ML.
We are hiring for this. Every open role lists the topics its interview covers, so you can prepare for the real thing rather than guessing.
See open roles